FLUX.1 Kontext takes images as input, not just text prompts
- Source
- x.com
- Date

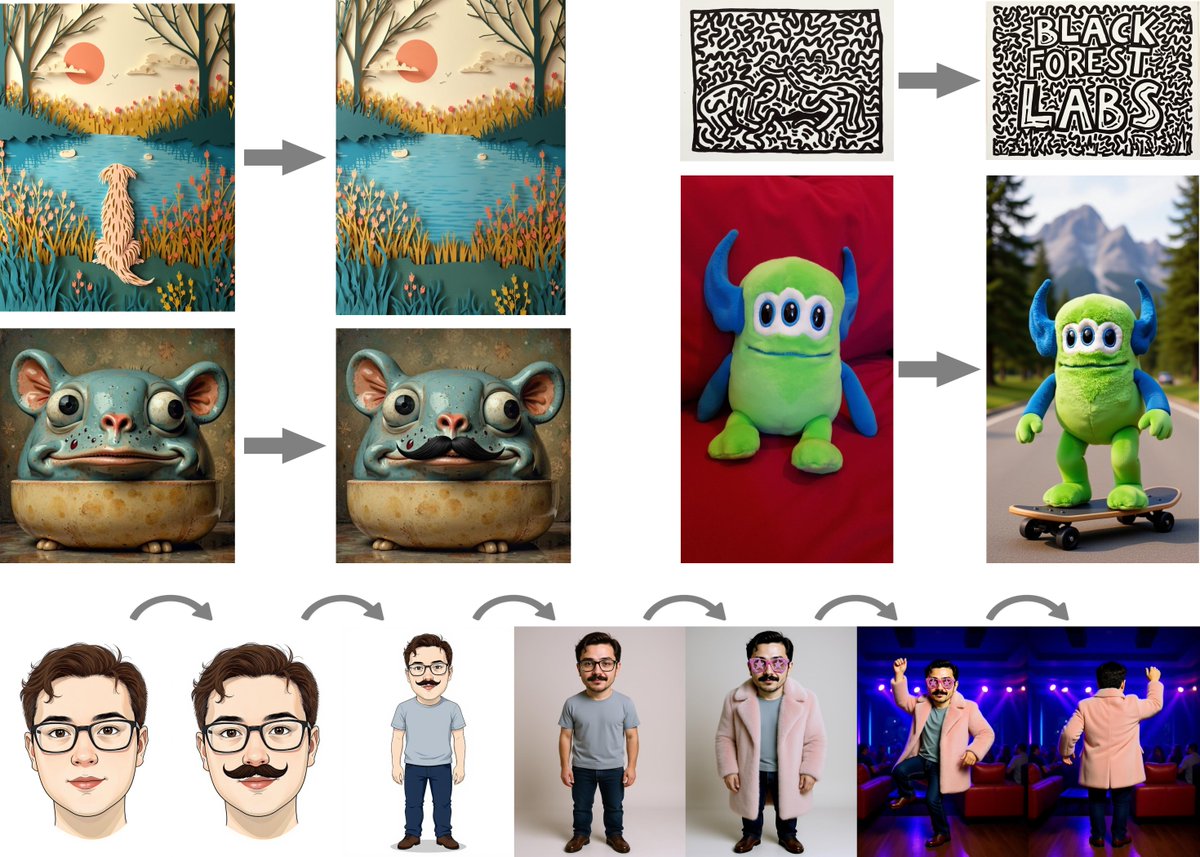
Today we're releasing FLUX.1 Kontext - a suite of generative flow matching models that allow you to generate and edit images. Unlike traditional text-to-image models, Kontext understands both text AND images as input, enabling true in-context generation and editing.

Four things make Kontext special: Character consistency: Preserve elements across scenes Local editing: Target specific parts without affecting the rest Style reference: Generate new scenes in existing styles Interactive speed: Iterate with minimal latency
Two models available: FLUX.1 Kontext [pro]: Pioneer for fast iterative editing. First model to build upon previous edits while maintaining characters, identities, styles & features consistent across scenes FLUX.1 Kontext [max]: Maximum performance at high speed – improved prompt adherence, typography & premium consistency
🔓 FLUX.1 Kontext [dev]: Open-weights variant of our most advanced generative image editing model. Available in private beta.
Context
FLUX.1 Kontext lets an existing image carry information that would be difficult to specify entirely in words. Black Forest Labs describes a workflow in which users provide an image and a written editing instruction, then build further changes on the result. The release article identifies preserving a reference character across scenes and changing particular parts of an image as core capabilities.
This makes the image itself part of the instructions for the next version. Repeated editing still has a limit: the same article documents visual degradation after six successive edits in one example.
- open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
Checking sign-in…
Loading comments…