Fine-tuning a 350M Model for Better Structured Outputs in 100 GRPO Steps
Source
huggingface.co
Date
Context
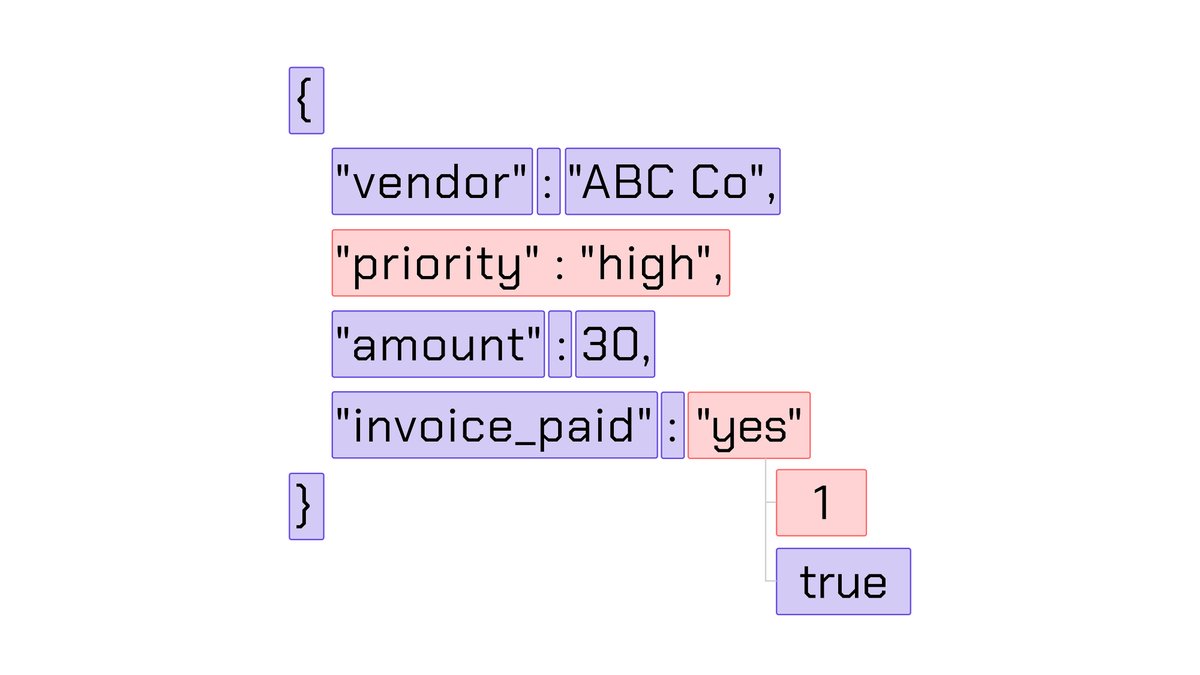
A small model can learn to follow output formats better through targeted rewards. A published experiment fine-tuned Liquid AI's 350-million-parameter LFM2.5 model for 100 steps, rewarding parseable output, correct field counts and compliance with a specified data structure. On the same evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → setup, its IFStruct pass rate rose from 22.6% to 29.7%. Most progress came from JSON, which rose from 18.0% to 31.9%; YAML barely changed. The result supports targeted improvement in machine-readable output, with substantial failures still remaining. Experiment and results.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
LoRA — A cheap way to fine-tune a model by training a small add-on layer instead of changing all of the model's weights.