On-policy distillation: RL's error correction at SFT prices
- Source
- x.com
- Date

Our latest post explores on-policy distillation, a training approach that unites the error-correcting relevance of RL with the reward density of SFT. When training it for math reasoning and as an internal chat assistant, we find that on-policy distillation can outperform other approaches for a fraction of the cost.
Context
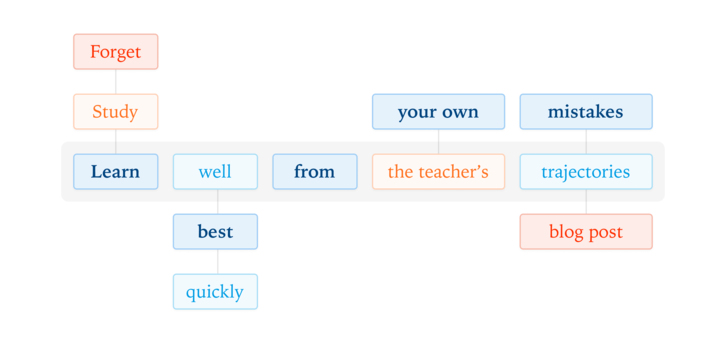
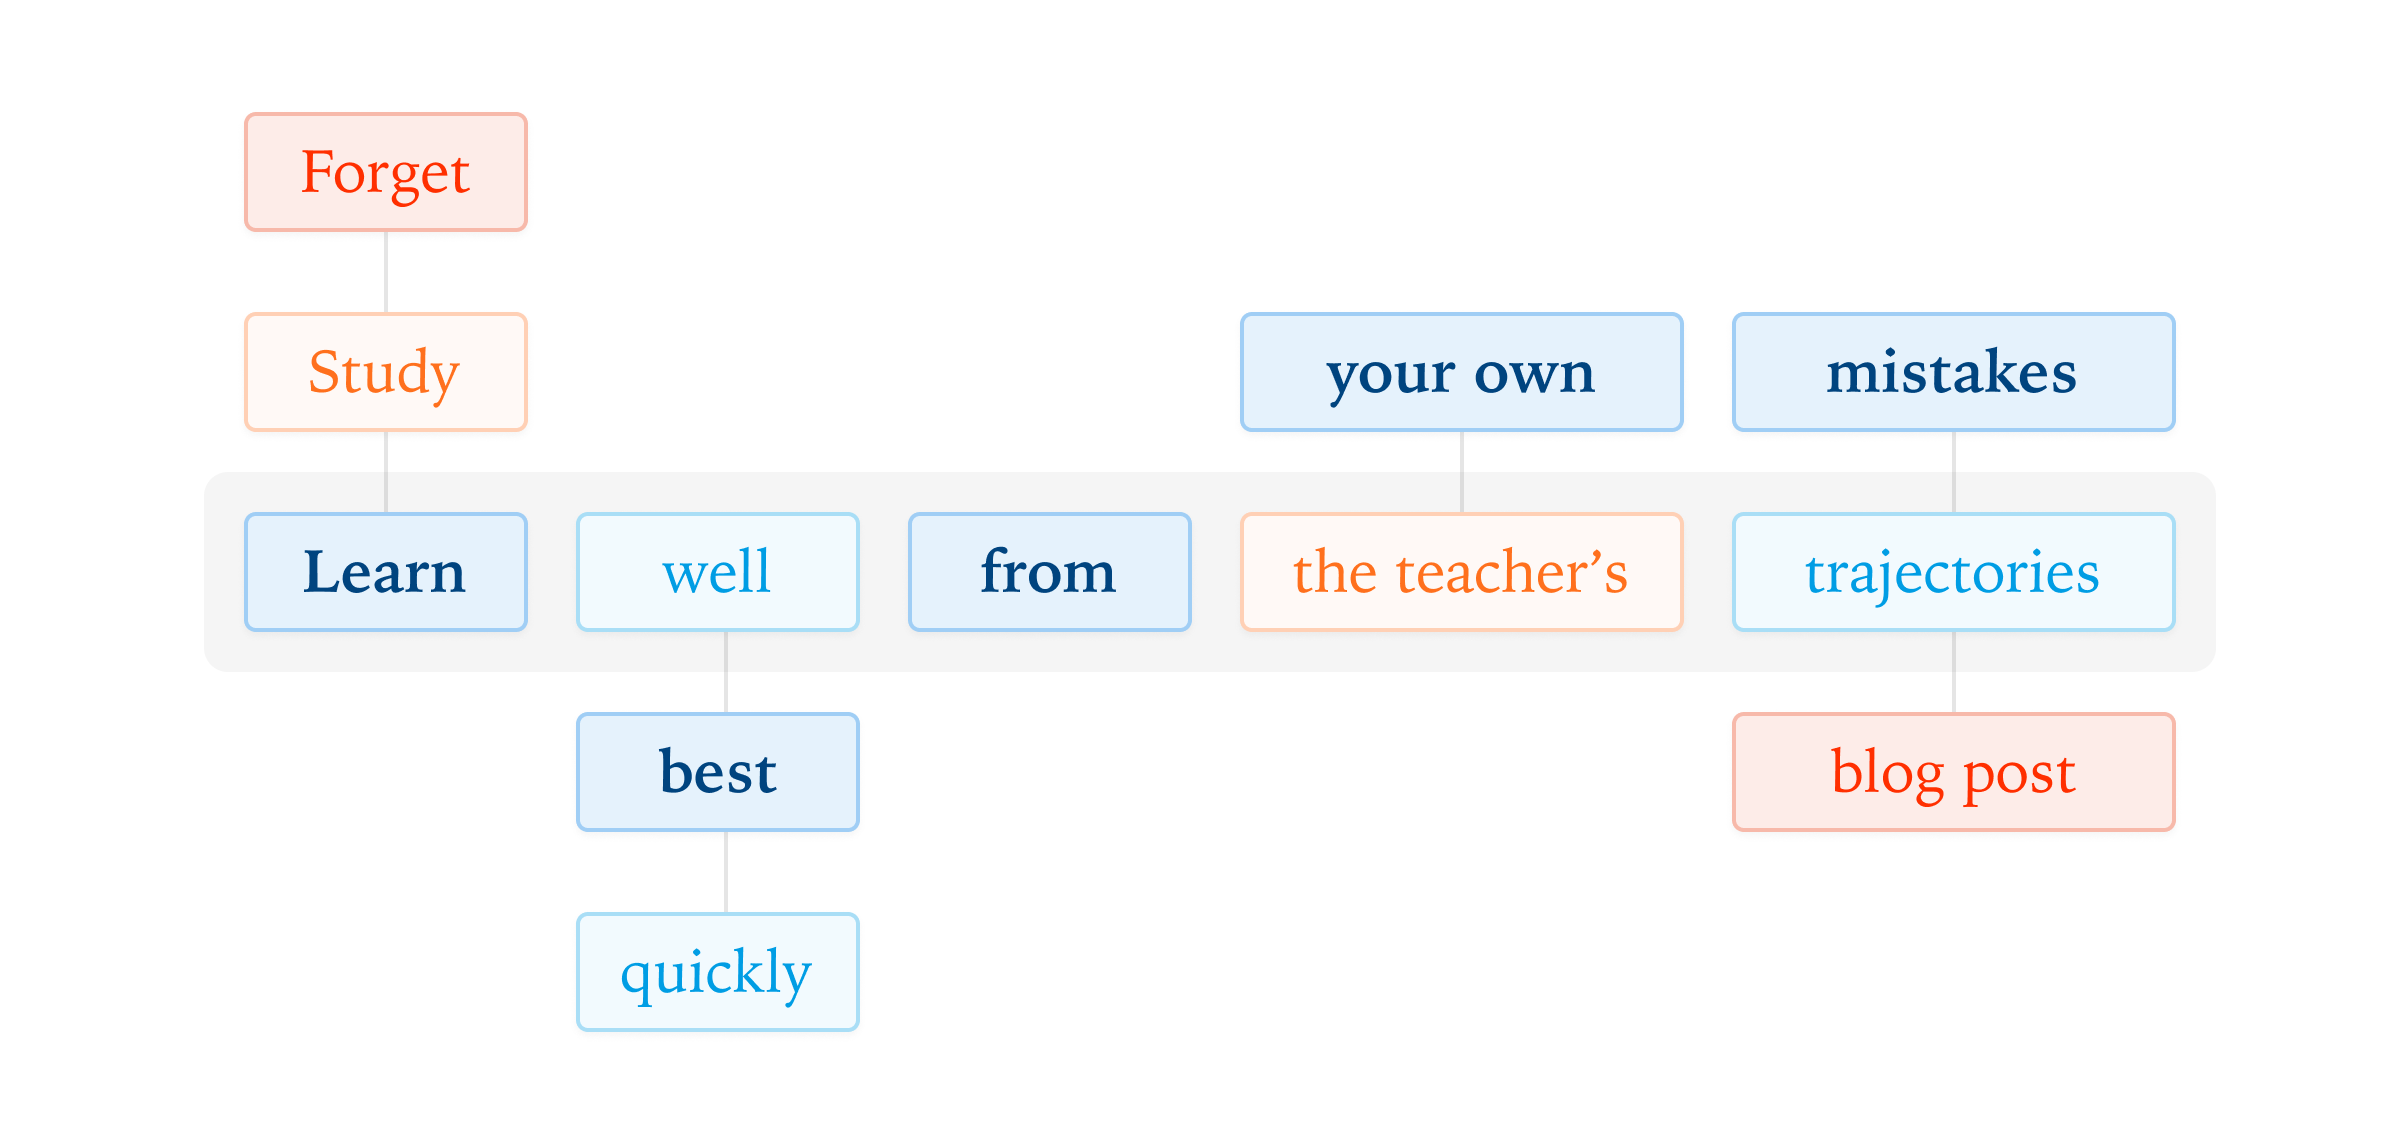
A smaller model can learn from feedback on its own attempted answers. In Thinking Machines' on-policy distillation approach, the student generates a response and a stronger teacher supplies feedback for each generated text unit, conditioned on what the student has already written. This exposes the teacher to the student's actual mistakes. Learning only from polished teacher answers can leave those situations uncovered; grading only the final answer provides much less detailed feedback.
The lab reports improved training efficiency in its math-reasoning experiments. The mechanism explains the potential saving: each attempt supplies many local learning signals, while keeping training focused on the paths the student actually takes. Experiment details.
- distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.

Checking sign-in…
Loading comments…