RoFormer: Enhanced Transformer with Rotary Position Embedding
Source
arxiv.org
Author
Jianlin Su et al.
Date
Context
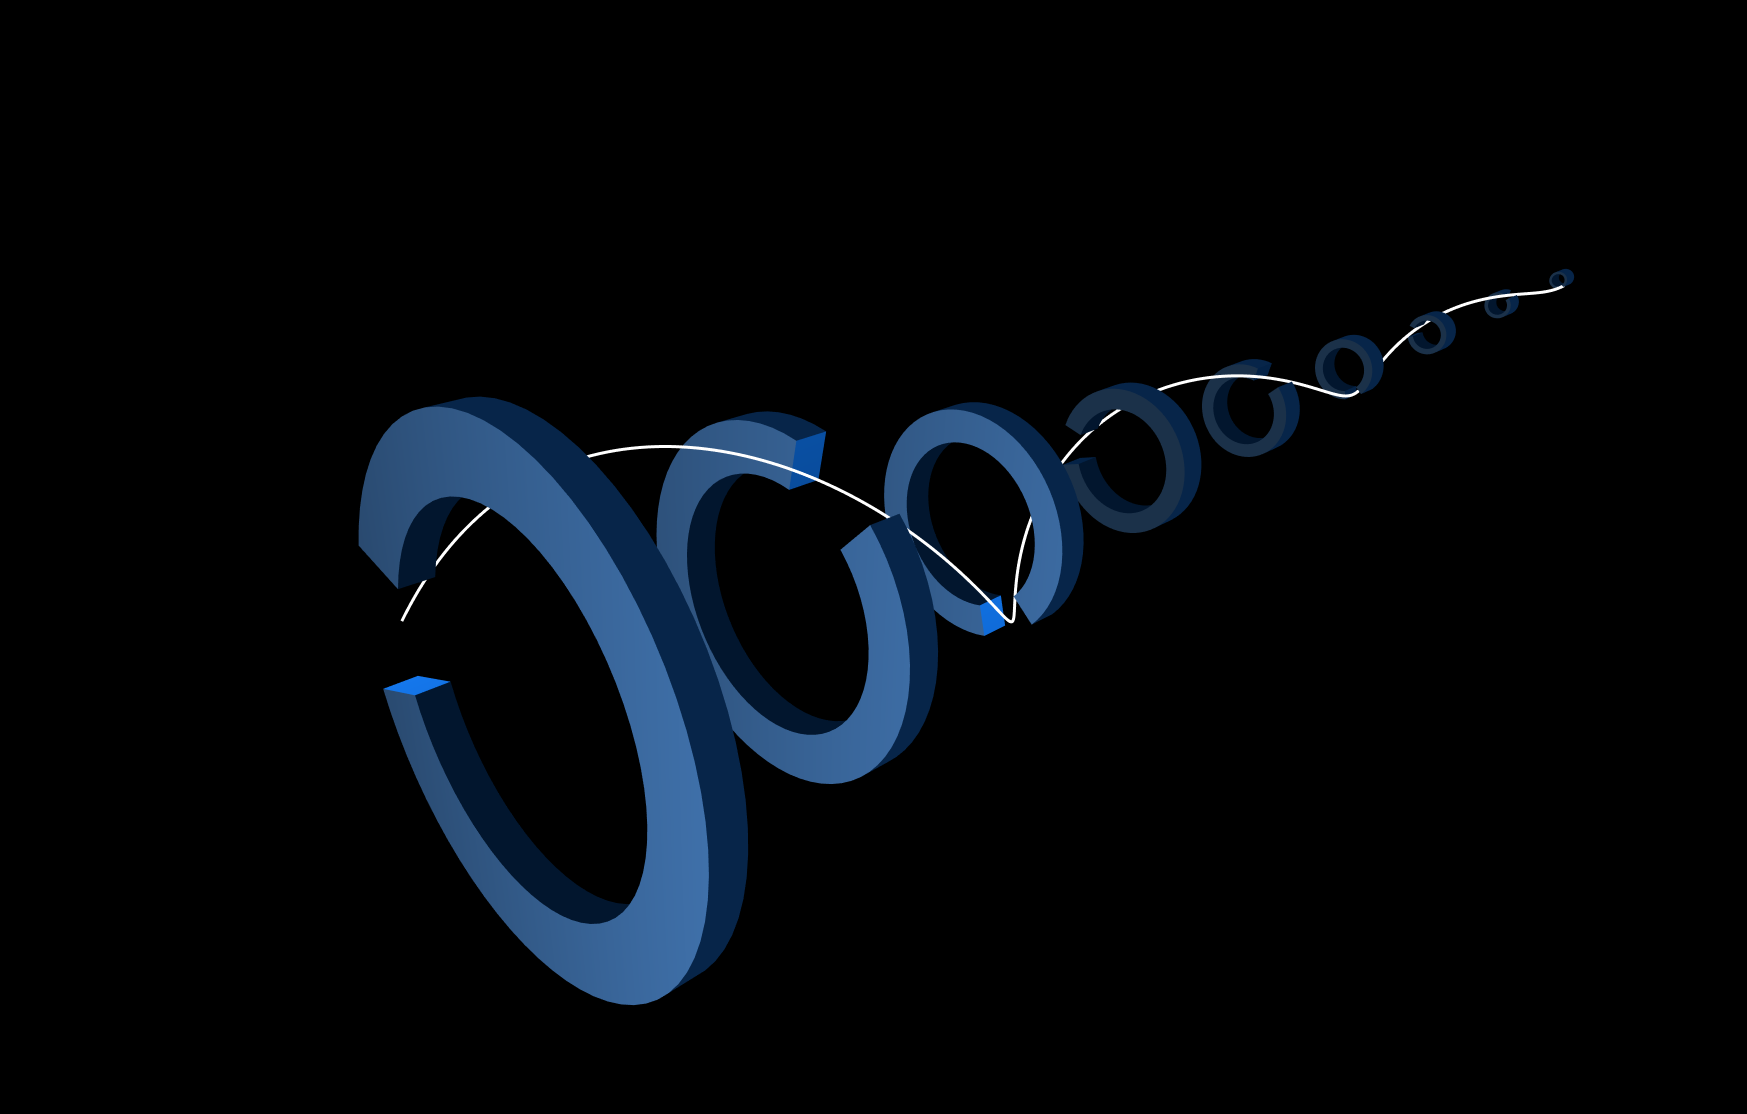
RoFormer addresses how a LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition → represents the order and spacing of text. Its Rotary Position embeddingA list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.Full definition →, or RoPE, rotates the numerical representations used when attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → compares two text positions. Each rotation depends on position, making the comparison also depend on the distance between them. This puts relative position directly into the attention calculation. The paper's derivation explains that mechanism.
It revisits a problem already present in the original Transformer, which added position information to its input representations. RoPE offers a different mathematical treatment of order; flexibility in sequence length alone does not establish reliable performance on arbitrarily long text. Original positional encoding.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.