Halv cut AI agent cost by 57.1% using Jev
- Source
- halv.ai
- Author
- villaspedro
- Date
Context
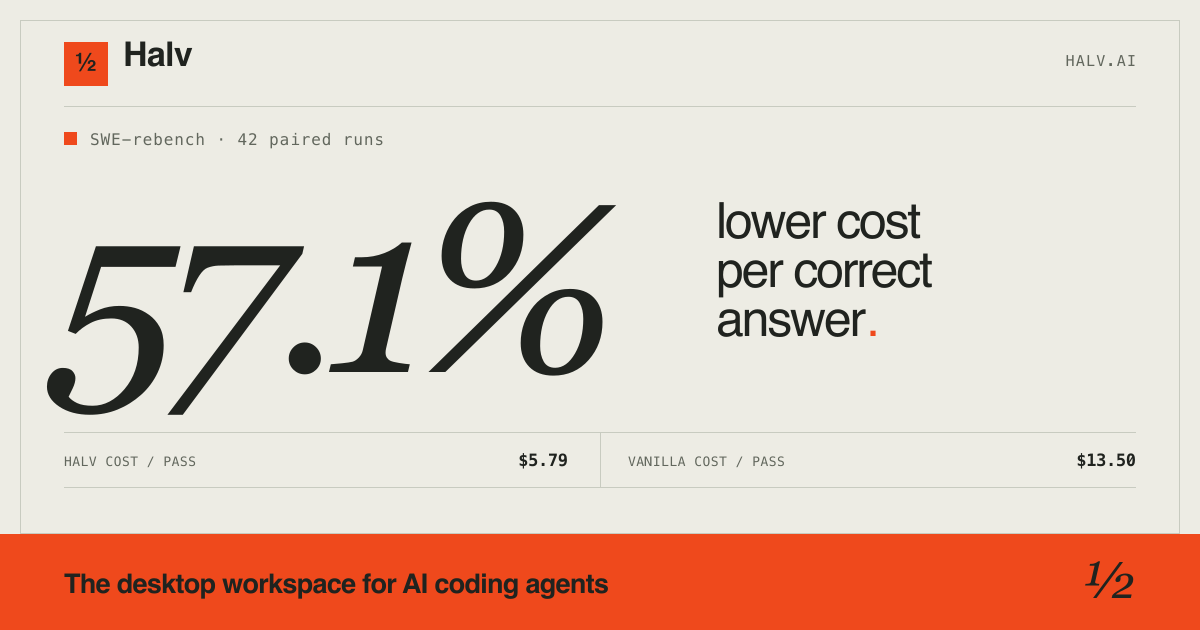
Halv's interim benchmark report compares its routed coding workflow with the same Codex coding working through a single model alone. Across 14 repository tasks repeated three times, each side passed 25 of 42 attempts. Halv recorded $144.67 in estimated model costs versus $337.50, a 57.1% reduction, while using about 3.49 times as many total .
The experiment changed several things together: which worker model handled each task, delegation, and tools for managing code and . It therefore supports a result for that combined workflow, without isolating the contribution of its JEV router. Equal overall pass counts also concealed a regression on one task, which fell from three passes to one. The costs are token-based estimates rather than invoices, leave out the subscription price, and exclude infrastructure-invalid attempts and runs from a rolled-back policy experiment, so they are not the complete experiment bill. Methods and exclusions.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.

Checking sign-in…
Loading comments…