Accelerating Mamba-2 with High-Performance Forward Pass Kernels in NVIDIA CUDA Tile
- Source
- developer.nvidia.com
- Author
- Tanya Lenz
- Date
Context
Engineers at the trading firm Jane Street, working with NVIDIA, rewrote the forward pass of Mamba-2, a sequence model that carries a fixed-size hidden state from to token like a recurrent network, as GPU kernels in cuTile, NVIDIA's Python language for writing kernels in terms of tiles rather than individual threads (NVIDIA Technical Blog). The core problem is that stepping through tokens one at a time is fine for generation but too slow for training and prefill. The post's approach splits a sequence into chunks and uses a formula that jumps the hidden state from the start of one chunk to the next with a single matrix multiplication, which is the kind of work Tensor Cores accelerate. The per-token decay is handled as cumulative sums in log space, and the authors note that the exponentials they keep are never of positive numbers, which keeps the computation numerically stable.
That becomes three kernels: one computes the cumulative decay sums within each chunk, one walks across chunks to produce each chunk's starting hidden state, and one computes the outputs for every chunk in parallel, fusing the carried-state term, the causally masked interaction matrix and the skip connection so the intermediate matrix stays in registers instead of global memory. Further tuning included compiler latency hints, rearranging operands to suit the Blackwell Tensor Core's memory layout, a transposed memory layout for contiguous loads, and an autotuner that picks settings per input shape. On a single B300 GPU, the authors report the cuTile forward pass is 1.14x to 1.82x faster than an open-source Triton implementation of Mamba-2, with larger gains at longer sequences and bigger state sizes. They stress these are kernel-level numbers; end-to-end training speed also depends on the backward pass, which a follow-up post is meant to cover. The kernels are available through NVIDIA's TileGym.
- Jane Street and NVIDIA split the Mamba-2 forward pass into three cuTile kernels: a per-chunk cumulative sum of the decay term, a sequential loop that carries hidden state between chunks, and a fused output kernel.
- Working in log-space turns Mamba-2's chained decay multiplications into cumulative sums, so the hidden-state jump across a chunk stays a Tensor Core matmul; the kept exponentials are of negative values, so they cannot overflow.
- The output kernel fuses the carried-state term, the causally masked interaction matrix and the skip connection, keeping that matrix in registers instead of writing it to global memory as a direct PyTorch version would.
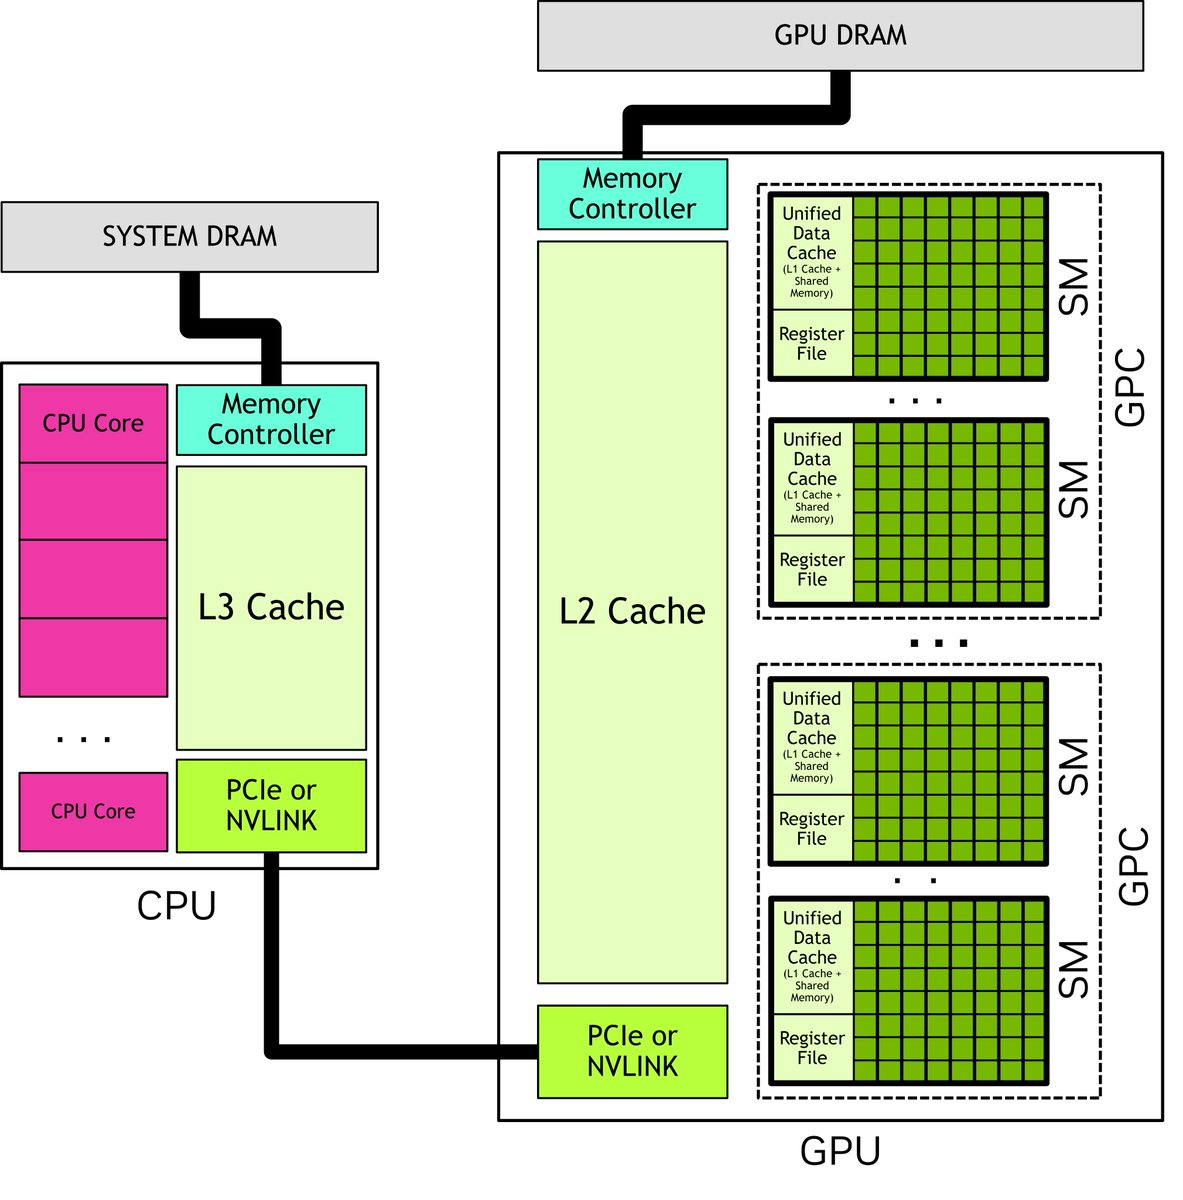
- On Blackwell, MMA operand A can live in Tensor Memory but operand B must sit in Shared Memory, so the authors transpose the product to route the fused operand to A and relieve shared-memory contention.
- On a single B300, the cuTile forward pass ran 1.14x to 1.82x faster than the open-source Triton Mamba-2 kernel, with larger gains at longer sequences and state sizes; these are kernel-level results, not end-to-end training.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
 articleScale Agentic Coding Workflows with Meta’s Muse Spark Open on NVIDIA GB300 NVL72
 articleOptimizing Agent Reliability and Tool Calling Efficiency for Chip Design Using NVIDIA NeMo Gym
 articleNVIDIA Run:ai Is Now Open Source as Part of NVIDIA DSX AI Factory Platform
 articleBuild Applications on NVIDIA BlueField Faster with NVIDIA DOCA Agent Skills
Checking sign-in…
Loading comments…