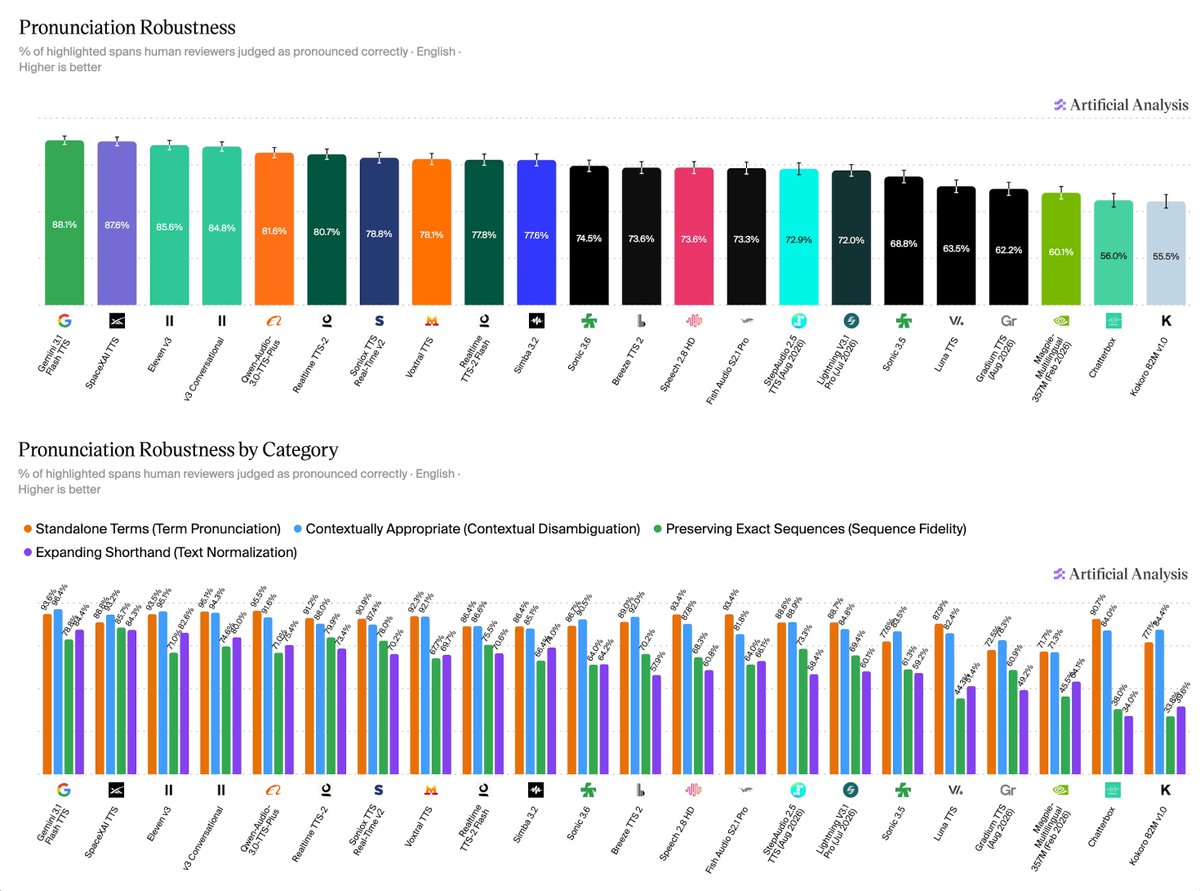
Shows how natural-language style captions plus LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition → character profiling give TTS per-character voices in long-form audio. It is a usable pattern for anyone building multi-speaker narration.
Key takeaways · AI-distilled
Audible's team says conventional TTS struggles with audiobooks because it reads single utterances with little story context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →, so it fails to switch style between characters and can voice a character differently in chapter 1 than in chapter 10.
To caption expressive speech at scale, the team pairs the controllable-TTS model with a reverse 'speech captioner' that describes prosody from audio, and uses each to generate training data for the other in an iterative synthetic-data flywheel.
BookLLM, built on off-the-shelf LLMs, profiles characters and attributes every passage to a speaker. On 25 English and Spanish books it identified who speaks where with 97% and 94% accuracy against two human annotators.
Each prominent character gets one fixed profile from a curated voice catalogue, picked to maximize contrast, while minor characters fall back to the narrator. Fixing the profile once per book is what keeps a voice consistent from start to finish.
Per-line captions such as 'whispering nervously' act as stage directions. Audible reports the pipeline raised dialogue differentiation by 3.7 MUSHRA points, with statistically significant gains for eight of ten voices in English and Spanish tests.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.