Efficient Memory Management for Large Language Model Serving with PagedAttention
Source
arxiv.org
Author
Woosuk Kwon et al.
Date
Context
PagedAttention addresses a memory-management obstacle to serving many language-model requests together. Each request needs a growing cache of attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → data, and wasted space or duplicated data can limit how many requests fit in memory. The 2023 paper introduces a paging-based approach and implements it in vLLM, allowing more flexible allocation and sharing of that cache. The authors report two to four times the throughput of FasterTransformer and Orca at comparable latency in their evaluations. The improvement concerns how much work the server handles at once, rather than an equivalent speedup for every individual answer.
Terms in this piece · Glossary
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
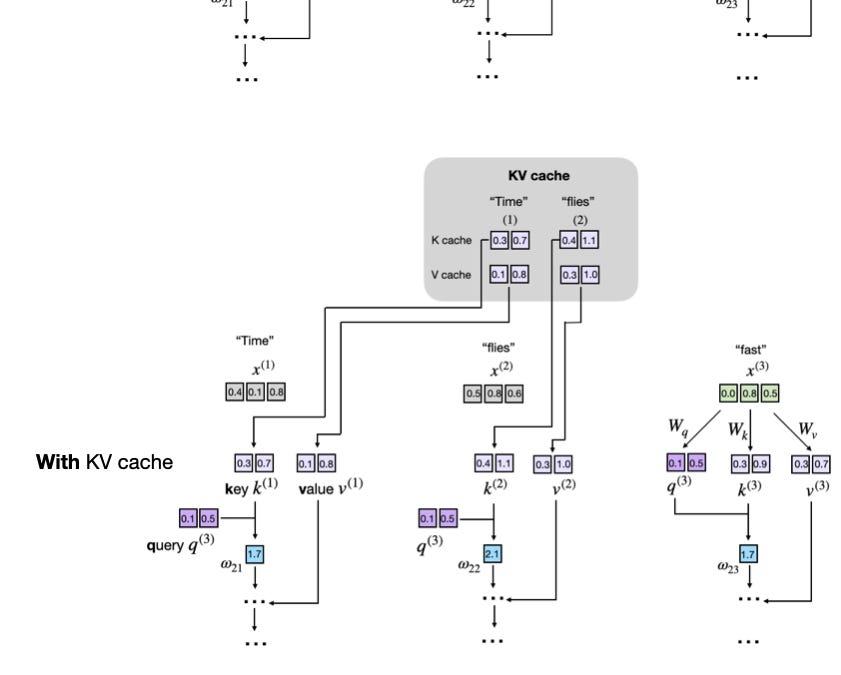
KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.