d-Matrix Adopts NVIDIA NVLink Fusion for Rack-Scale XPU Deployment
- Source
- blogs.nvidia.com
- Author
- Jesse Clayton
- Date
Context
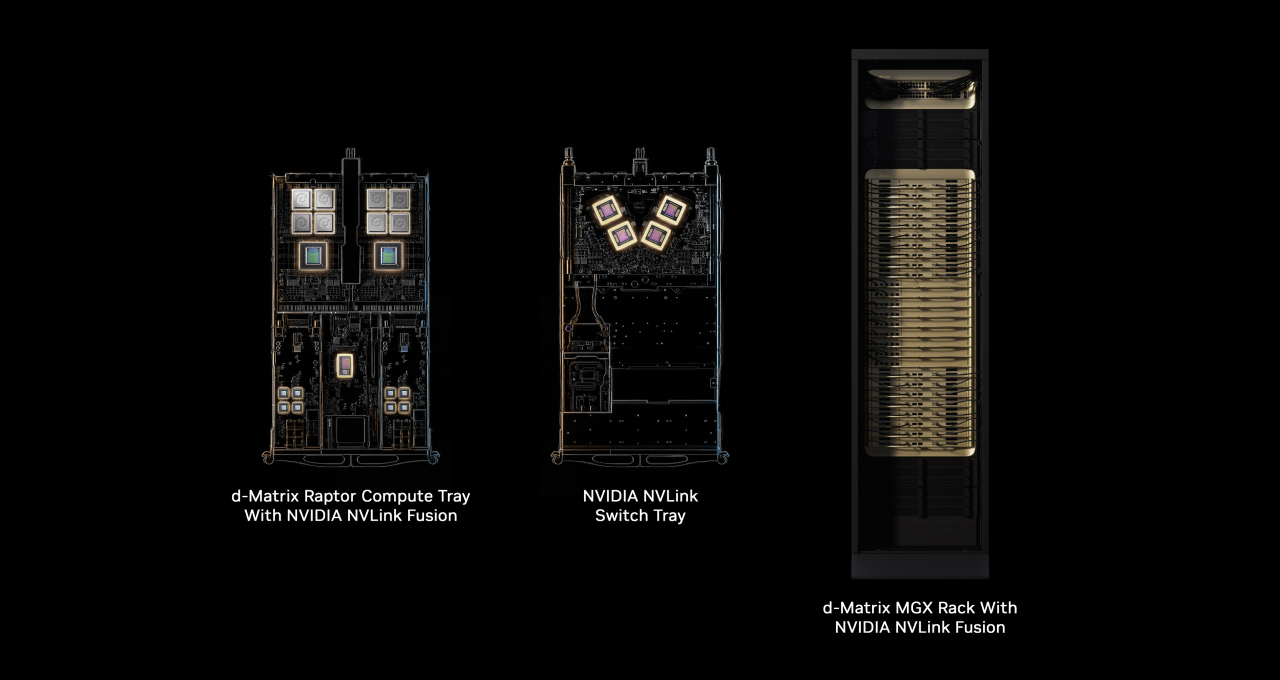
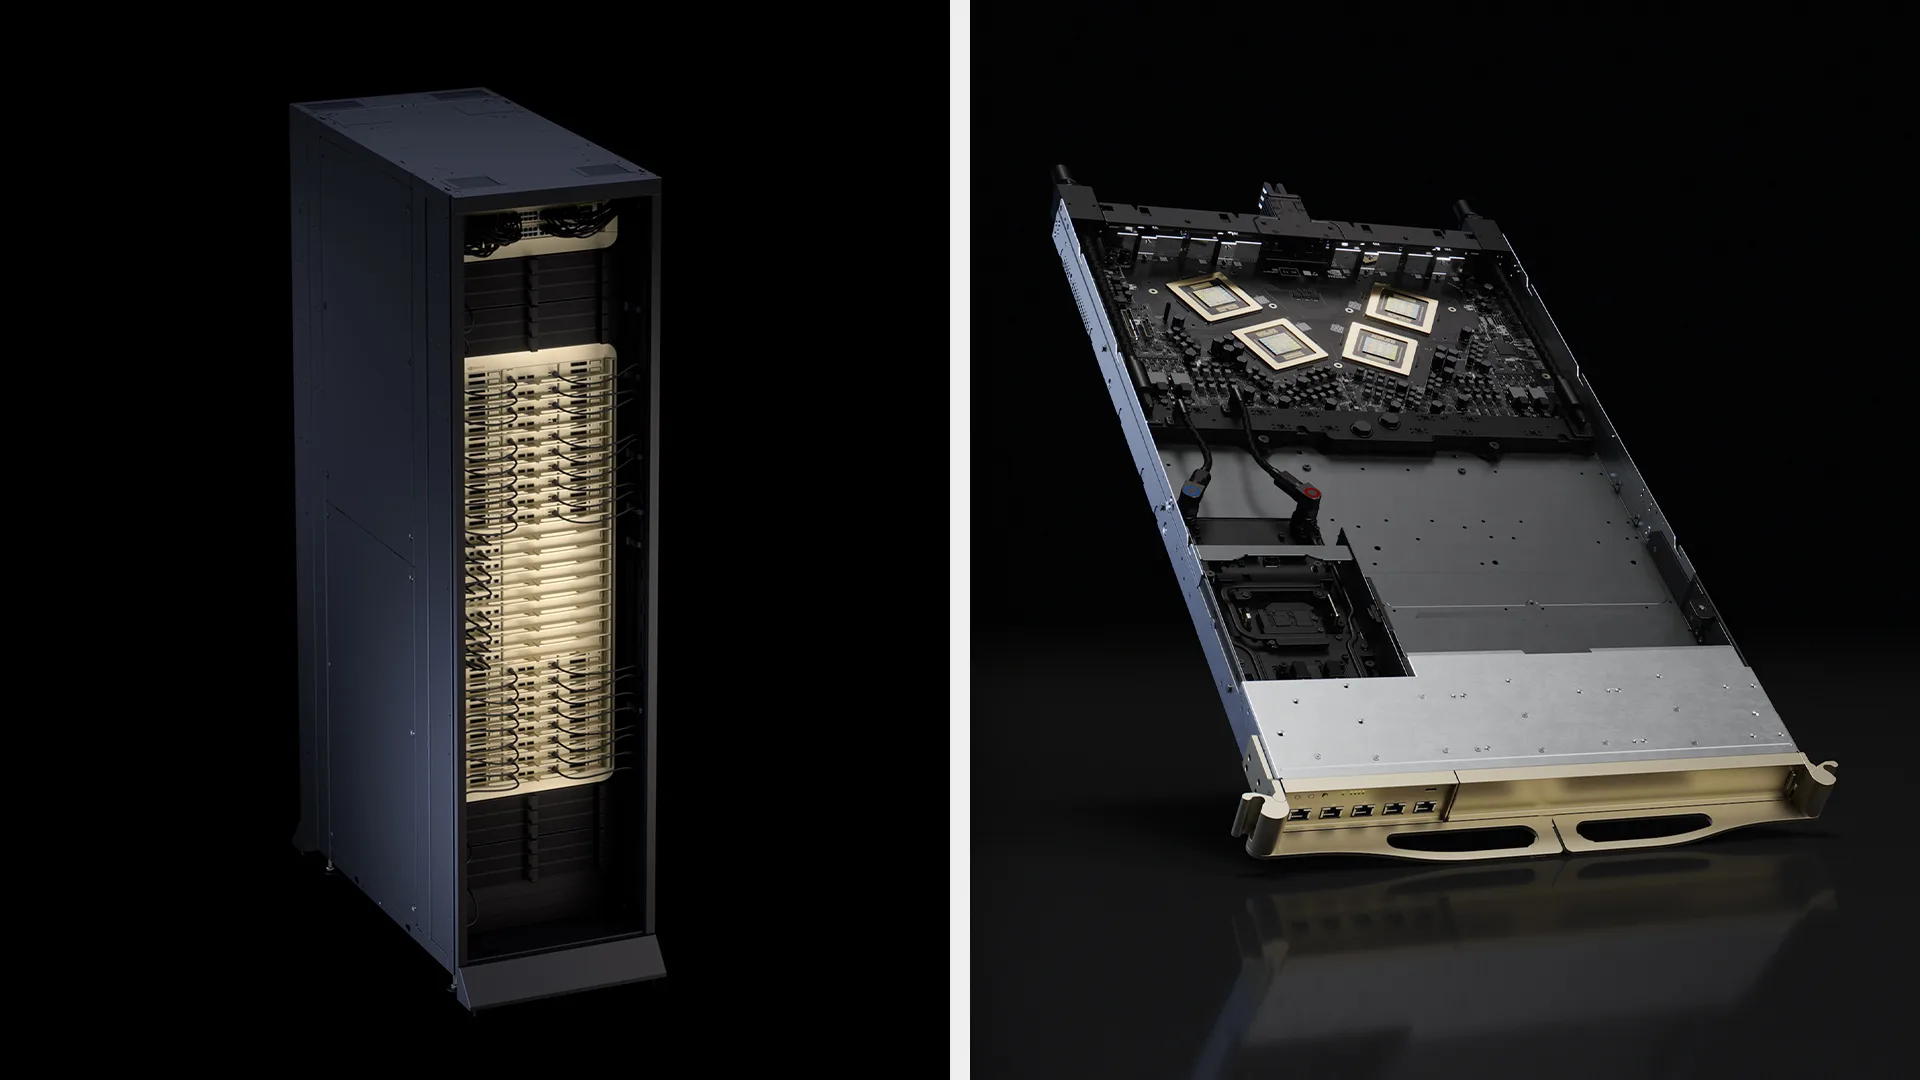
AI chipmaker d-Matrix plans to connect its next-generation Raptor processors through NVIDIA's NVLink Fusion platform. The arrangement would give its specialized chips access to established networking and rack designs, including power and cooling infrastructure.
The deployment problem extends beyond designing a fast processor: many chips must communicate and operate together inside a supported system. NVIDIA's announcement presents shared infrastructure as a way for d-Matrix to reduce that integration work. This is a planned deployment approach, with faster rollout and lower integration risk described as intended benefits.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
“Demand for inference is soaring, but capital, time and energy remain finite.”
Sid Sheth
“With NVLink Fusion and MGX, we can integrate our Raptor XPUs into a broadly deployed, liquid-cooled architecture, giving customers a faster, lower-risk path to deploy and scale ultralow-latency inference.”
Sid Sheth
Checking sign-in…
Loading comments…