OpenAI Ultrafast makes Astra up to 8x faster in Codex and the API
- Source
- x.com
- Date
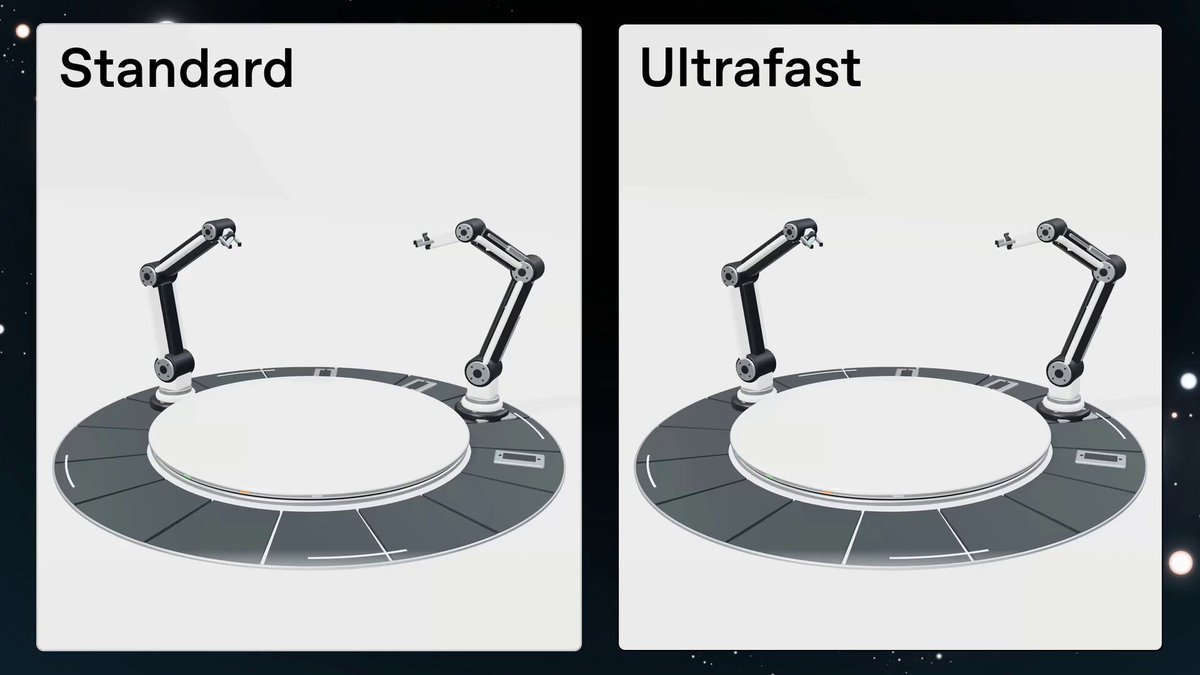
Ultrafast is a speed tier rather than a new model. OpenAI says it runs Astra up to 8x faster than the Standard tier in Codex. It is available through the API to all developers, and pairs with a new WebSocket mode in the Responses API, which OpenAI pitches as the route to real-time experiences on a frontier model. It is also bundled into a new Pro 500 plan. GPT-6.1 Sol support is listed as coming soon.
For agent builders, latency compounds across every step of a long tool-calling loop, so a large per-call speedup shortens end-to-end task time more than it shortens any single response. The claim is OpenAI's own and specific to Codex, so measure it on your own workloads before redesigning around it. The more interesting follow-up is Sol support: a fast tier on the cheaper model would change the cost and speed tradeoff for interactive agents.

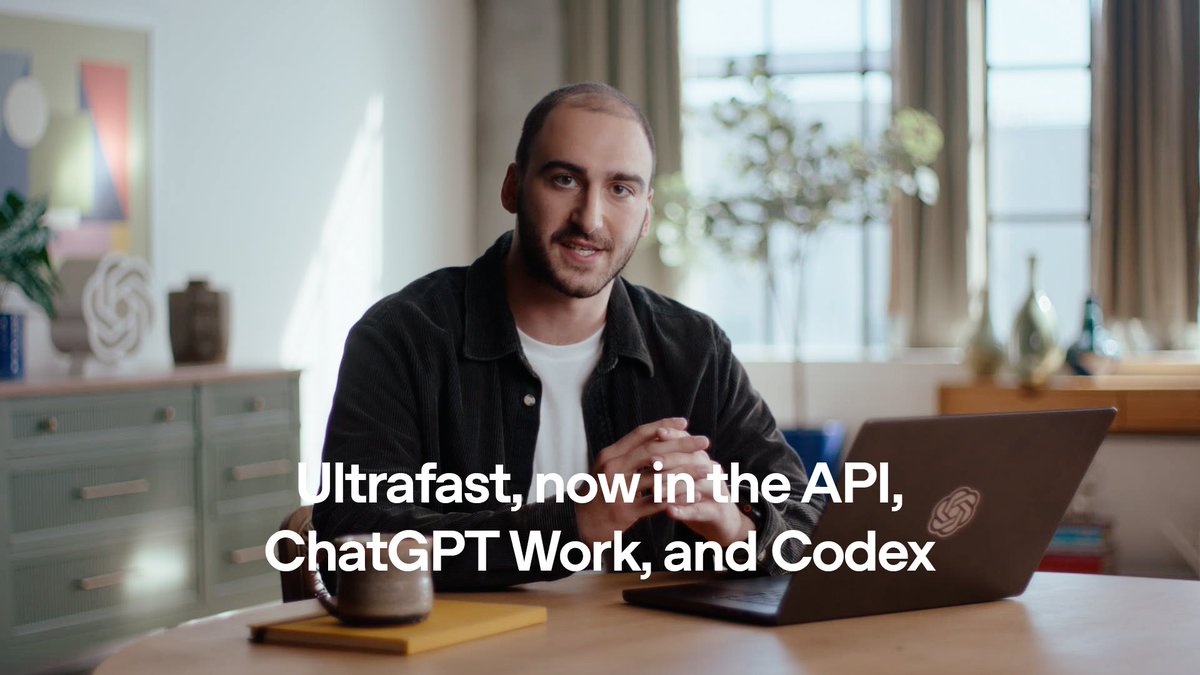
Ultrafast is our fastest way to build with Astra yet: in Codex, it runs up to 8x faster than Astra Standard and 4x faster than Astra Fast. Bring your ideas to life as fast as you can type them.
Context
Ultrafast is a speed setting for Astra, and its headline multiplier compares it with OpenAI's own slower Astra settings, not with other companies' models. In the OpenAI Developers post, the company says that in Codex, Ultrafast runs up to 8 times faster than Astra Standard and 4 times faster than Astra Fast.
The video attached to the post says what kind of speed is being counted, at least for the API. In its narration (an automatic speech transcript; the visuals were not analyzed), the presenter says that in the API, Ultrafast "generates " over seven times faster than the standard tier and over four times faster than the fast tier. Tokens are the small chunks of text a model writes out, so these figures describe how quickly output appears. Neither the post nor the narration says how much sooner a complete task finishes. OpenAI's main launch post, covered separately, also describes the Codex gain as faster token generation, but gives a lower API figure of up to 6 times without naming the baseline, so the API multiplier depends on which announcement and which comparison a reader takes.
The narration also claims that developers no longer have to trade speed for intelligence, and the demonstration generates sprites for a racing game while a regular-speed request is still running. The collected material includes no quality measurement, so the speed claim comes with OpenAI's own figures and the trade-off claim rests on its word alone.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.

Checking sign-in…
Loading comments…