Coding LLMs from Scratch
- Source
- github.com
- Author
- Prince Canuma
- Date
Context
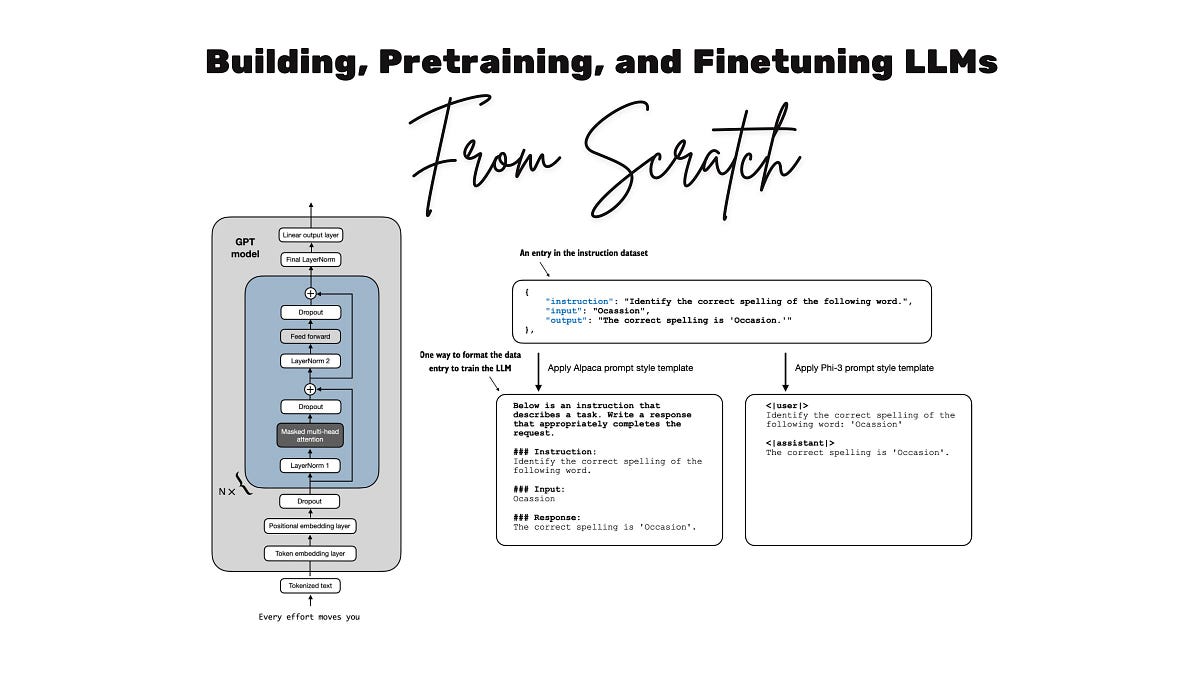
Coding LLMs from Scratch combines instructional model-building with a separate model release. Its Llama 2 teaching track describes constructing and training a small model for code completion. The separate Llama-3-6B release starts from an existing Meta Llama 3 model and continues training after modifying it.
That distinction helps readers choose what to study. Reconstructing a model's architecture exposes how its components fit together; adapting a pretrained model starts with learning already contained in an existing model. The repository includes both approaches, so its title should not be read as saying every published model was trained from an entirely new starting point.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
“By the end, you will have created and trained a LLaMA 2 model with 100M parameters from scratch using PyTorch to do code completion.”
“The goal is to code LLaMA 3 from scratch in PyTorch to create models with sizes 3B, 6B, 35B and 45B params.”
“Introducing the world's first Llama-3 base model with 6B parameters.”

Checking sign-in…
Loading comments…