Transformers Explained Visually
- Source
- poloclub.github.io
- Author
- aray07
- Date
Context
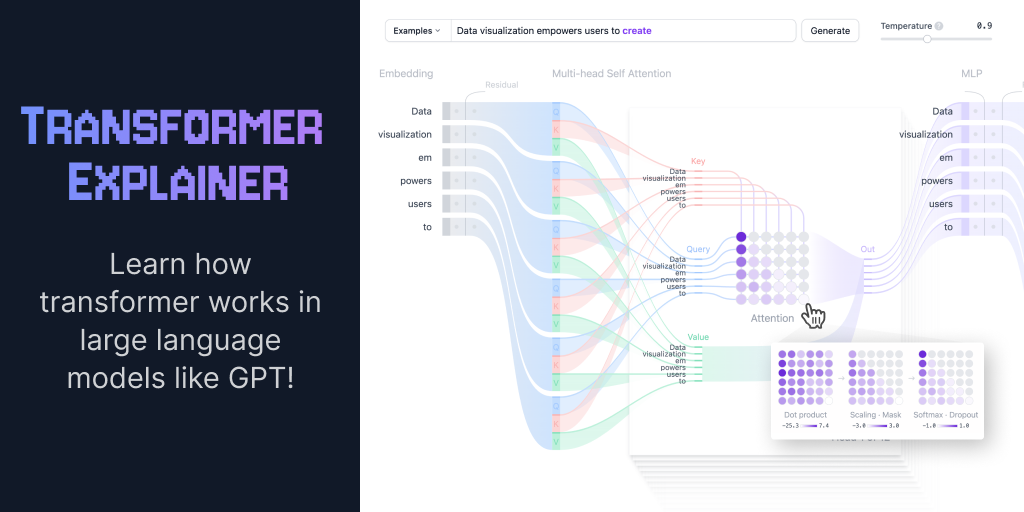
Transformer Explainer makes next- prediction inspectable using OpenAI's small GPT-2 model. Entered text becomes numerical representations; mixes information from preceding text, and the final layers assign probabilities to possible next text units. The interactive views expose those intermediate calculations.
Its temperature control illustrates why the same prompt can produce different continuations. Lower values concentrate probability on the leading candidates, while higher values spread it more widely before sampling. Changing that setting alters how an output is selected from the model's predictions. Following that process helps a learner connect a chat-style response to the calculations that generate it.
- transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
- embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.

Checking sign-in…
Loading comments…