What exactly does word2vec learn?
- Source
- bair.berkeley.edu
- Date
Context
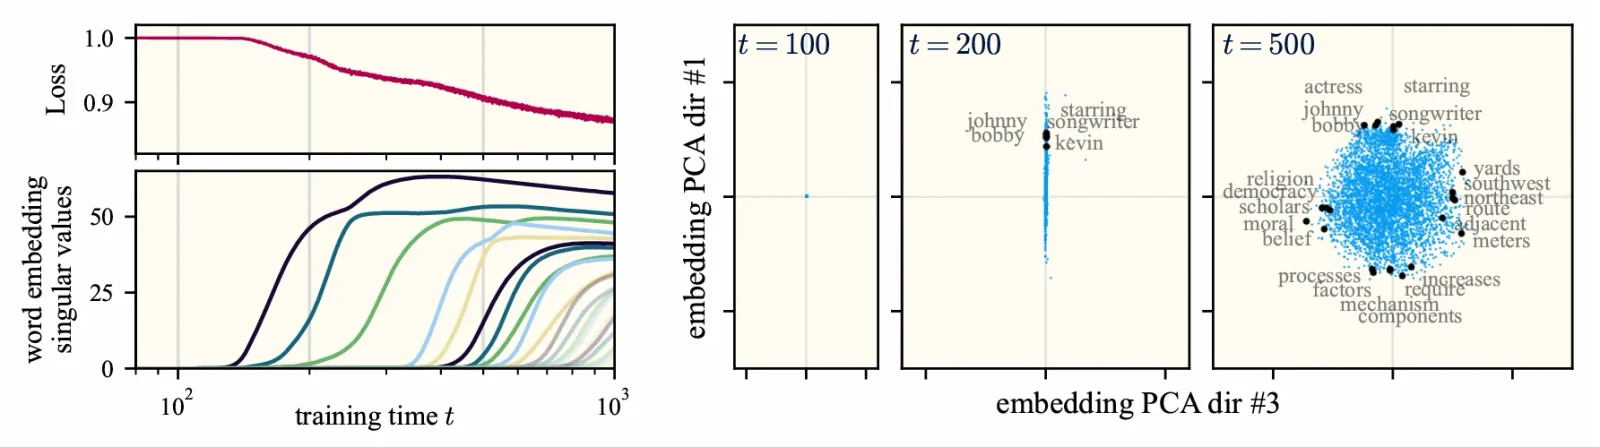
Word2vec learns numerical representations in which relationships between words become geometric patterns. A theory described by Berkeley AI Research explains how those patterns can emerge progressively: under the analyzed conditions, training adds one independent direction at a time, expanding the representation's capacity. The research explanation connects those directions to measurable word co-occurrence statistics.
The result makes it possible to calculate the predicted features from the text statistics and training settings. Its analytical solution uses an approximated training objective, constrained settings, very small initial weights, and infinitesimal learning steps. This provides a tractable account of a simple language-learning system, with the article reporting experimental agreement beyond the exact analytical setup.
- The paper shows word2vec's learned features are exactly the top eigenvectors of a specific target matrix built purely from word co-occurrence and unigram probabilities, so training is equivalent to running PCA on that matrix, computable a priori from corpus statistics alone.
- From near-zero initialization, word2vec learns in discrete steps: each step increments the matrix's effective rank by one concept; on Wikipedia the first eigenvectors track celebrity biographies, then government administration, then geography.
- The theory needs no data-distribution assumption, only four mild approximations; despite them, the resulting model scores 66% on a standard analogy versus 68% for real word2vec and only 51% for classical PPMI.
- Applying the theory to gendered/temporal concepts, the authors find the representation's geometry follows a spiked random matrix model: semantic signal dominates early in training, but noise can dominate later, degrading the model's ability to resolve that linear concept.
Checking sign-in…
Loading comments…