Fable 5.1 is now live in Claude Code and the Claude Platform.
- Source
- x.com
- Date

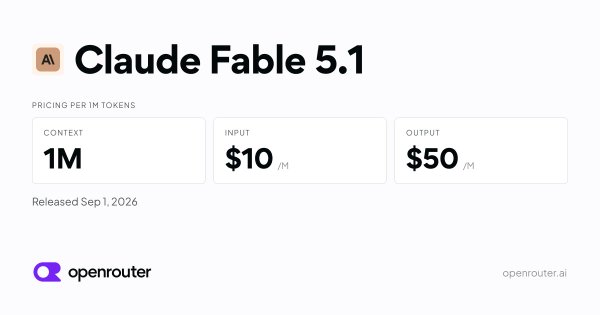
Fable 5.1 is now live in Claude Code and the Claude Platform. It's priced the same as Fable 5, with 75% cheaper API cache reads. It gets a lot further into a long task before it needs your input, is better at telling you when it's stuck, and its writing style is more natural. https://t.co/1xtB71e3Zw
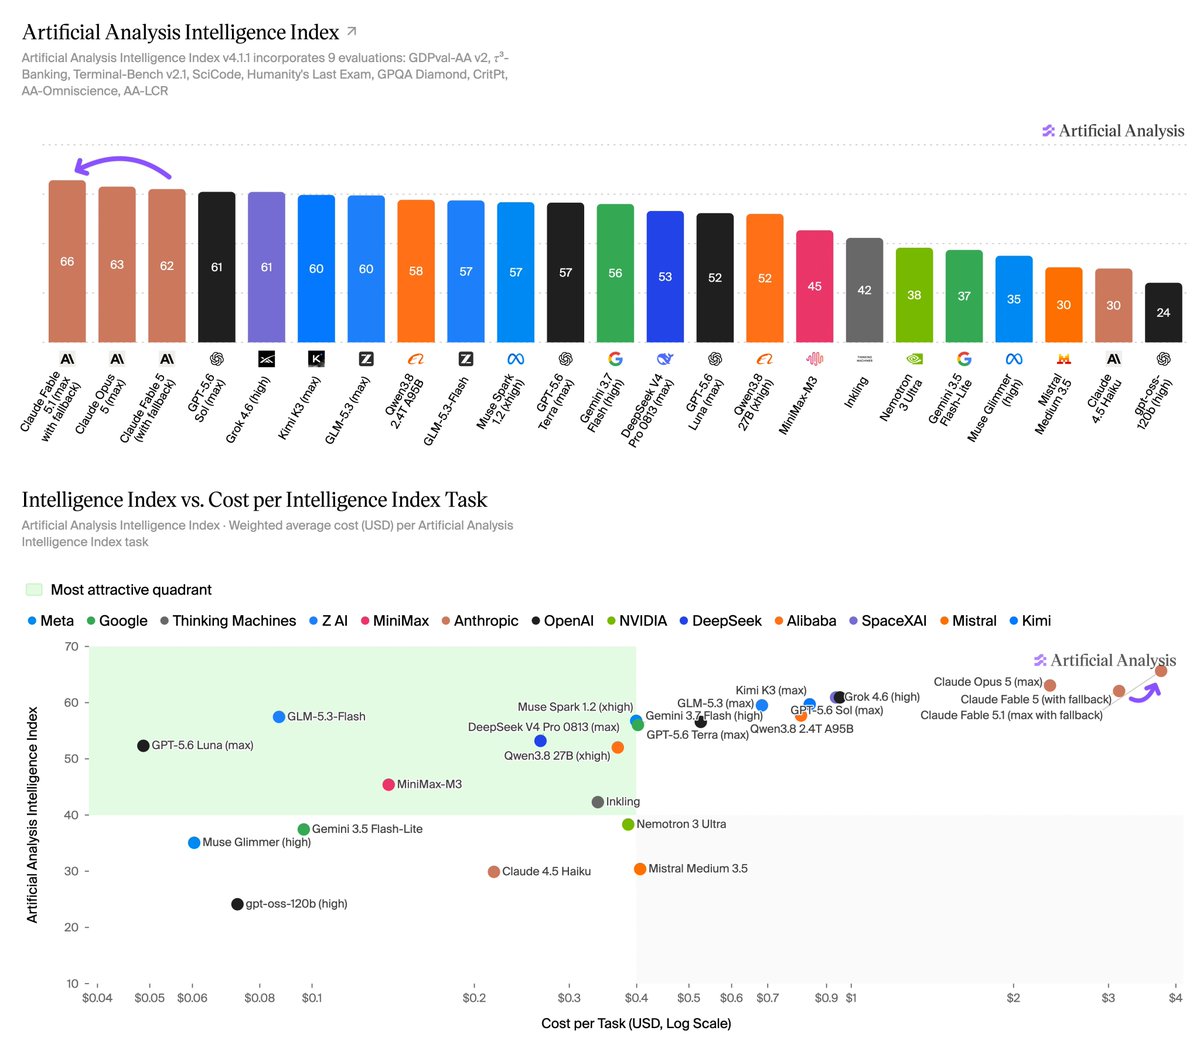
It’s ahead of both Fable 5 and Opus 5 across our agentic coding and computer use evals. On Terminal-Bench 4.0 in Claude Code, Fable 5.1 scores 55.8%. Fable 5 scores 42%, and Opus 5 scores 52.3% on the same setup.

Our biggest goal with this upgrade was to deliver increased intelligence while making the model safely accessible. So we’ve taken steps to manage costs while improving safety measures.
To lower costs, we’ve kept pricing the same as Fable 5 while lowering the price of cache reads on usage-based billing. Cache reads on Fable 5.1 are $0.25/MTok, down from $1/MTok on Fable 5. For builders on the Claude Platform with long horizon workloads, a prompt cache-optimized integration will see significant savings. In Claude Code, cache reads count at a reduced rate toward subscription usage, which remains unchanged. Long sessions billed at API rates can net out 25%-45% cheaper.
Context
Anthropic cut the price of one specific part of Fable 5.1 usage: cache reads. Caching lets a long session reuse the model has already processed instead of paying the full input price again. In its developer announcement, Anthropic says cache reads on Fable 5.1 cost $0.25 per million , down from $1 on Fable 5, while standard pricing is unchanged from Fable 5. An integration built to reuse cached context therefore pays less for that part of its workload.
Anthropic estimates that long Claude Code sessions billed at API rates can come out 25% to 45% cheaper. That estimate concerns those sessions; the 75% reduction applies specifically to cache reads, not to every component of a task's bill.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- distillation — Training a small, cheap model to imitate a big one's outputs, keeping much of the capability at a fraction of the cost.
Checking sign-in…
Loading comments…