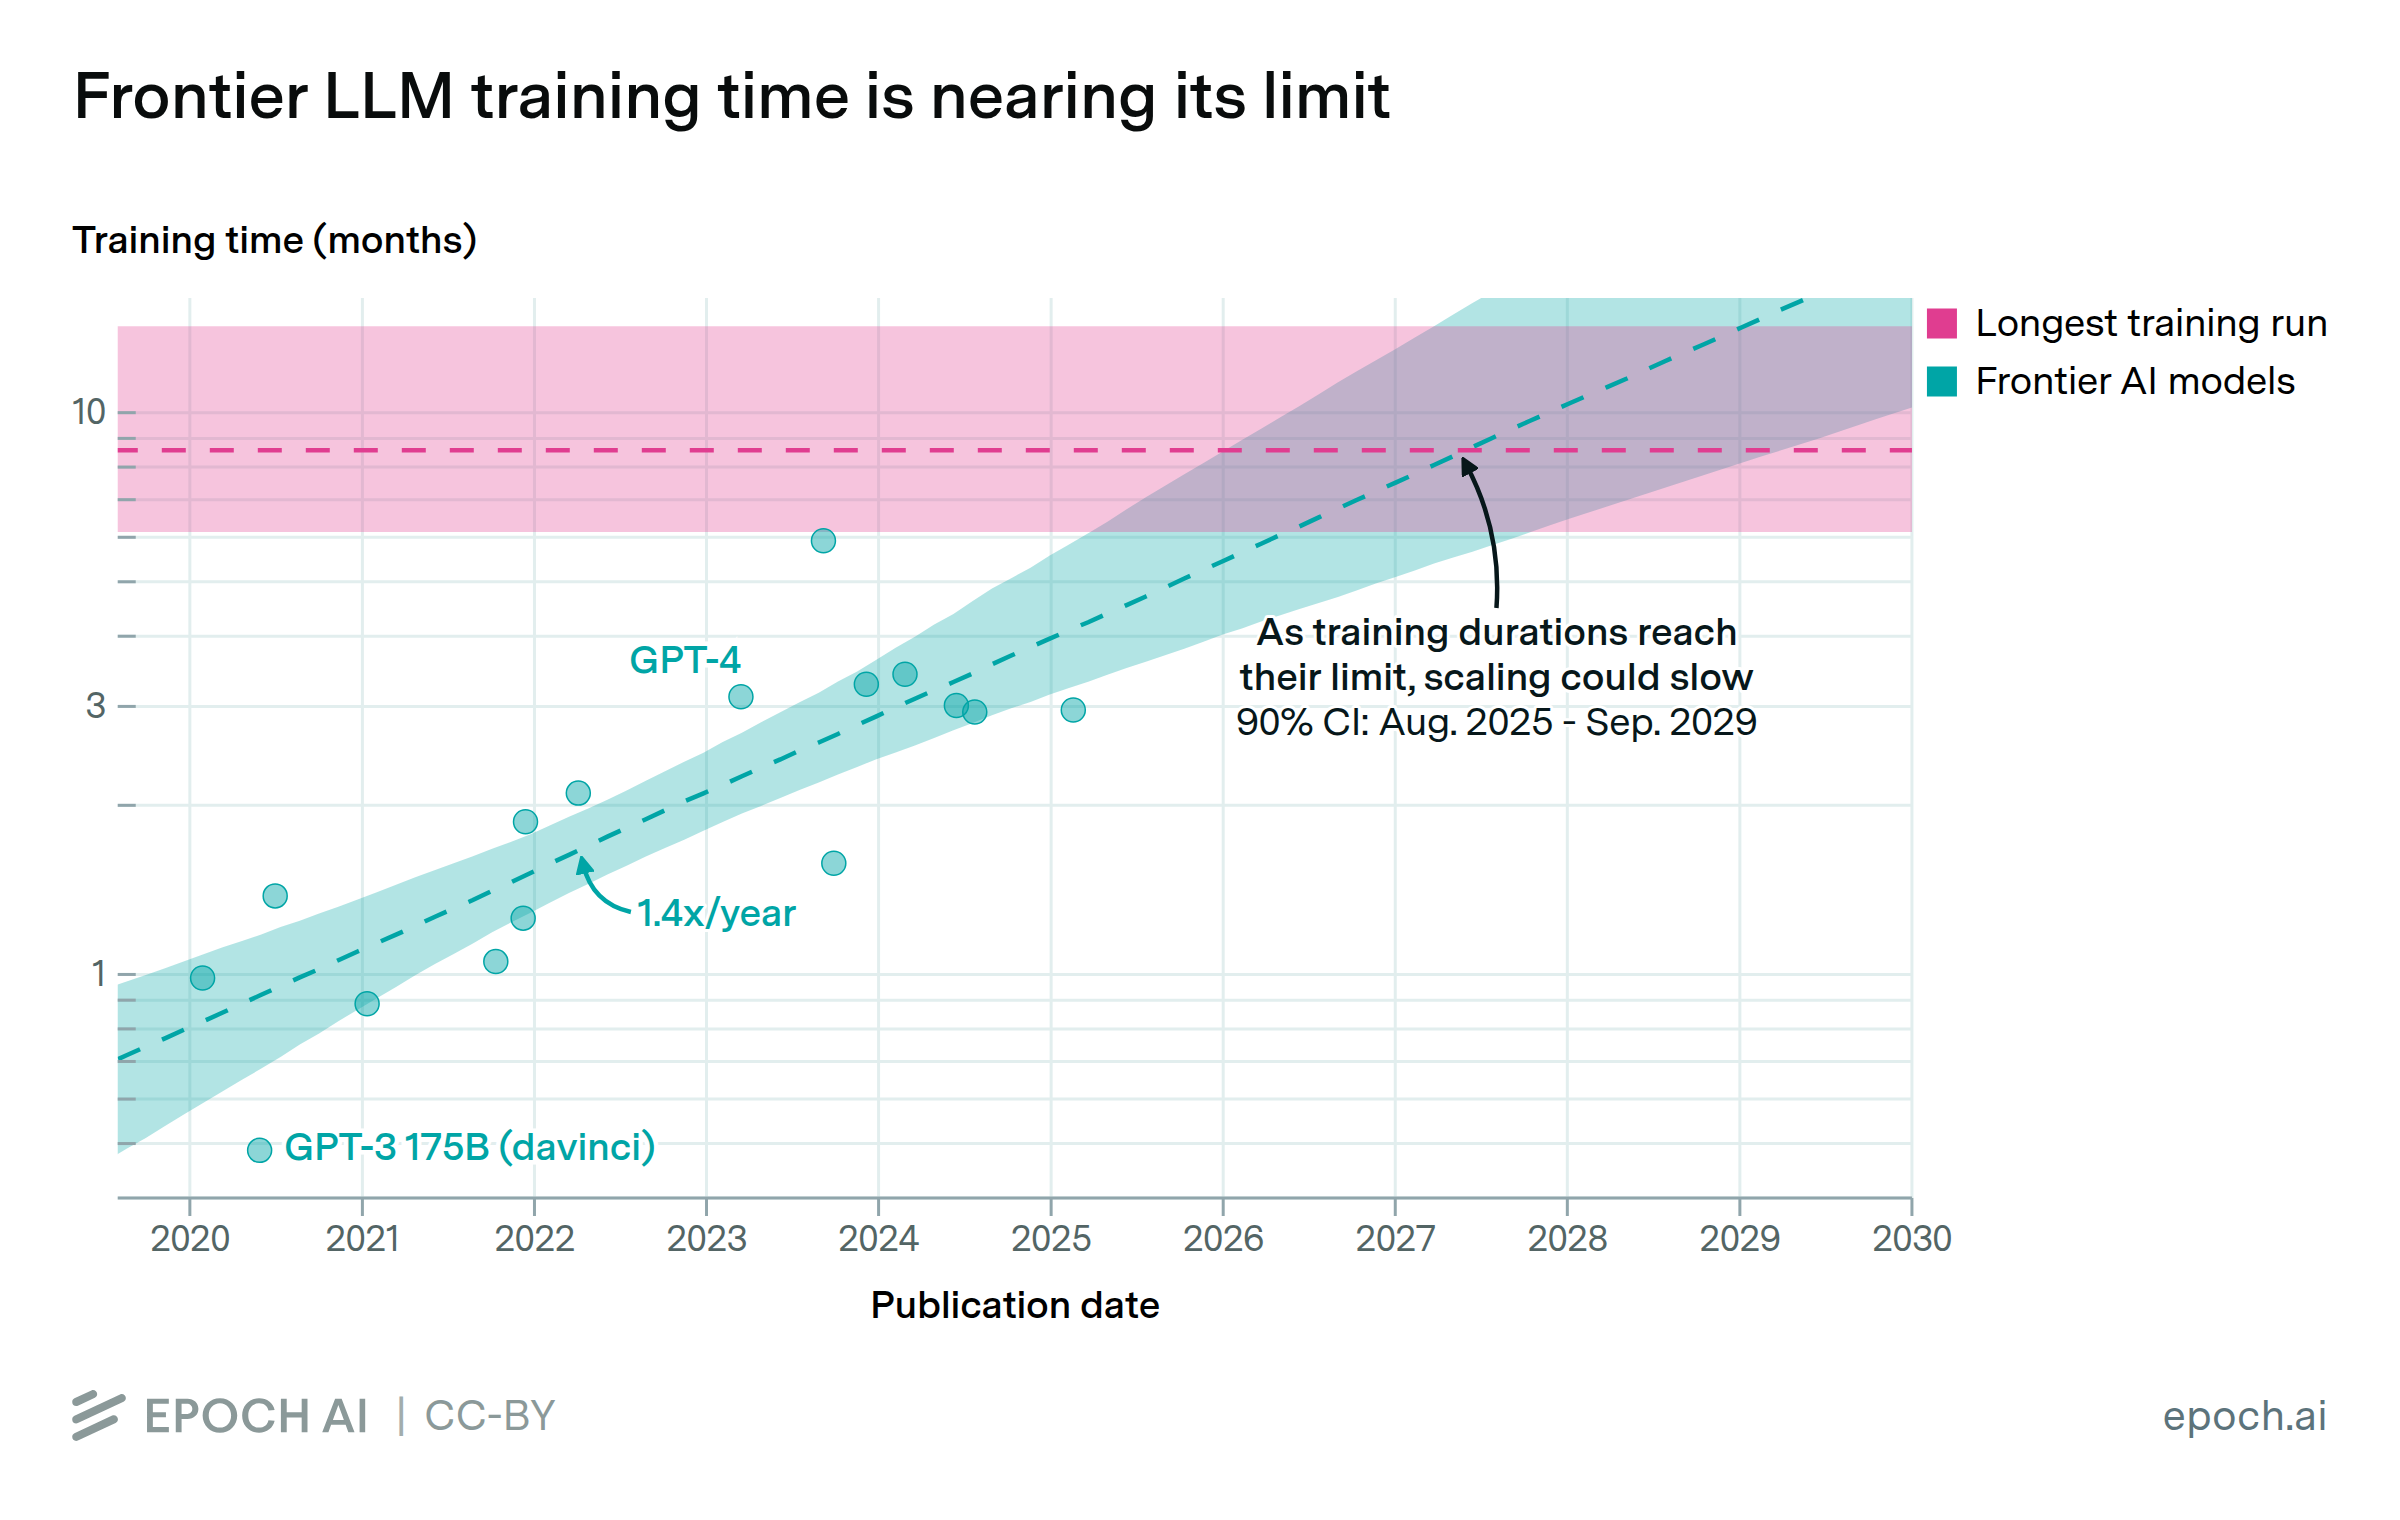
If runs lasting over nine months lose to later runs with better hardware and algorithms, further capability scaling must come from more compute per unit time rather than longer training.
Key takeaways · AI-distilled
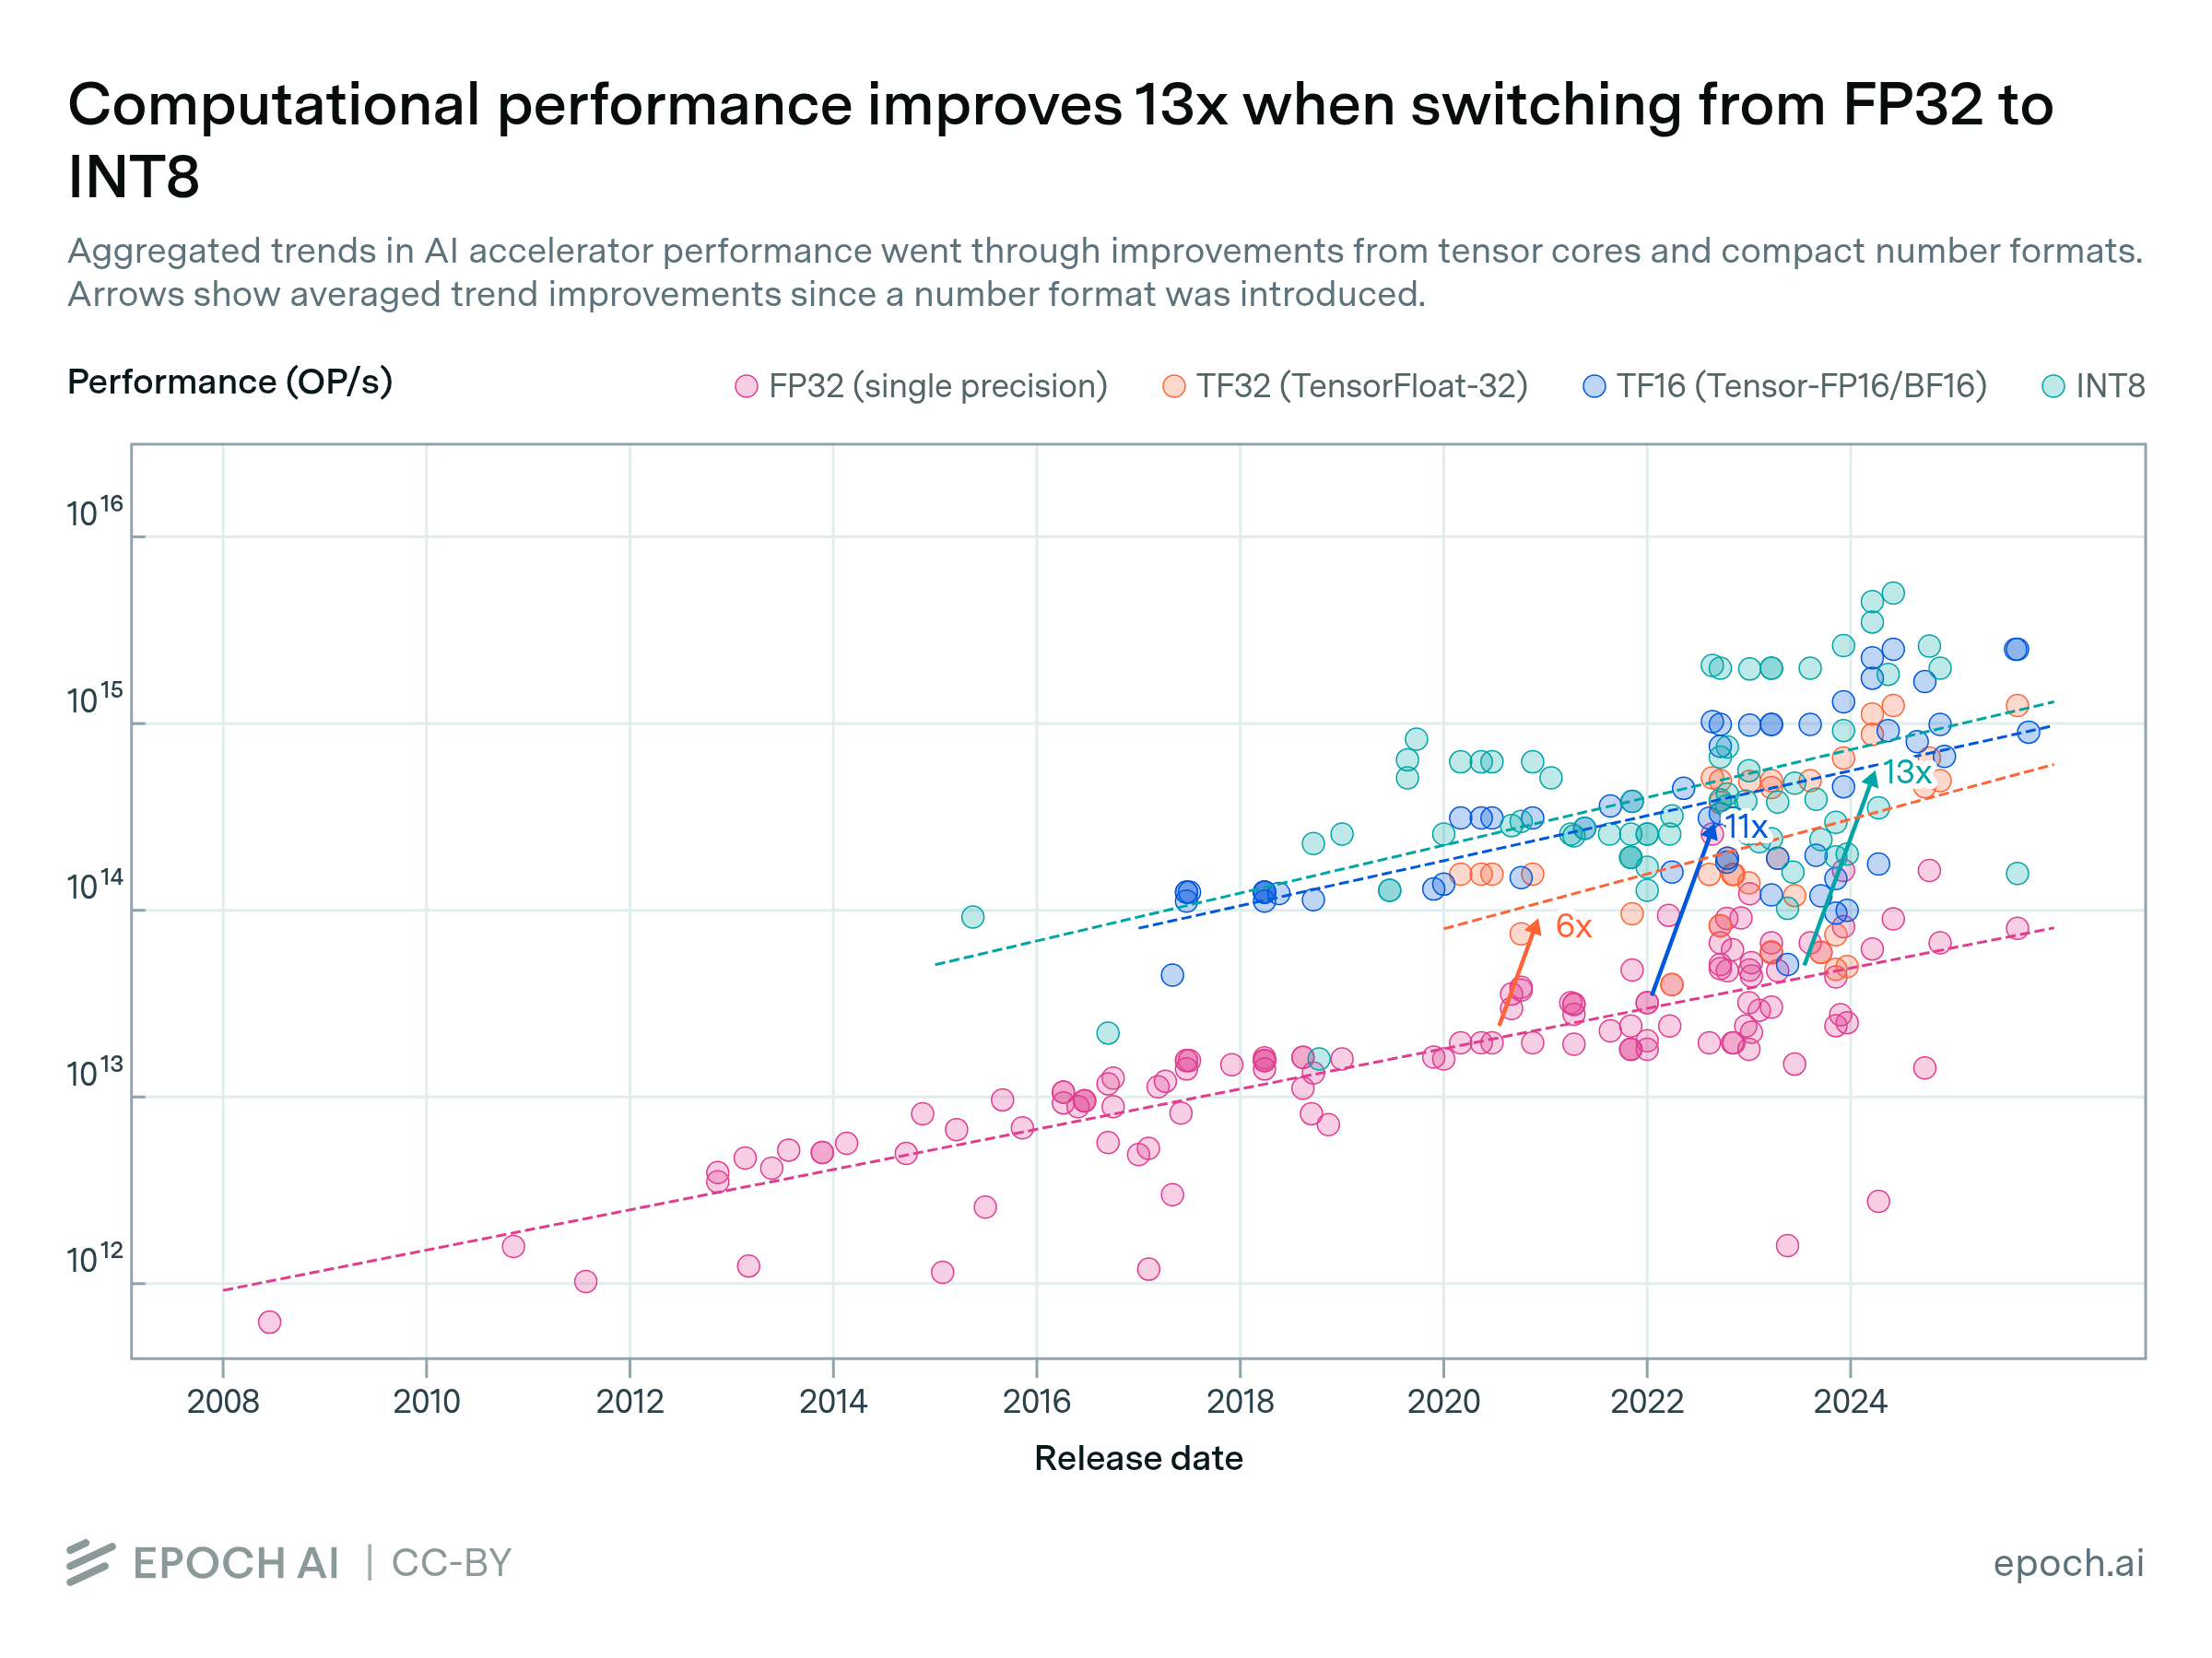
Epoch says longer training runs have been a significant driver of frontier training-compute growth, so if run lengths stop increasing, compute growth will slow unless hardware scaling speeds up.
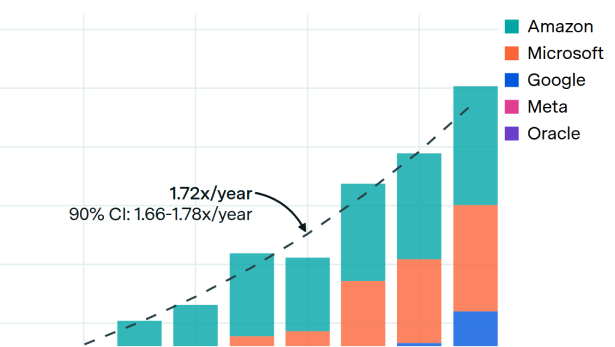
It names two ways developers could compensate: building larger clusters faster, or spreading a single training run across multiple clusters.
Among notable models with reported durations in Epoch's table, Grok-3, Llama 3.1-405B, Nemotron-4 340B and GPT-4 each trained for roughly 3 months, while Falcon-180B ran about 5.9 months.