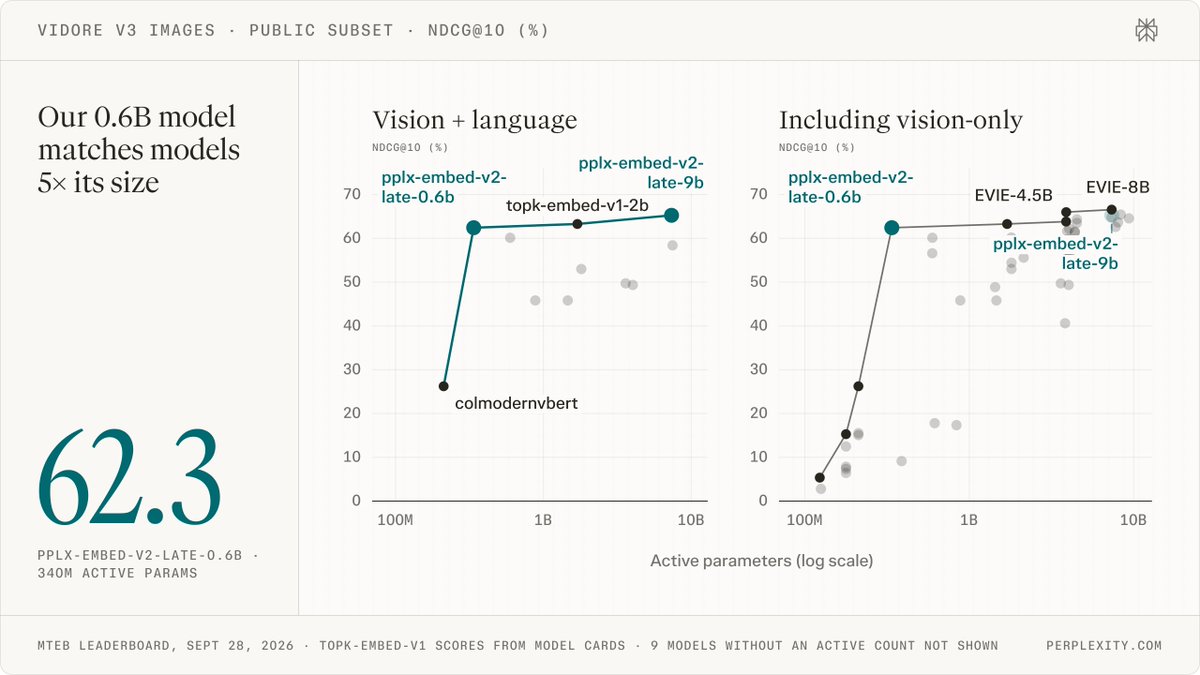
An MIT-licensed 9B multimodalA model that works with more than text — reading images, audio, or video, and sometimes generating them too.Full definition → embedder whose 1024-dim prefix is compatible with the 0.6B model lets you mix a large indexing model with a cheap query model. Contextual chunkingSplitting documents into passages small enough to embed and retrieve individually — the step that quietly determines whether retrieval works at all.Full definition → also applies to images.
Terms in this piece · Glossary
multimodal — A model that works with more than text — reading images, audio, or video, and sometimes generating them too.
embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
chunking — Splitting documents into passages small enough to embed and retrieve individually — the step that quietly determines whether retrieval works at all.