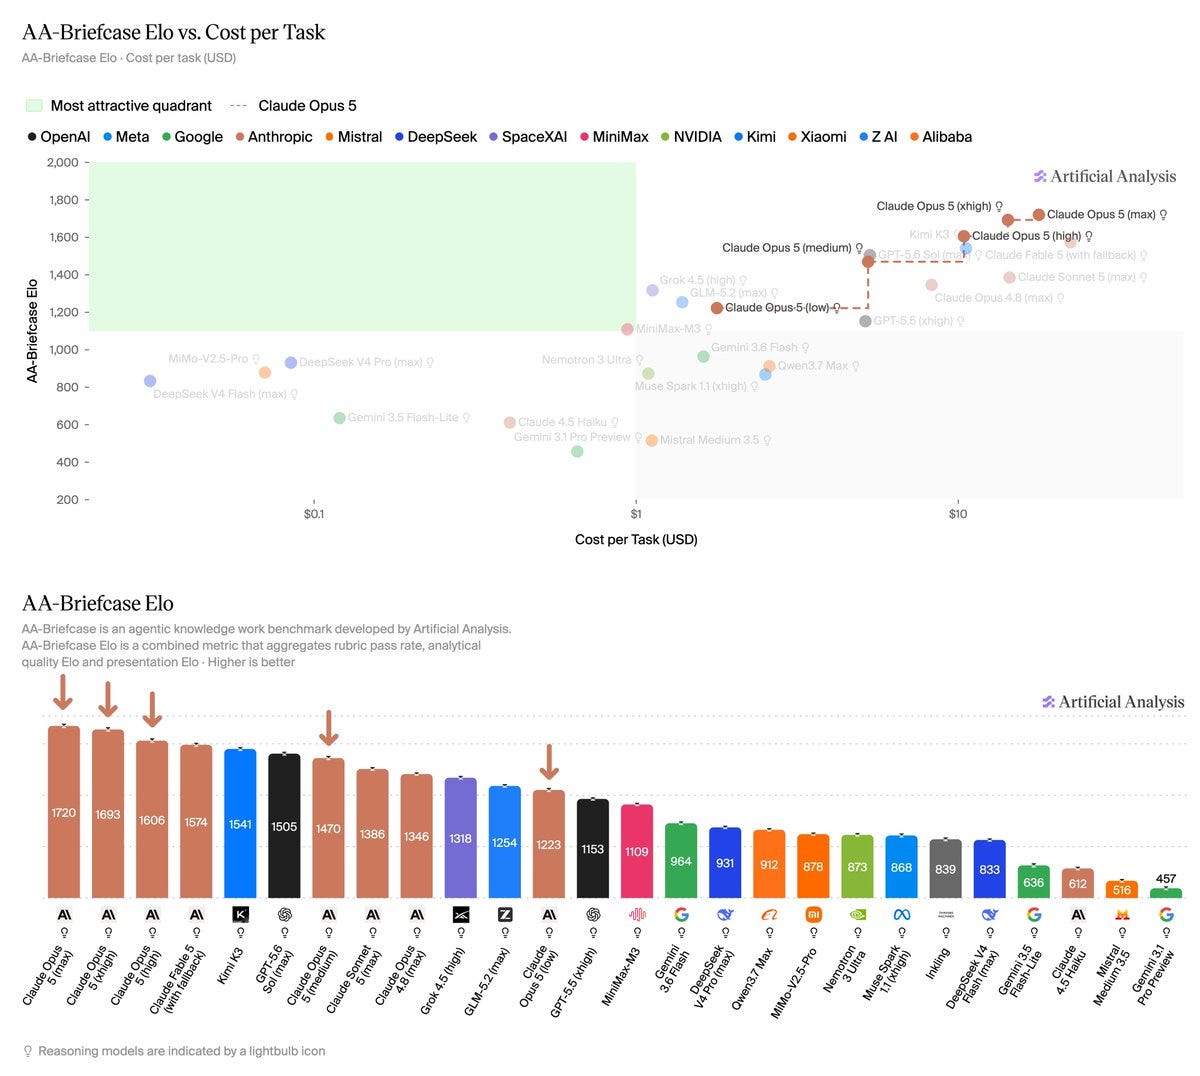
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Why it matters
Shows how frontier models behave as agents with a stateful, irreversible tool: they converge on the same subjects across independent runs, and they rank other models' work above their own. Useful evidence on model priors and evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → design.