An Open Recipe for IMO Gold: Training Nemotron for Olympiad Mathematics
- Source
- arxiv.org
- Author
- Ivan Moshkov, Stephen Ge, George Armstrong, Wei Du, Sadegh Mahdavi, Igor Gitman
- Date
Most systems that reach International Mathematical Olympiad gold level lean on a formal theorem prover to check each step, which means every problem first has to be translated into formal logic. NVIDIA's recipe skips that translation step entirely. Two Nemotron 3 Ultra models are post-trained as specialists, a generator that proposes proof attempts and a verifier that checks them, and the two run an iterative refine loop in plain natural language until the proof holds up. That combination reached the IMO 2026 gold-medal threshold without any formal prover in the loop. The more consequential part for outside researchers is what shipped alongside the result: the post-training checkpoints, the training data, and the inference code needed to reproduce or extend it, plus a new benchmark for the task. Open recipes for frontier math performance are rare, and most published results describe the outcome without the pipeline that produced it. This one hands over the pipeline, so labs without frontier-scale budgets can test whether the same generate-verify-refine pattern transfers to other domains that need rigorous, checkable reasoning rather than a fluent-sounding answer.
Context
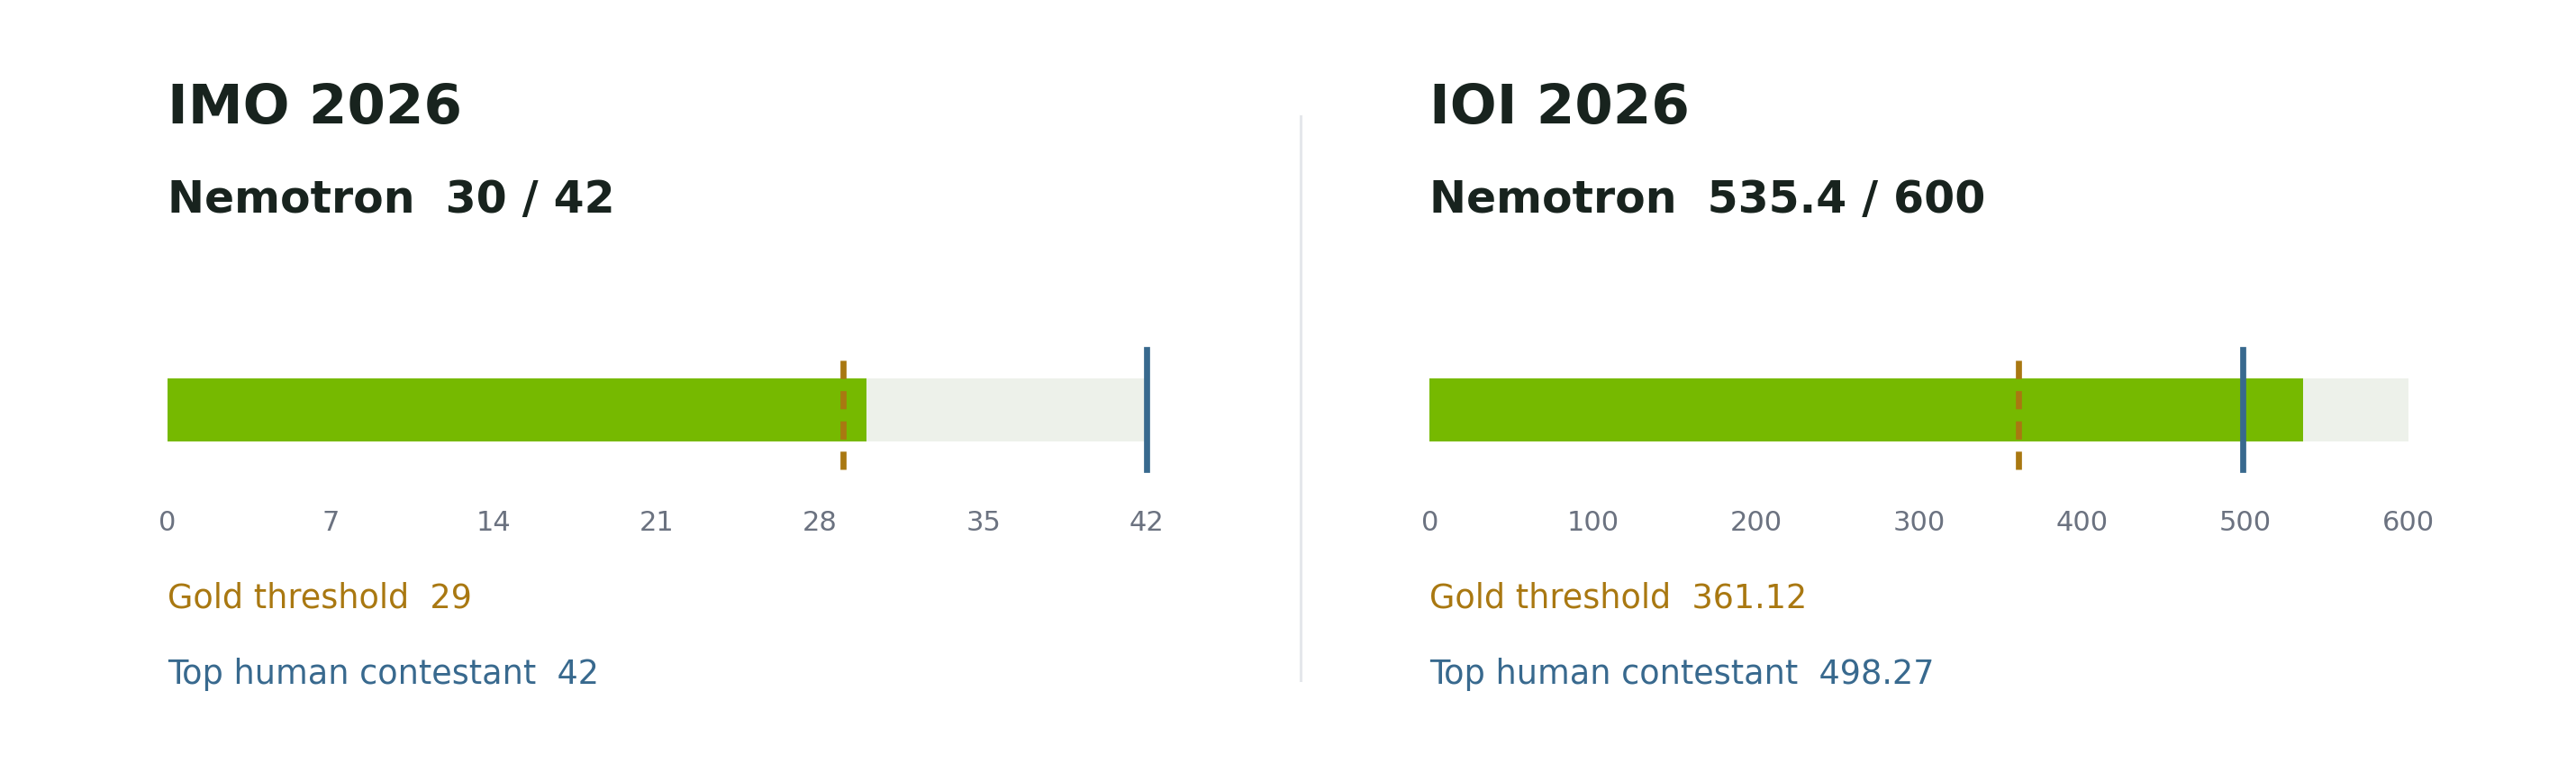
NVIDIA's reported olympiad result came from a system that repeatedly generated, checked, and revised mathematical proofs. The paper abstract describes three Nemotron model versions, including two specially trained variants, followed by a separate computationally intensive selection stage. The system worked in natural language without a formal proof checker, external tools, or internet access, and scored 30 out of 42 points on IMO 2026, which the authors say reached the gold-medal threshold.
NVIDIA's companion account, also covered in related Intel, says official IMO graders assessed the submitted proofs. The result belongs to this complete search-and-selection pipeline, so it should not be read as the score of a single ordinary model response.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
 articleOne Model Family, Two Gold-Level Results: Fine-Tuning Nemotron for IOI and IMOhuggingface.co
 videoOpenAI’s IMO Team on Why Models Are Finally Solving Elite-Level MathSequoia Capital
 articleRePro: Proof-Verified Benchmark Rewriting for Reliable Evaluation of LLM Mathematical Problem SolvingXiyuan Zhou, Zhuoqi Li, Xinlei Wang, Yirui He, Yuhao Wu, Yuheng Cheng, Yan Xu, Junhua Zhao, Jinjin Gu
Checking sign-in…
Loading comments…