Hamel Husain and Isaac Flath found the build_evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → workflow in Anthropic's claude-api plugin asked them to pick a failure to turn into an eval before they had reviewed any conversations. Husain argues you should look at the data first, then decide which failures matter.
To validate labels, the tool had reviewers skim long conversations in a Markdown file and report corrections in chat. The pair asked Claude to build a web annotation app instead, and Husain argues most eval work belongs in a web app rather than a chat window.
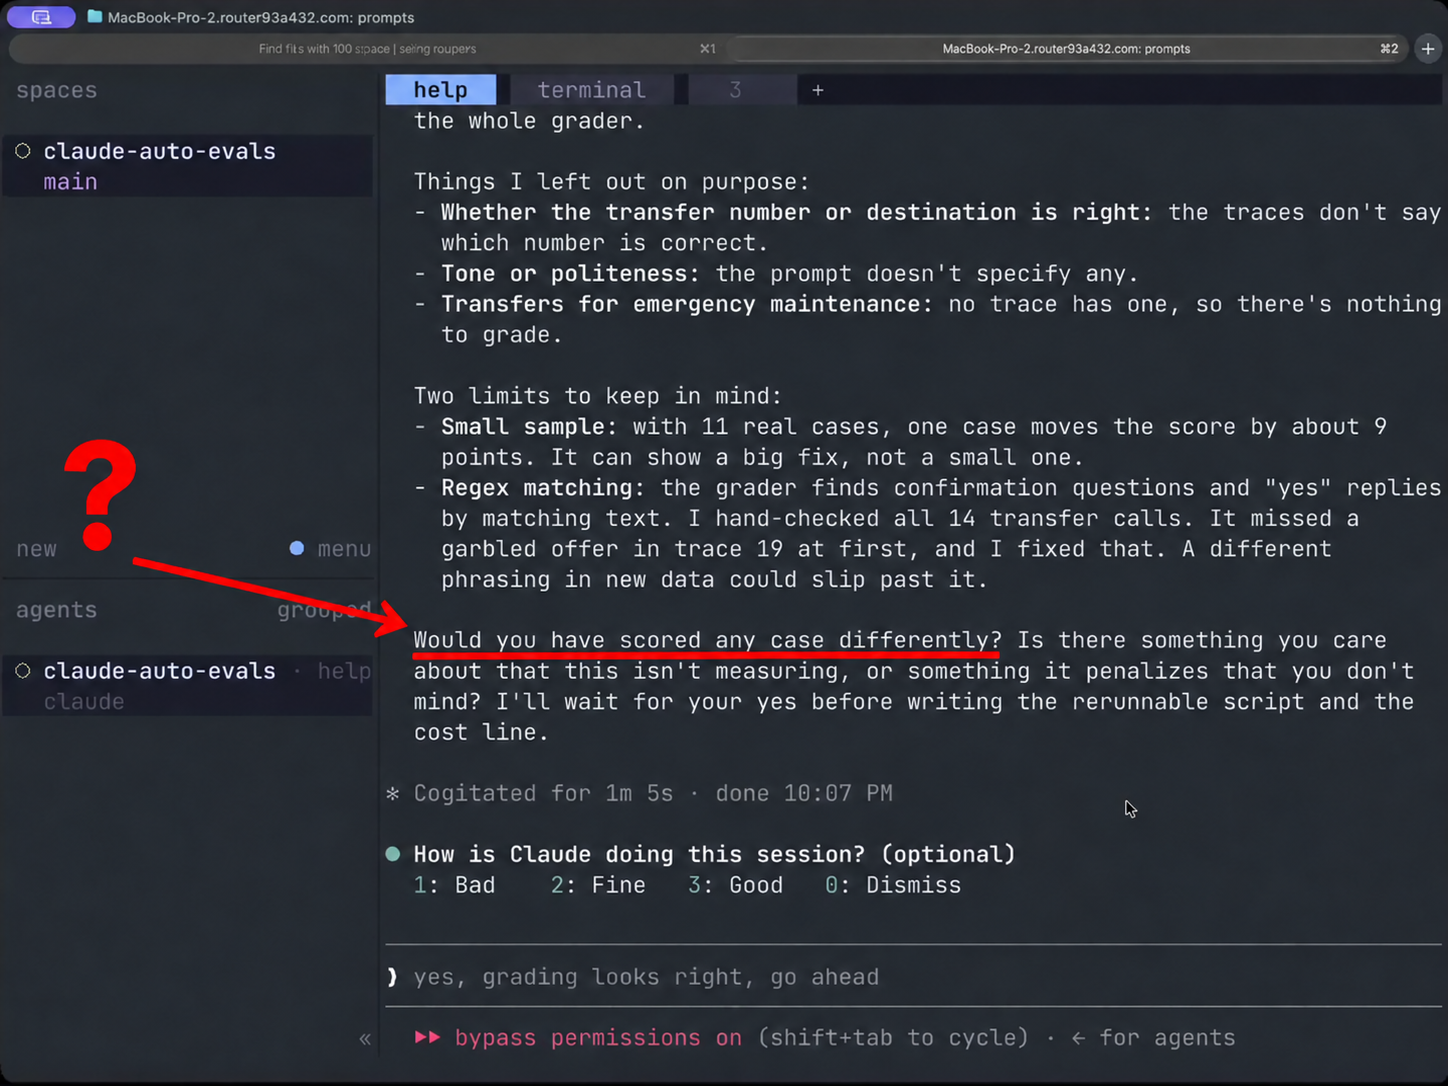
The generated call-transfer evaluator bundled four checks, one LLM-as-judgeUsing one model to score another's output against a rubric, so quality can be measured at a scale human grading cannot reach.Full definition → and three code-based, into a single pass/fail score. Husain recommends scoping each eval to one error, or at least separating code checks from judge checks, and reading the judge prompt itself.
On the positive side, Husain says the plugin's one-shot issue discovery surfaced problems with human handoff, formatting and voice behavior that other auto-eval approaches had missed, the strongest result of that kind he has seen.
His verdict is to hold off for now. The plugin's author told him it would be updated in response to the feedback, so the specific workflow reviewed here may change.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
LLM-as-judge — Using one model to score another's output against a rubric, so quality can be measured at a scale human grading cannot reach.
Why it matters
Anthropic's eval tooling will shape how many teams build evals. This review shows where it nudges you to skip error analysis and validate judgments without enough context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition →.