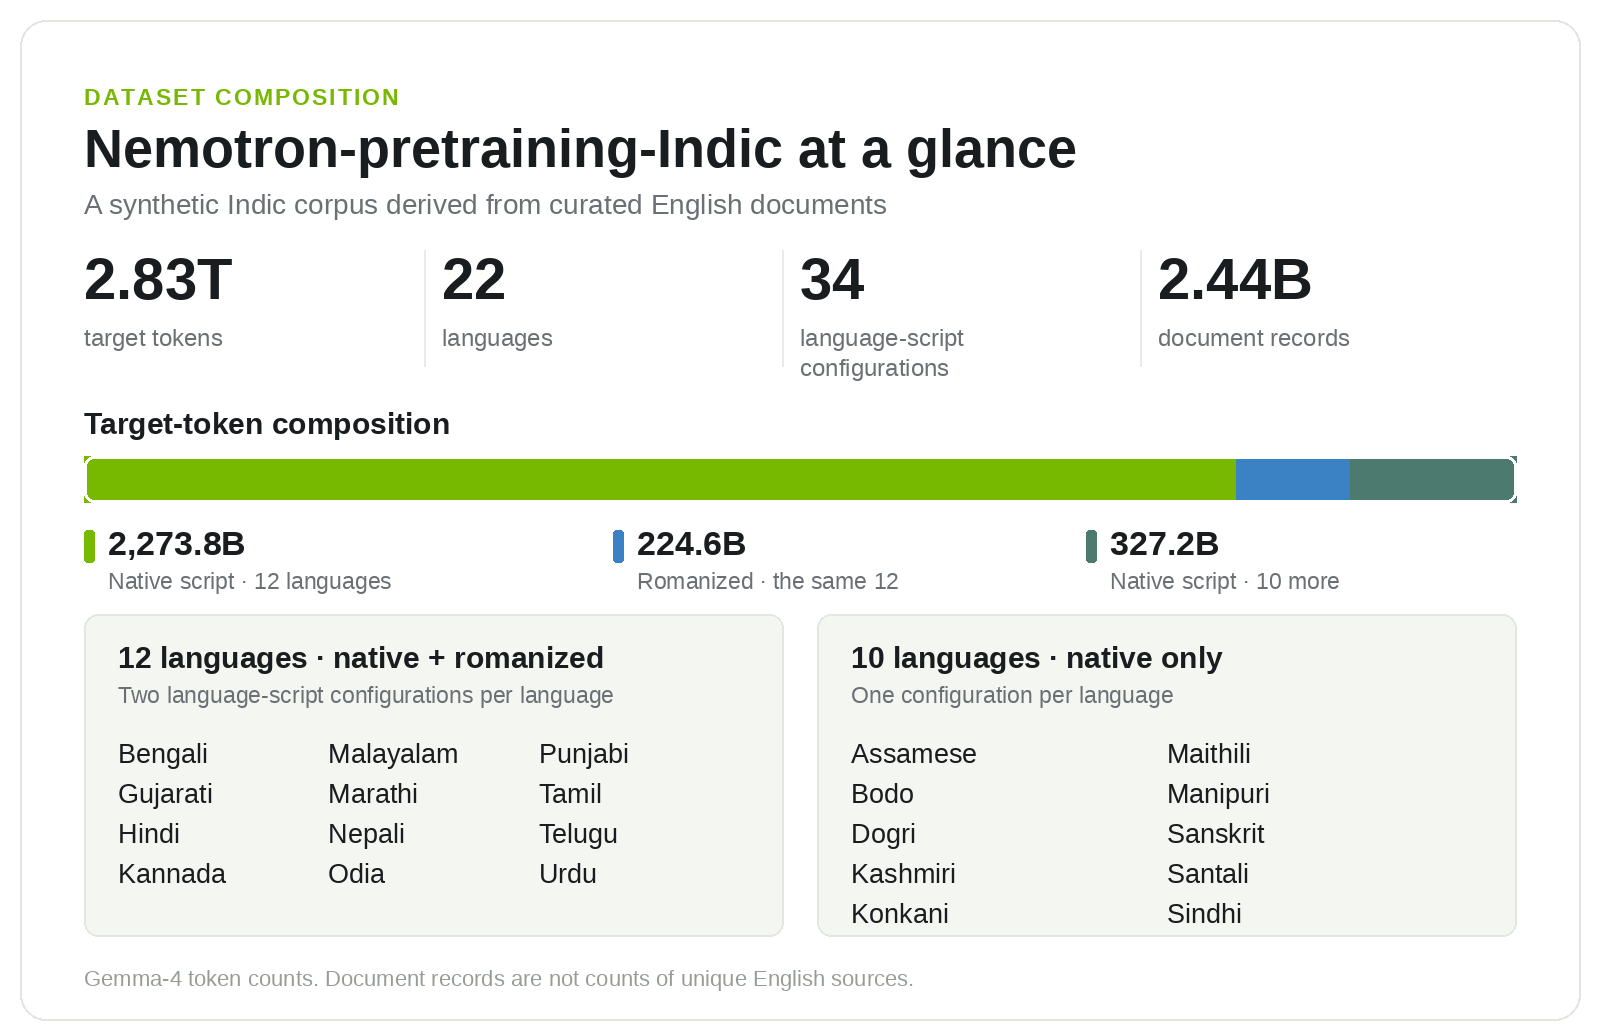
Scaling Indic Pretraining: 2.8 Trillion Tokens and an Open Data Generation Pipeline
Source
huggingface.co
Date
Why it matters
The pipeline documents the translation, quality assessment, and repair workflow used to turn English math, code, and QA data into Indic languages, so teams can adapt the recipe to their own source material for low-resource language pretrainingThe first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.Full definition →.
Terms in this piece · Glossary
pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.