Explains the R1 pipeline of pure RL with verifiable rewards, then SFT and preference tuning to recover general usability, which is directly useful for anyone building reasoning models.
Terms in this piece · Glossary
RLHF — Reinforcement learning from human feedback — training a model to prefer answers humans rate as better, which turns a raw text predictor into a usable assistant.


 article[AINews] DeepSeek v4.1-Flash: 763B-P8B-D16B novel causal Encoder–Decoder architecture with vision marks the Return of the Whalewww.latent.space
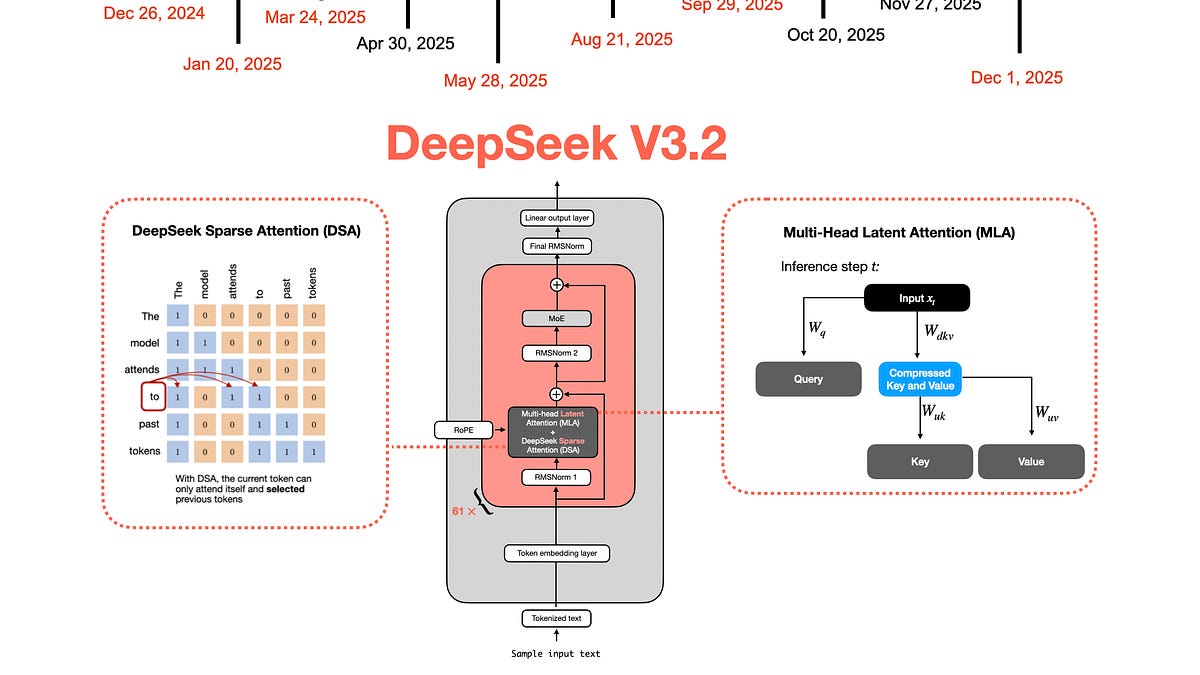 articleA Technical Tour of the DeepSeek Models from V3 to V3.2Sebastian Raschka, PhD
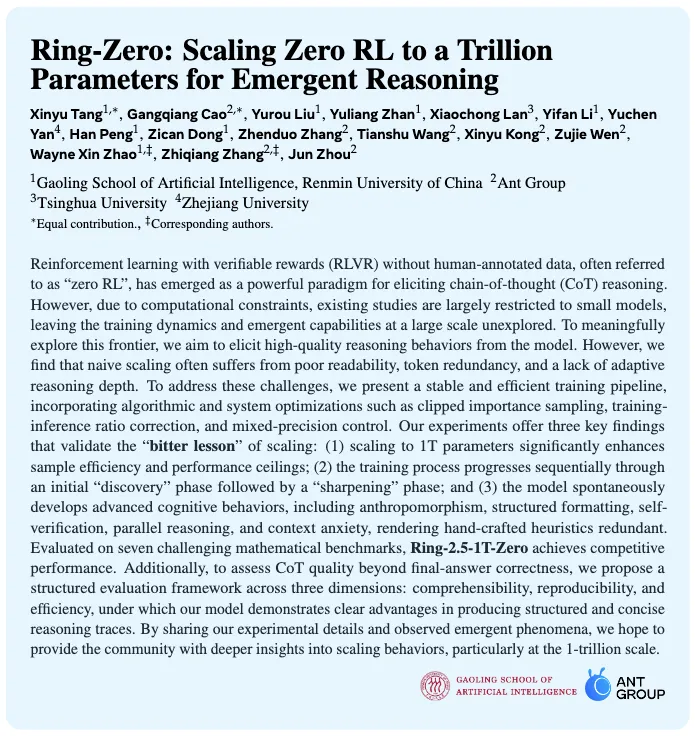 postZero RL at trillion scale, with no format rewards requiredAnt Ling