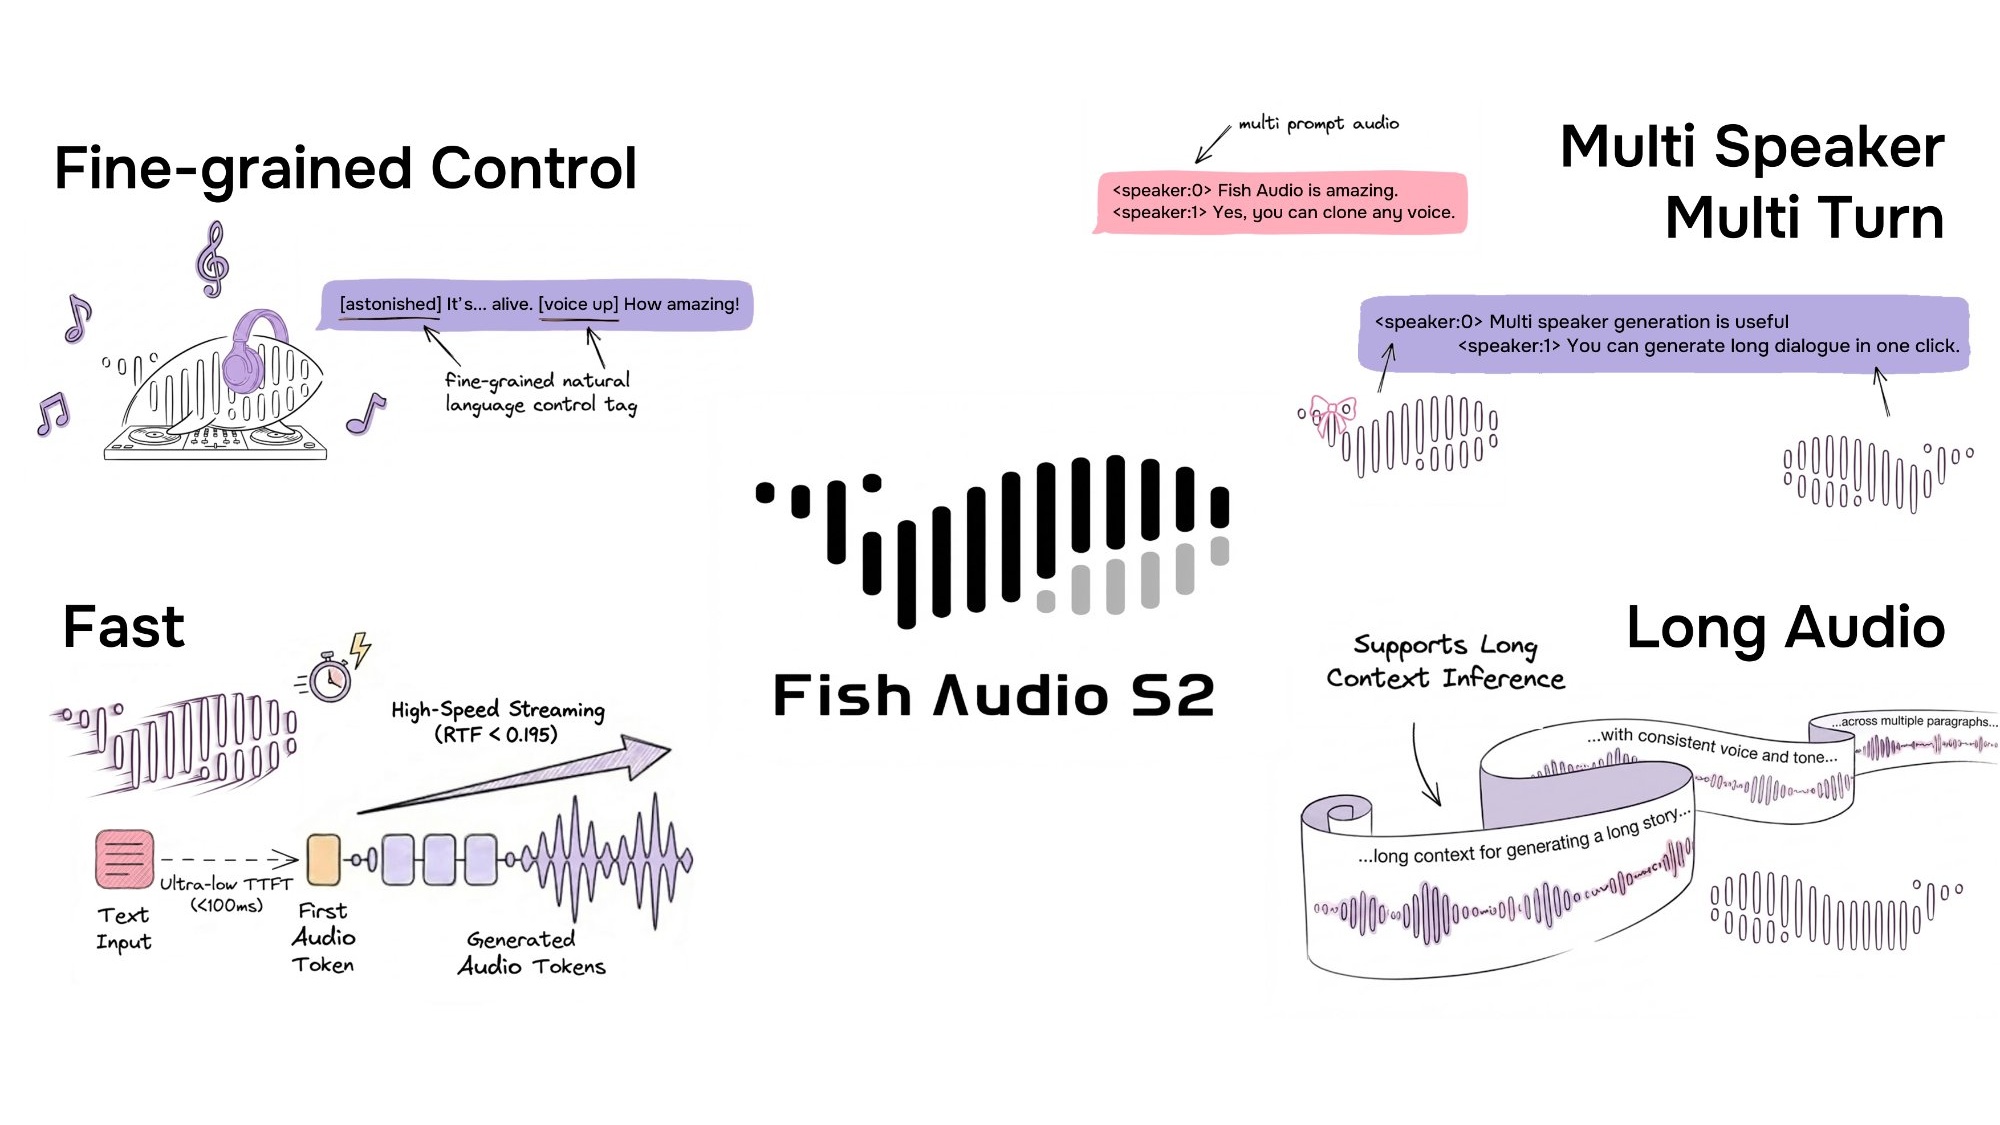
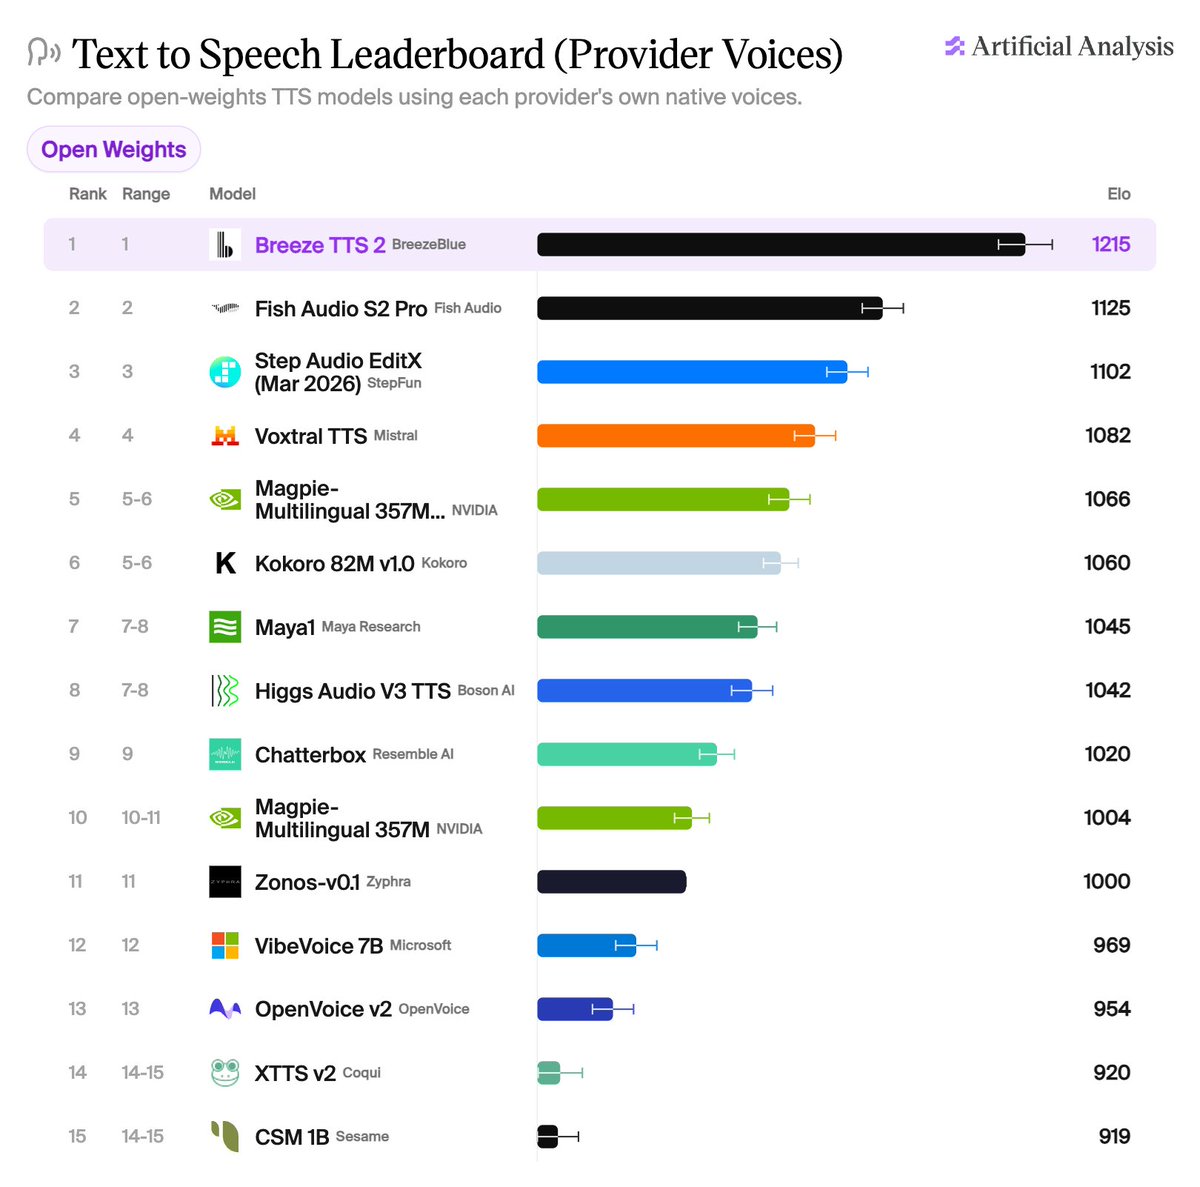
S2 is an open-weights TTS model with free-form inline tags for word-level prosody control, plus fine-tuningTaking a trained model and training it a bit more on your own examples so it gets better at one specific job.Full definition → code and an SGLang streamingSending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.Full definition → engine. Builders of voice agents can self-host it instead of depending on a closed API. Note the community license limits some uses.
Key takeaways · AI-distilled
Fish Audio reuses the same models for data curation and RL rewards: a speech-quality scorer filters training audio and later supplies the acoustic reward, and a transcription model that annotates data later scores intelligibility and instruction-following.
S2 uses a Dual-AR design over a 10-codebook audio codec: a 4B-parameter slow model predicts the main semantic codebook along time while a 400M fast model fills the 9 residual codebooks per step, avoiding the 10x sequence growth of flattening all codebooks.
Fish Audio reports 0.54% Chinese and 0.99% English WER on Seed-TTS Eval, an 81.88% win rate against gpt-4o-mini-tts on EmergentTTS-Eval, and a 0.515 Audio Turing Test score versus 0.417 for Seed-TTS, all self-reported.
Because the architecture mirrors a standard autoregressive LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition →, S2 runs on SGLang with continuous batching and prefix caching. Reused cloning audio hits the prefix cache 86.4% of the time on average, and one H200 reaches a 0.195 real-time factor and about 100 ms to first audio.
Terms in this piece · Glossary
fine-tuning — Taking a trained model and training it a bit more on your own examples so it gets better at one specific job.
streaming — Sending a model's response token by token as it is generated, so the reader sees text immediately instead of waiting for the whole answer.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.