← All IntelIntel / article
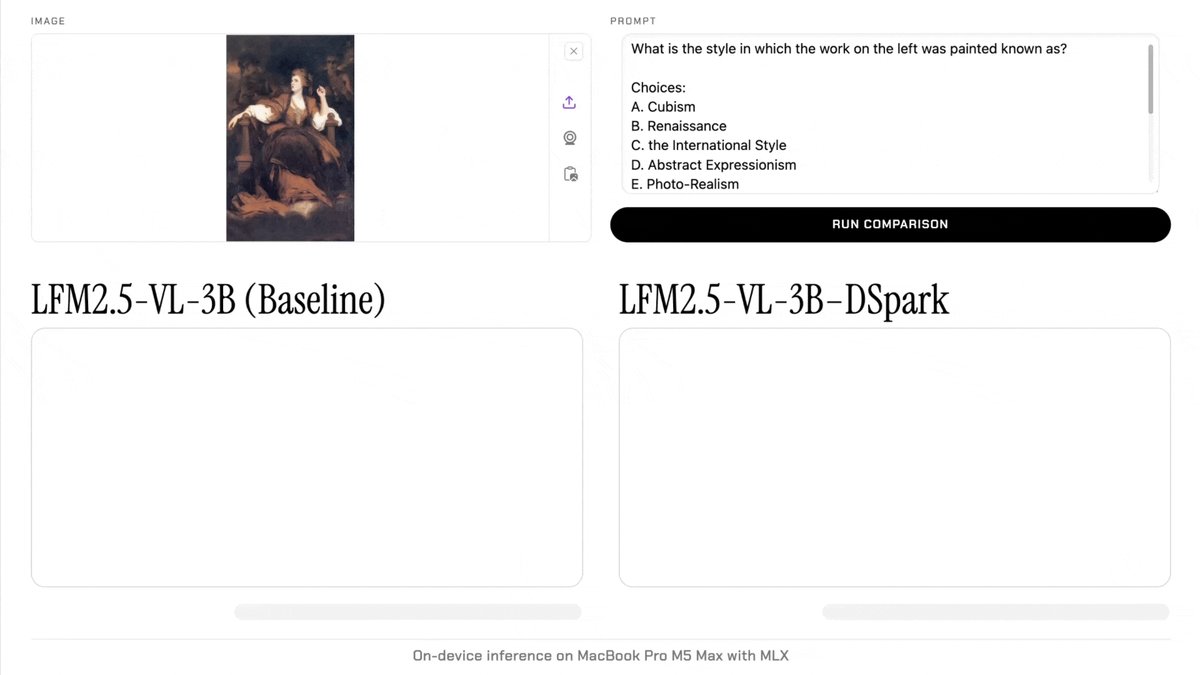
Up to 3.2x Faster Inference with LFM2.5-DSpark
- Source
- huggingface.co
- Date
Why it matters
for LFM2.5 with published draft checkpoints: up to 3.2x faster decode and 57% lower function-calling latency at ~300M extra parameters, with greedy outputs unchanged by construction — a near-free latency win for on-device loops.
Terms in this piece · Glossary
- speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
- inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Read the source huggingface.co
Recommended reads
Comments
Checking sign-in…
Loading comments…