Engrams Embedding Entendre: Codesign for Efficient DRAM/SSD Offloading
Source
Bryan Shan
Author
Bryan Shan
Date
Key takeaways · AI-distilled
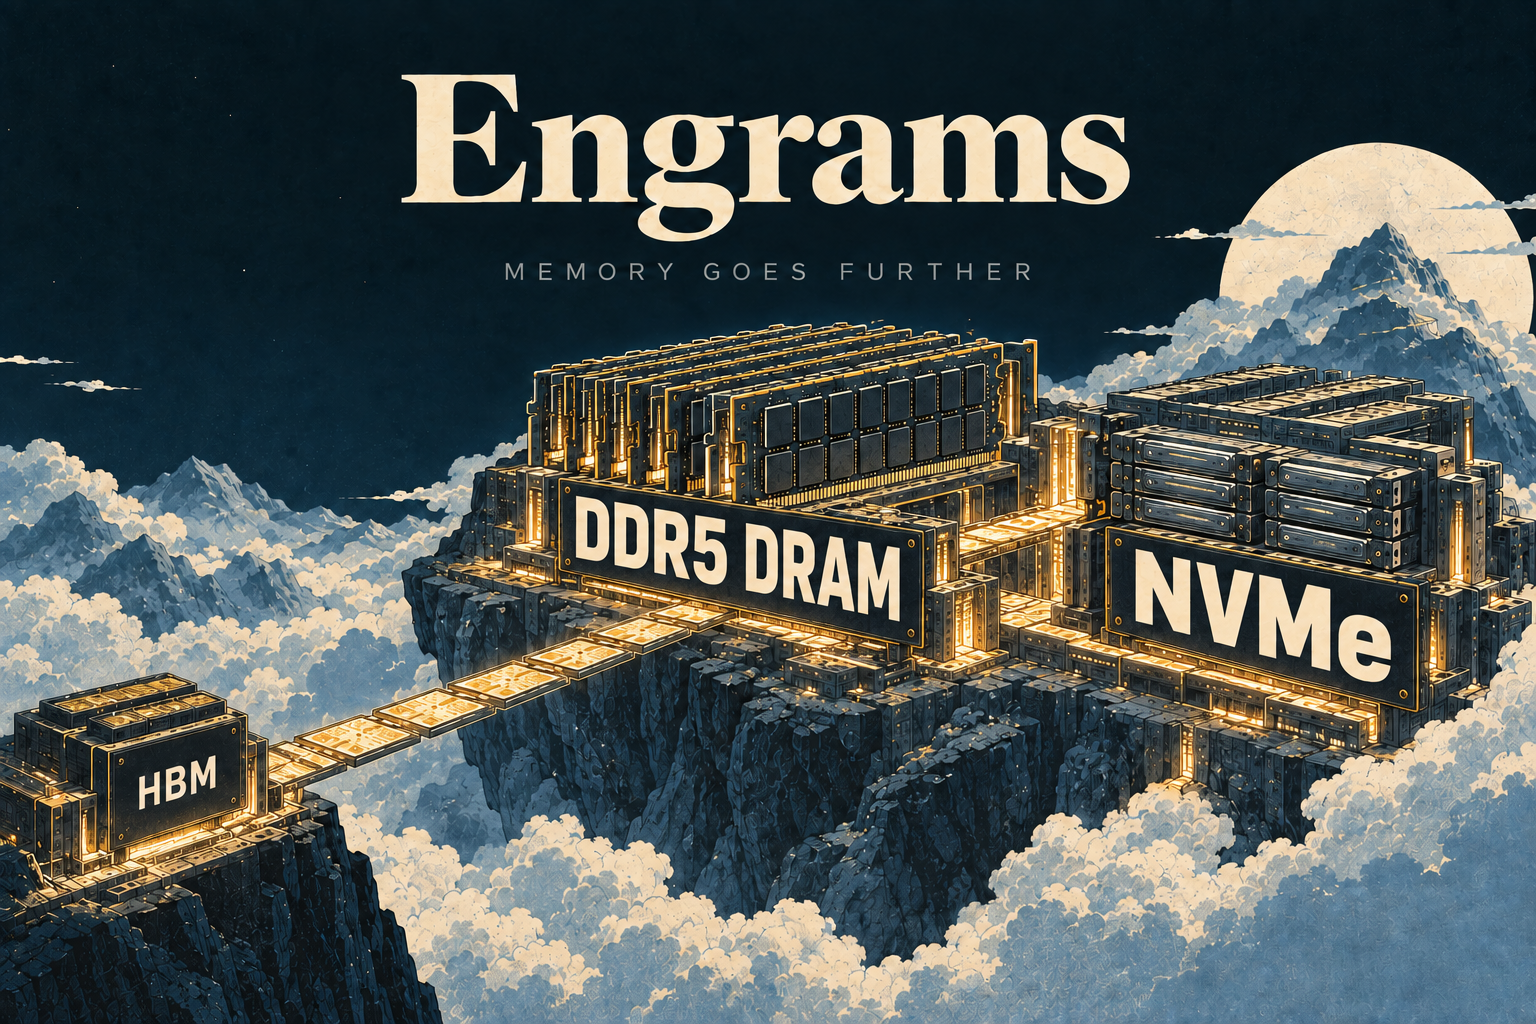
Engram embeddingA list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.Full definition →-row addresses depend only on tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → ID, not hidden state, so the runtime can prefetch rows from host DRAM while earlier layers compute, avoiding the need to move whole weight matrices the way ordinary parameter offloading does.
DeepSeek-V4.1-Flash's Engram table runs about 189 GiB; SemiAnalysis memory-mapped it to SSD and found DRAM-offloading the table can beat keeping it in HBM across most of the pareto frontier, even on GPU SKUs with high HBM capacity.
Probing DeepSeek-V4.1-Flash's Engram gate scores shows it mostly retrieves names, code fragments, relational phrasing, and boilerplate, evidence the learned memory optimizes the training objective rather than deliberately storing 'important' facts.
SemiAnalysis replicated DeepSeek's original two unreleased Engram models on fineweb-edu at an estimated 6E18 FLOPs per run and reproduced the same U-shaped scaling curve and earlier-layer representations resembling later-layer ones.
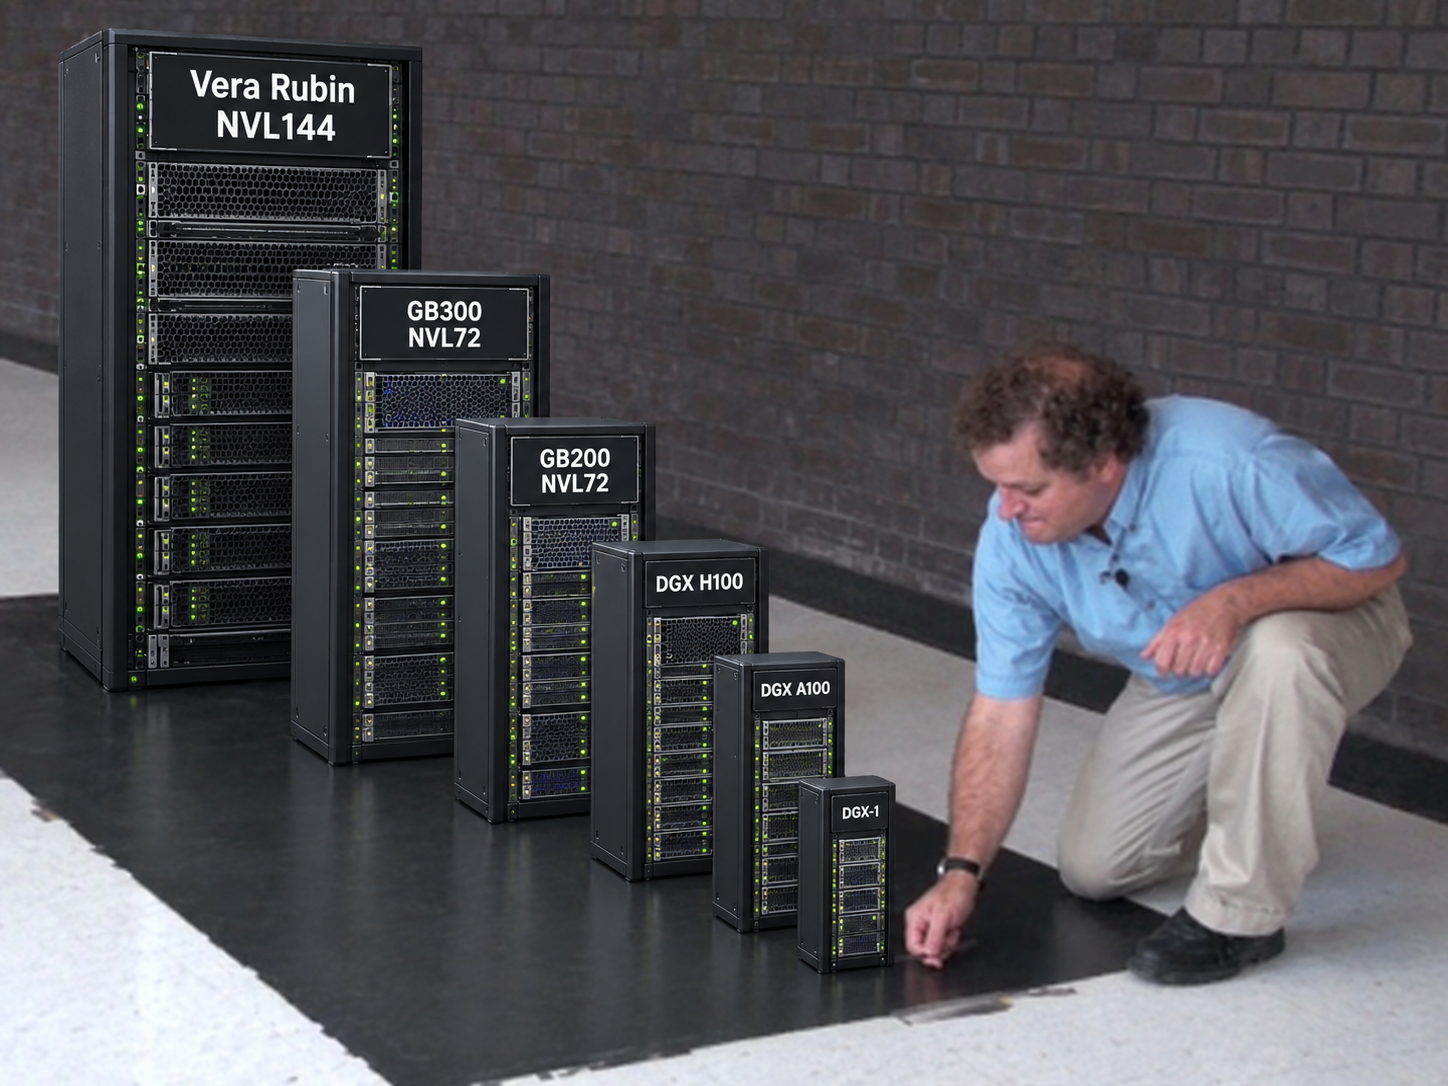
Engram lowers HBM needs per unit of quality but is framed as architecture adapting to constraints, not an escape from HBM demand, arriving as NVIDIA cuts planned Rubin Ultra HBM from 1024GB to about 200GB per chip.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
embedding — A list of numbers representing a piece of text's meaning, so that similar meanings end up numerically close and can be searched.
Why it matters
As HBM supply gets tighter, architecture-level tricks like Engram show one concrete way model designers are offloading memory pressure onto cheaper DRAM/NVMe tiers without sacrificing quality.