Commit0 Library Generation From Scratch 2024 12 02
Source
cohere.com
Author
Cohere
Date
Context
Commit0 tests whether an AI coding AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → can implement an entire software library from a specification and tests. The agent receives a description of the library's programming interface, writes an implementation and uses feedback from checks and execution to revise it. This makes the task depend on coordinating related pieces of code across multiple attempts. The December 2024 research summary reports that interactive feedback helped the tested agents pass more tests, but none fully reproduced the libraries. Its useful finding is that feedback improved partial progress while complete implementation remained unresolved in those experiments.
Terms in this piece · Glossary
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
 postCohere releases open-weights translation model North Small Translate
 articleThe Data Provenance Initiative A Large Scale Audit Of Dataset Licensing And Attribution In Ai 2023 10 25
 articleZero2Repo: Can Coding Agents Build Repositories from Scratch?Pei Yang, Tianyu Shi, Yuhang Yao, Wanyi Chen, Tongyun Yang, Dun Pei, Haonan Wang, Pengbin Feng, Guanxu Yu, Jingchun Huang, Zeyu Zhang, Shuhan Sun, Hao Li, Xiang Li, Jie Xiao, Xinyu Wang, Hanxin Chen, Daqi Li, Qi Jia, Hongshan Lin, Zhizhou Gu, Zijun Tian, Weizhi Du, Lynn Ai, Eric Yang
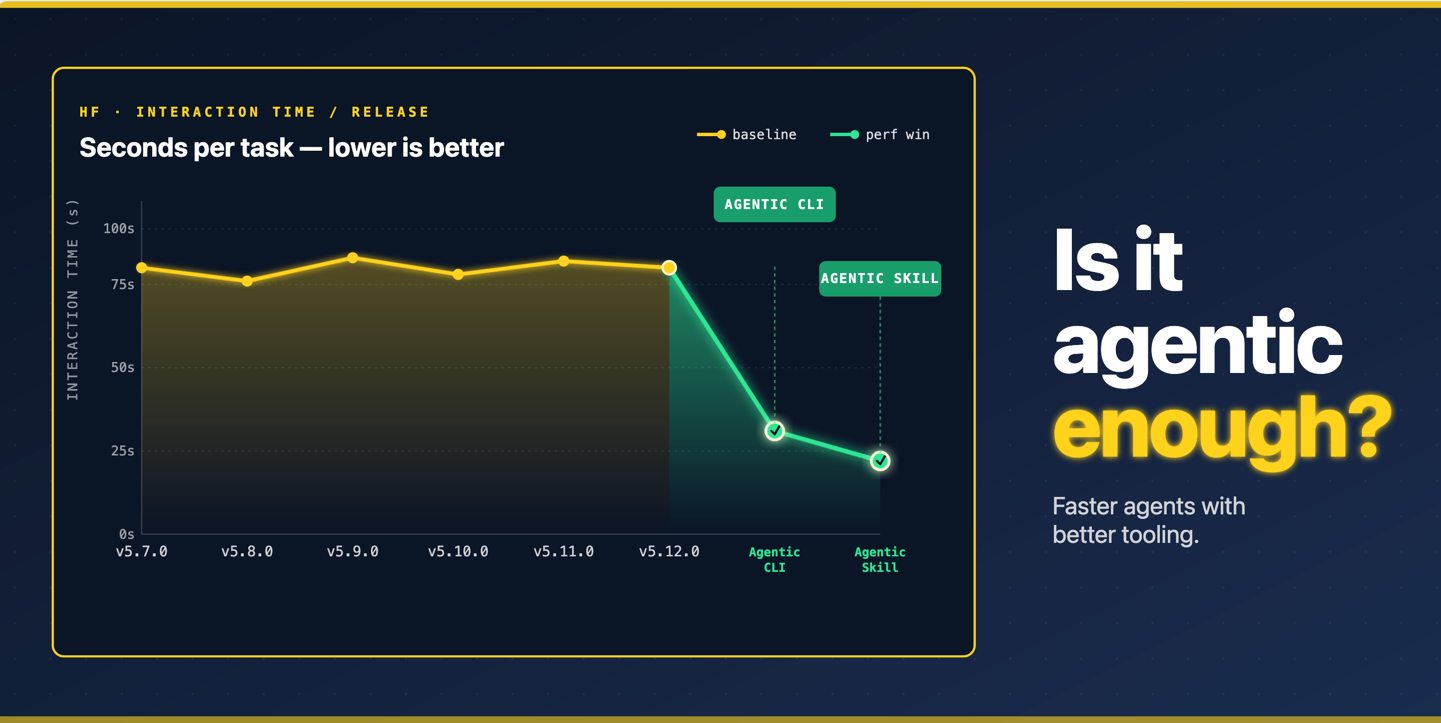 articleIs it agentic enough? Benchmarking open models on your own toolinghuggingface.co
 articleLoopsBench: From Harness Engineering to Loop Engineering in Benchmarking Coding AgentHan Li, Zhemin Fang, Rili Feng, Yingqi Zhao, Jiaheng Liu, Pengfei Gao, He Ye, Dayi Lin, Qingwei Lin, Saravan Rajmohan, Dongmei Zhang