← All IntelIntel / video
Theo's Fable 5.2 review: evals, effort levels and subscription math
- Source
- video.twimg.com
- Author
- Theo - t3.gg
- Date
Why it matters
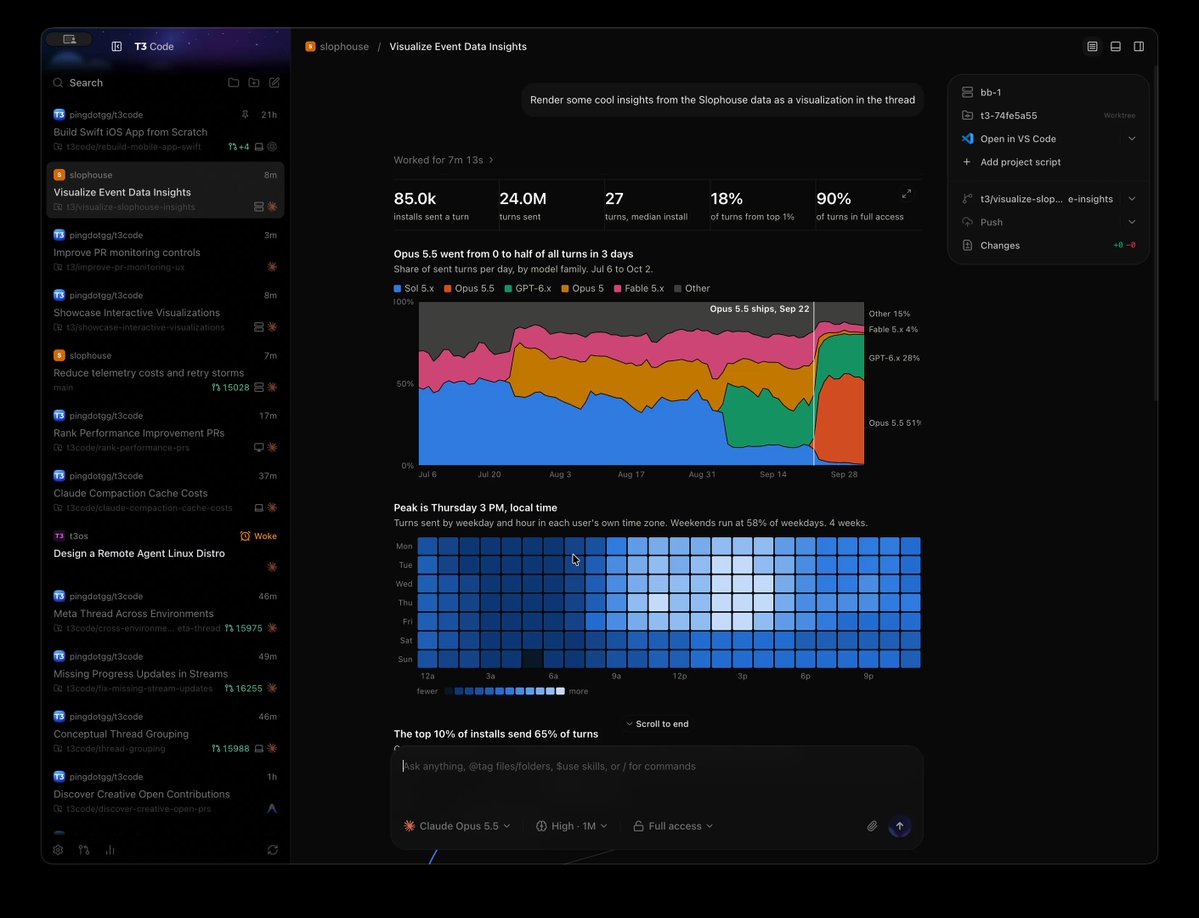
Practical numbers on Fable 5.2: where it trails Opus 5.5 on code review and analysis, why max effort hurts coding, and how Fable limits eat into a $200 plan, so you can budget and choose models.
Terms in this piece · Glossary
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
Read the source video.twimg.com
More from Theo - t3.gg
Comments
Checking sign-in…
Loading comments…