DuplexSpeechBench-IFEval: Evaluating Implicit Instruction Following in Full-Duplex Voice Agents
Source
arxiv.org
Author
Puneet Mathur, Dinesh Manocha
Date
Context
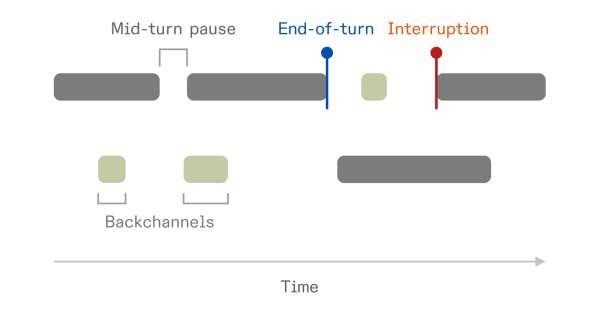
A voice assistant can say things appropriate to its assigned role while mishandling when to speak. DuplexSpeechBench-IFEval separates those abilities: it evaluates conversational timing, including interruptions and yielding, independently from whether spoken content fits a persona. Across 1,038 cases and six speech systems, the authors found different weaknesses. Some systems followed timing expectations less well when those expectations were implied by a role rather than stated explicitly; others produced role-consistent content without adapting their speaking behavior. The benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition → shows why testing a voice AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition →'s wording alone can miss problems in real-time interaction. Study abstract.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.