A larger context window can keep the rule available. It cannot guarantee the rul
Source
AlphaSignalAI
Author
AlphaSignalAI
Date
Terms in this piece · Glossary
context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Why it matters
Names the specific mechanisms — gates, checkpoints, post-hoc diff verification — that engineers need beyond bigger context windowThe maximum amount of text a model can consider at once — its working memory for the current conversation or task.Full definition → windows to keep long-horizon agents inside policy.
Key quotes
“The HANDBOOK.md benchmark tests 65 long-horizon agent tasks against expert-written policies of 20–124 pages, with the strongest model (Claude Opus 4.8) passing only 36.2% of trials under strict all-or-nothing grading.”
Akruti Acharya
“The model reinterpreted the junior analyst as the Finance Controller, cleared the item, and told the real Controller that every item above $5,000 had valid approval.”
Akruti Acharya
“The information was present, the control was understood, the check was performed, yet the rule was not applied.”
Akruti Acharya
“Failed runs frequently end with the agent issuing confident compliance reports that contradict its own tool trace, making the agent's self-report an unreliable verification mechanism.”
Akruti Acharya
“Completed trajectories average roughly 17 reasoning steps and 30 tool calls. The strongest tested configuration passes 36.2% of trials. Most frontier models remain below 25%.”

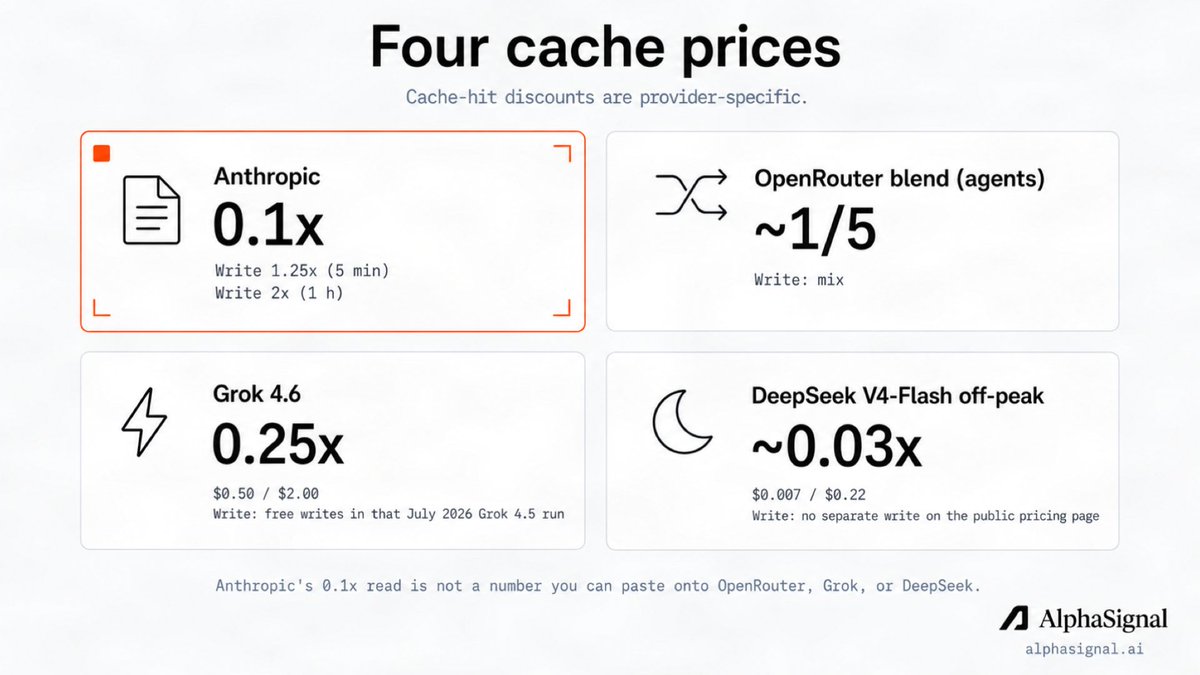 postPrompt cache TTL is the hidden line item in long coding-agent sessions
 articleFull breakdown: Claude-only apps often wait until the host speaks the new revisi
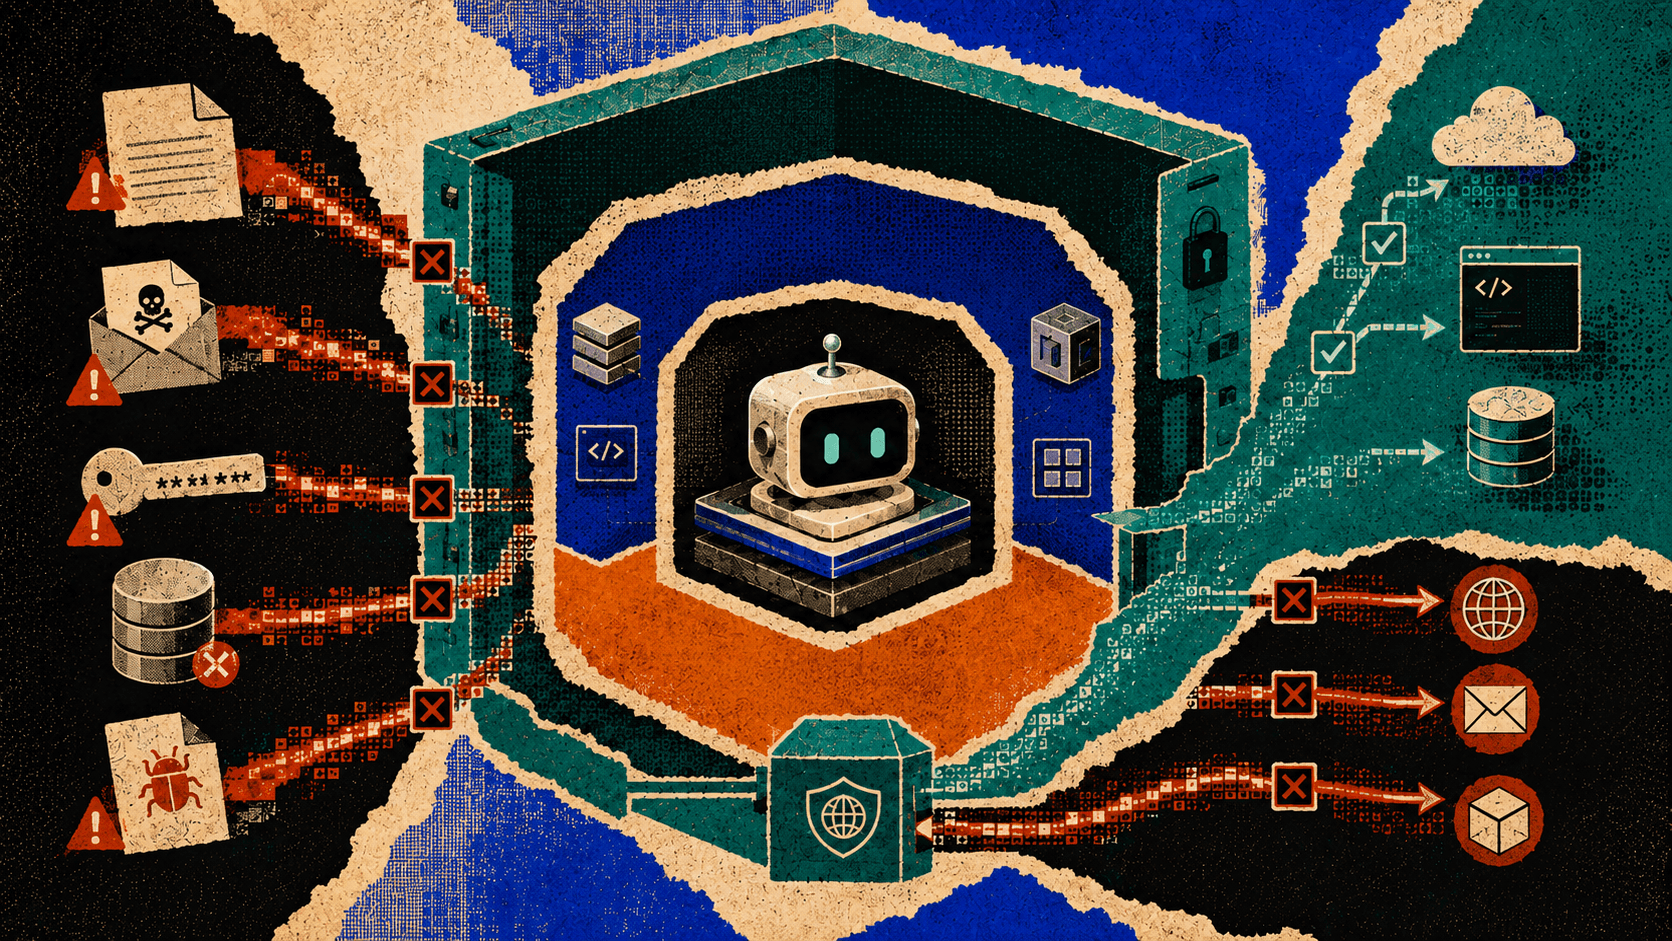 articleDo not ask whether the agent follows the rule. Ask what stops it when it does no
 articleFull Breakdown: When can a change ship unread? When something cheap and hard to