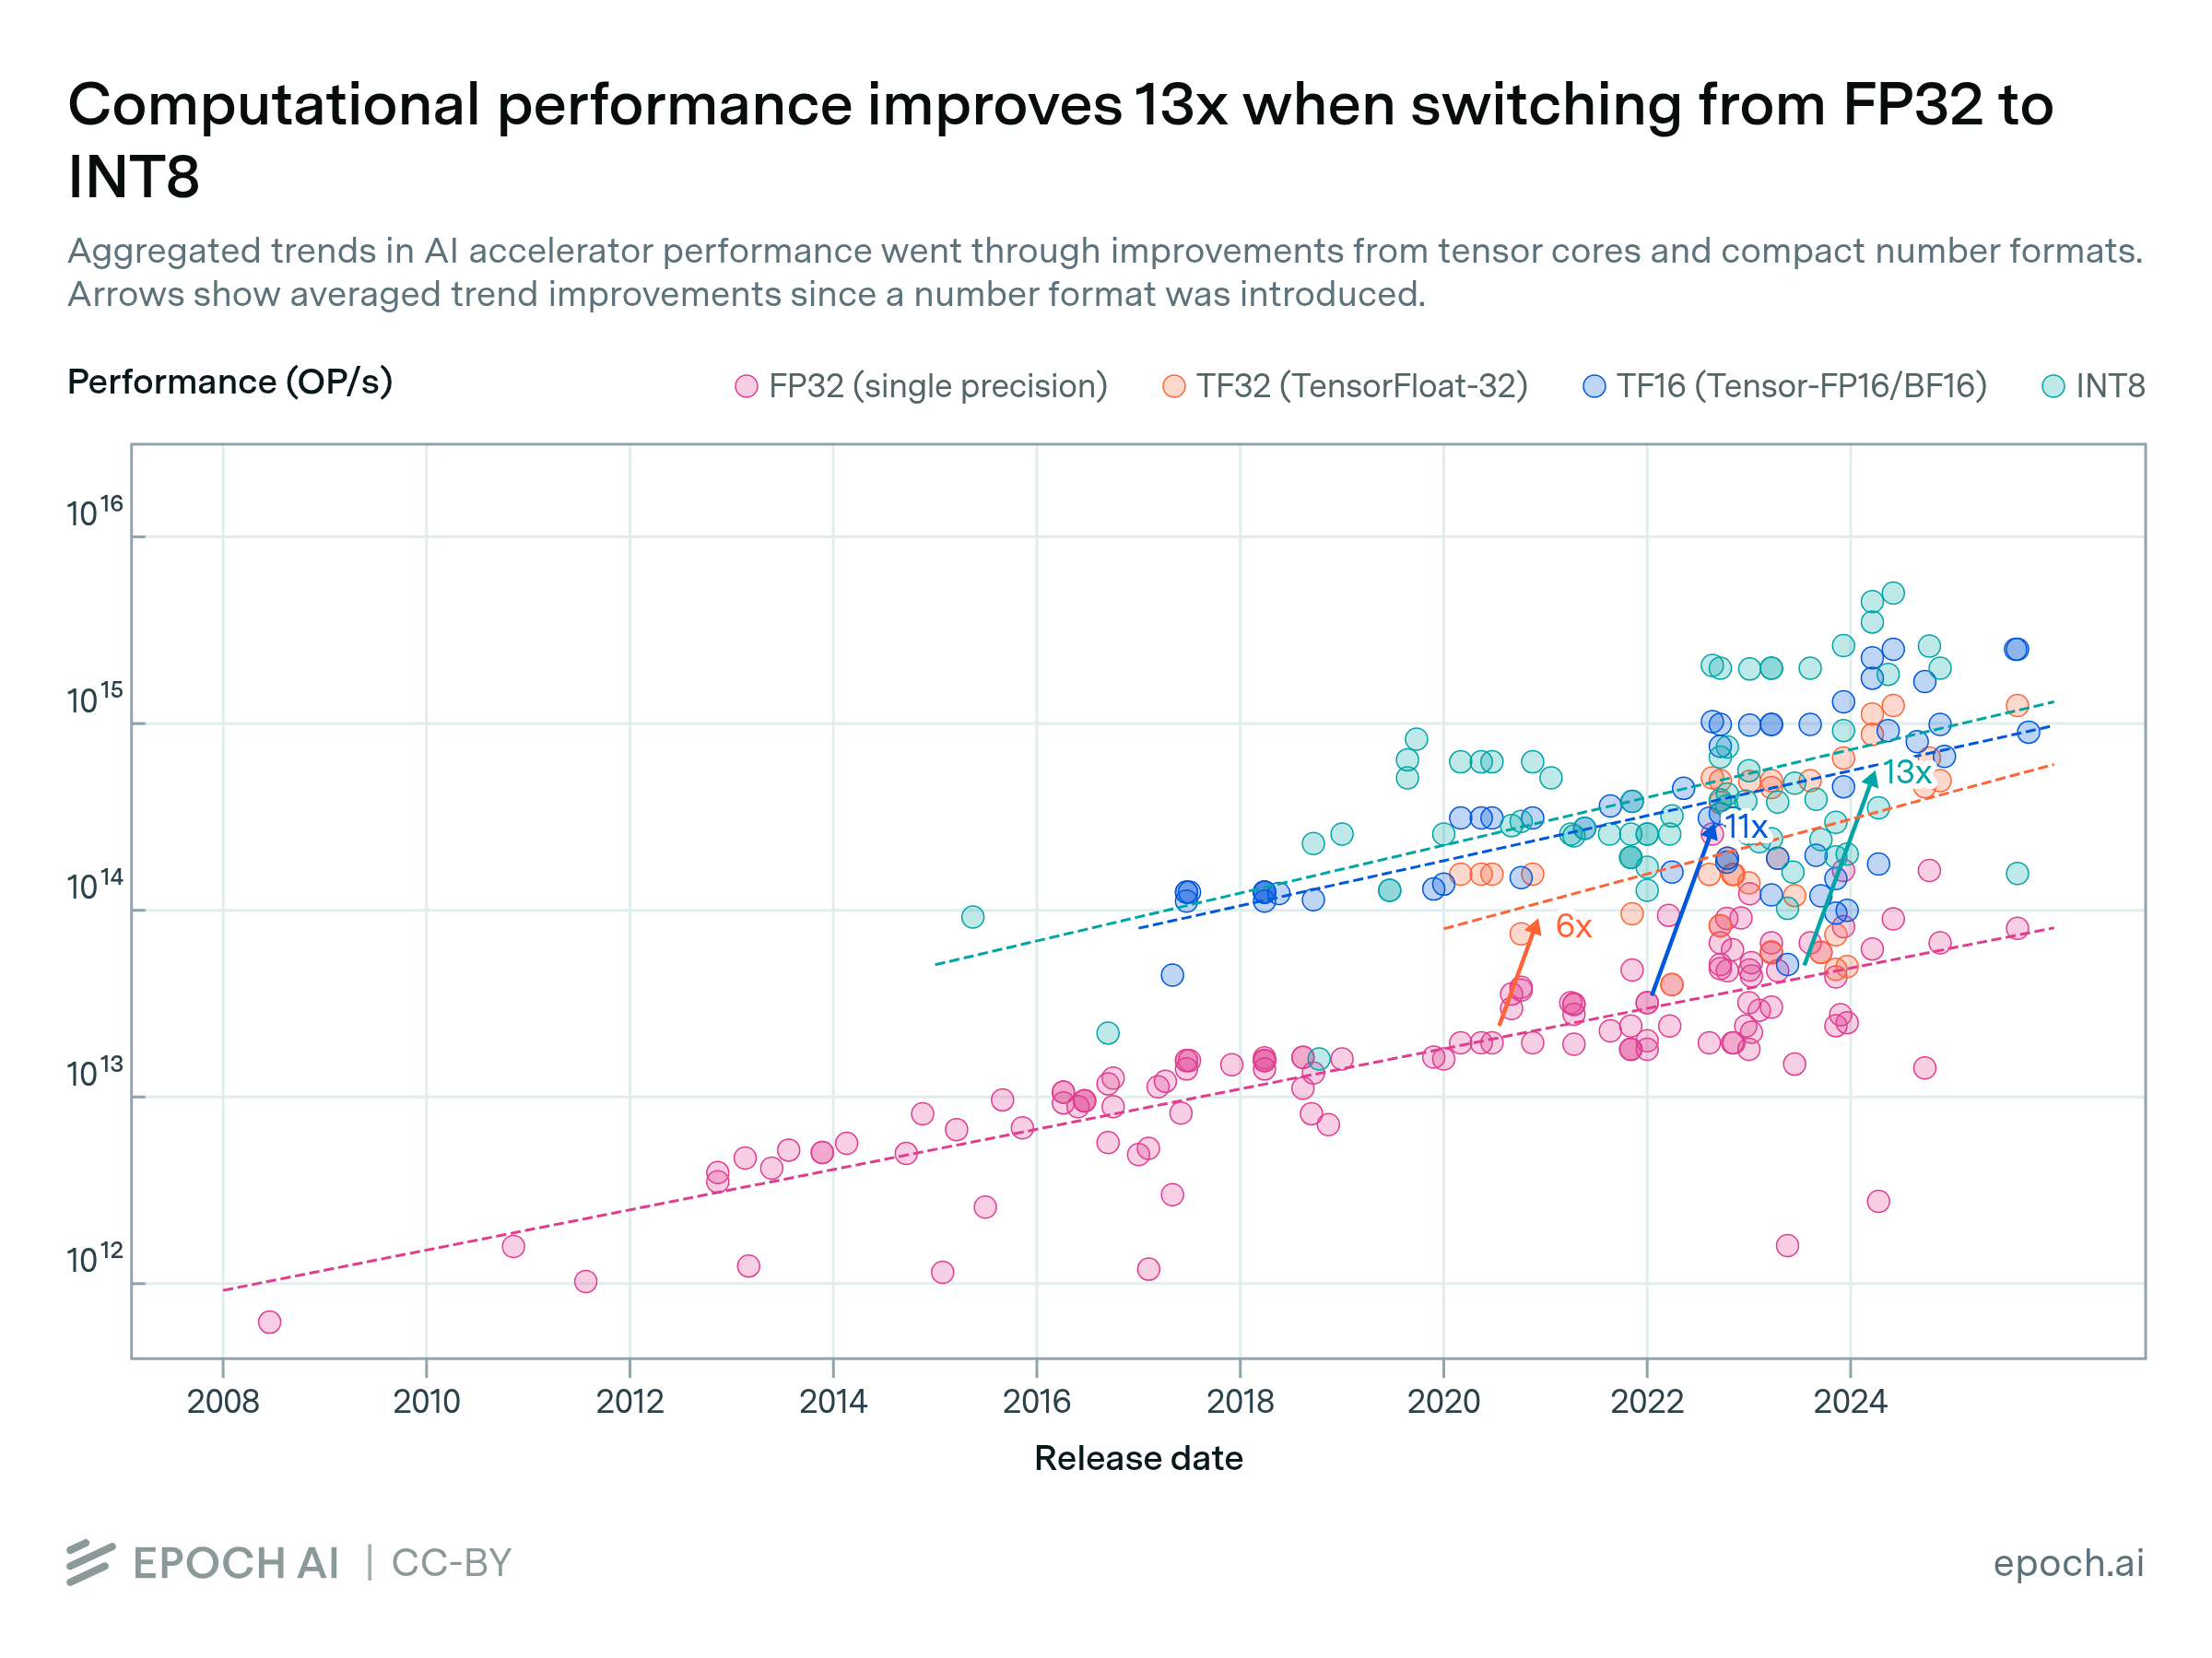
Switching from FP32 to tensor-INT8 yields about 13x average throughput, and 59x on the H100. This quantifies the gain from low-precision formats when planning inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → and training cost.
Terms in this piece · Glossary
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.