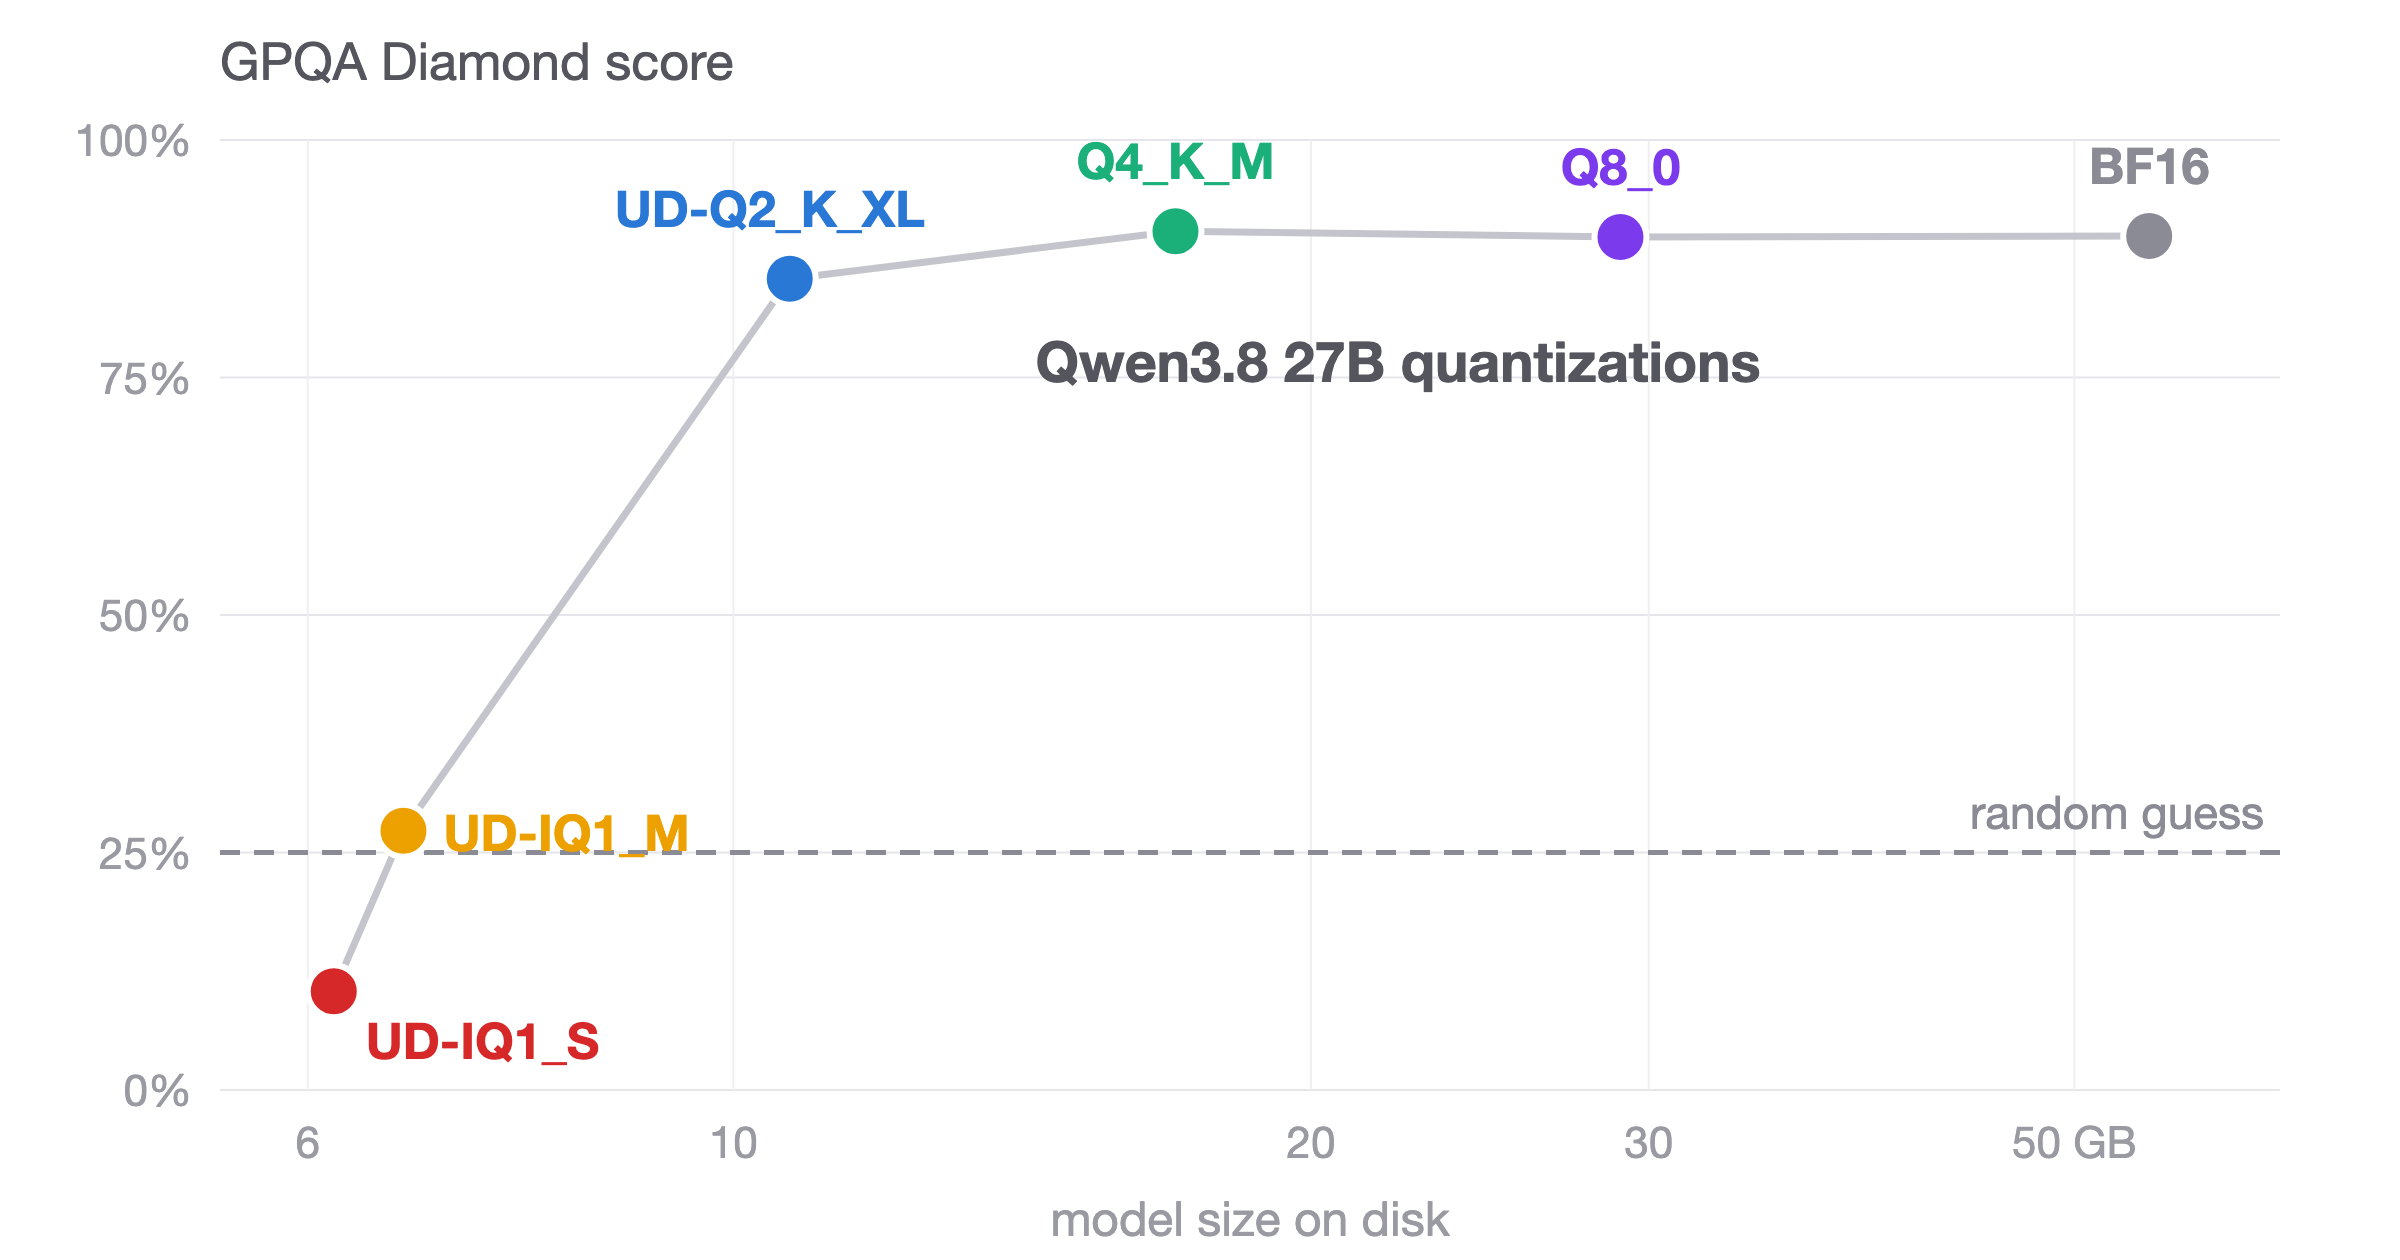
Reducing a model's numerical precision can save substantial memory without producing the same loss on every task. A benchmark study reports that a 17 GB, four-bit version of Qwen3.8 27B matched the 55 GB full-precision version on its Terminal-Bench 2.1 coding test. Much heavier compression performed differently: one-bit versions scored around chance on the science-question test, with longer reasoning sometimes ending in empty answers. These results support four-bit compression for the tested workloads, rather than treating all smaller versions as equivalent. The exact files used for most tests were later replaced, limiting determinismWhether the same input reliably produces the same output — something LLM systems mostly lack, which changes how you test and debug them.Full definition →.
Terms in this piece · Glossary
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
determinism — Whether the same input reliably produces the same output — something LLM systems mostly lack, which changes how you test and debug them.
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.