Introducing Supabase Evals
- Source
- supabase.com
- Author
- Supabase
- Date
Context
Supabase Evals is an open-source framework from the backend platform Supabase that tests whether coding agents can complete backend-development tasks in working environments. Agents use the platform's actual tools to build database structures, repair functions or fix data-access rules. Scoring combines executable checks, such as whether access succeeds, with model judgments for less mechanical questions.
The framework separates broad scenarios from a frequently run suite of known failures. That lets the team check whether a fix keeps working without continually changing the published comparison. Agents receive one retry after failure before grading, so the results describe performance with that recovery opportunity.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- MCP — The Model Context Protocol — an open standard that lets any AI assistant plug into any tool or data source without custom integration code.
- LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
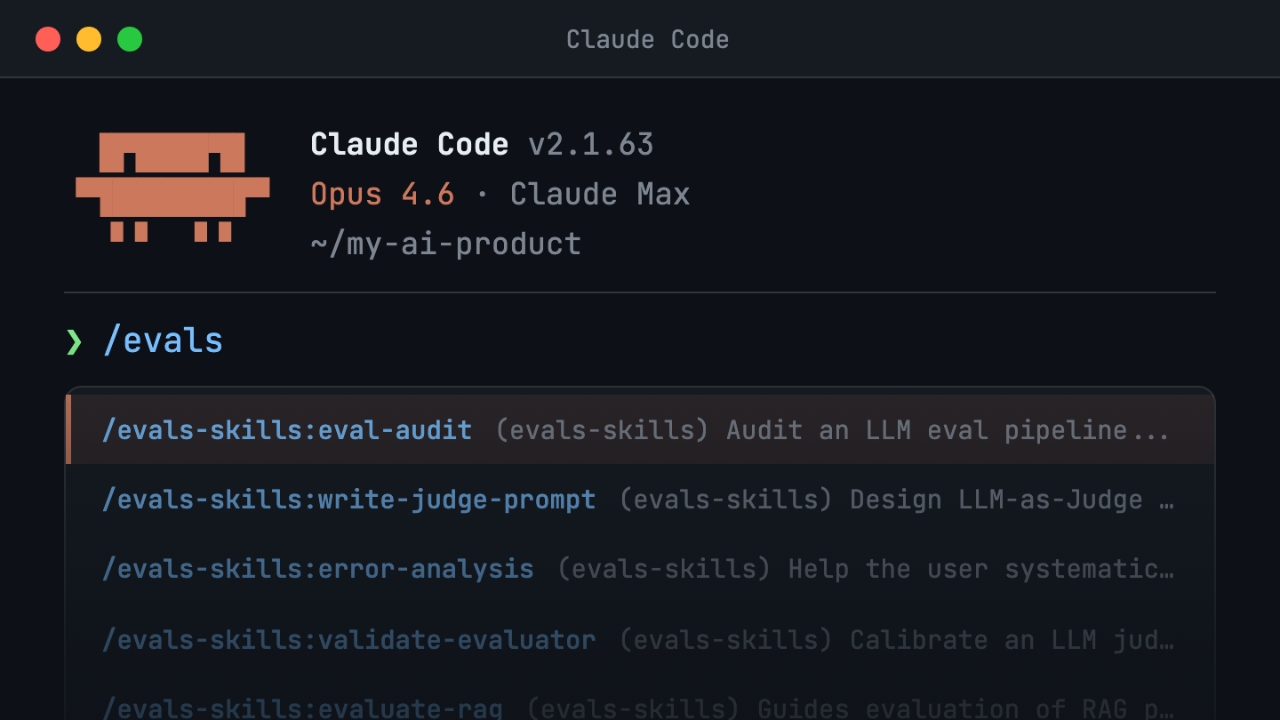
- agent skill — A reusable instruction file that teaches an agent how to do one job well — the procedure, the tools, and what counts as done.

Checking sign-in…
Loading comments…