Do Code Language Models Use Tests? A Behavioral and Representational Study of Test-Driven Code Generation
- Source
- arxiv.org
- Author
- Yunhao Liang, Chengguang Gan, Ruixuan Ying, Hanjun Wei, Zhe Cui, Shiwen Ni
- Date
Context
Adding example tests to a coding prompt can change a model's processing without improving its code. Researchers compared relevant tests with altered, irrelevant and synthetic tests using two Qwen models. Benefits varied by : visible tests substantially helped the smaller model on MBPP+, but effects elsewhere were small or unstable. More tests produced larger changes in internal representations even when correctness stopped improving. For Qwen3.6 on LiveCodeBench, the reported gains from original and synthetic tests were not statistically significant. Whether tests help must therefore be judged through performance on withheld cases, rather than internal changes alone. Study abstract.
- The question is whether a model reads pasted tests as an executable specification or just as extra prompt that perturbs its output. The evidence points mostly at the second.
- Qwen3.6-27B reaches 39.4% on LiveCodeBench from the natural-language prompt alone. Adding the relevant real tests buys 2.9 points (p = .458), and synthetic tests from a stronger model buy 1.7 (p = .701). Both are indistinguishable from noise.
- A shift in the model's internals is not proof the tests were used. Irrelevant tests and assertion-only prompts moved hidden states substantially without improving a single answer.
- Adding tests flips task outcomes in both directions, and after controlling for prompt length the association with harmful flips is substantially stronger than with helpful ones. More test context can cost you correct answers.
- The benefit does not transfer across benchmarks. Visible tests clearly helped Qwen2.5-Coder-7B on MBPP+ but had little or unstable effect on HumanEval+ and LiveCodeBench, so a win on one suite proves nothing about the next.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
“Public tests are widely used to guide large language model code generation, but whether models treat them as executable specifications or merely as extra prompt context remains unclear.”
“For Qwen3.6 on LiveCodeBench, the natural-language-only pass rate rises from 13.1% to 39.4%, yet relevant original tests add only 2.9 percentage points (p = .458), and synthetic high5 tests add 1.7 points over their matched baseline (p = .701).”
“More tests produce larger representation shifts, but accuracy gains quickly saturate or disappear; assertion-only and irrelevant-test prompts can strongly alter hidden states without improving correctness.”
“These results show that tests influence code models through both semantic guidance and prompt-context perturbation, and that representational change alone does not demonstrate effective test utilization.”
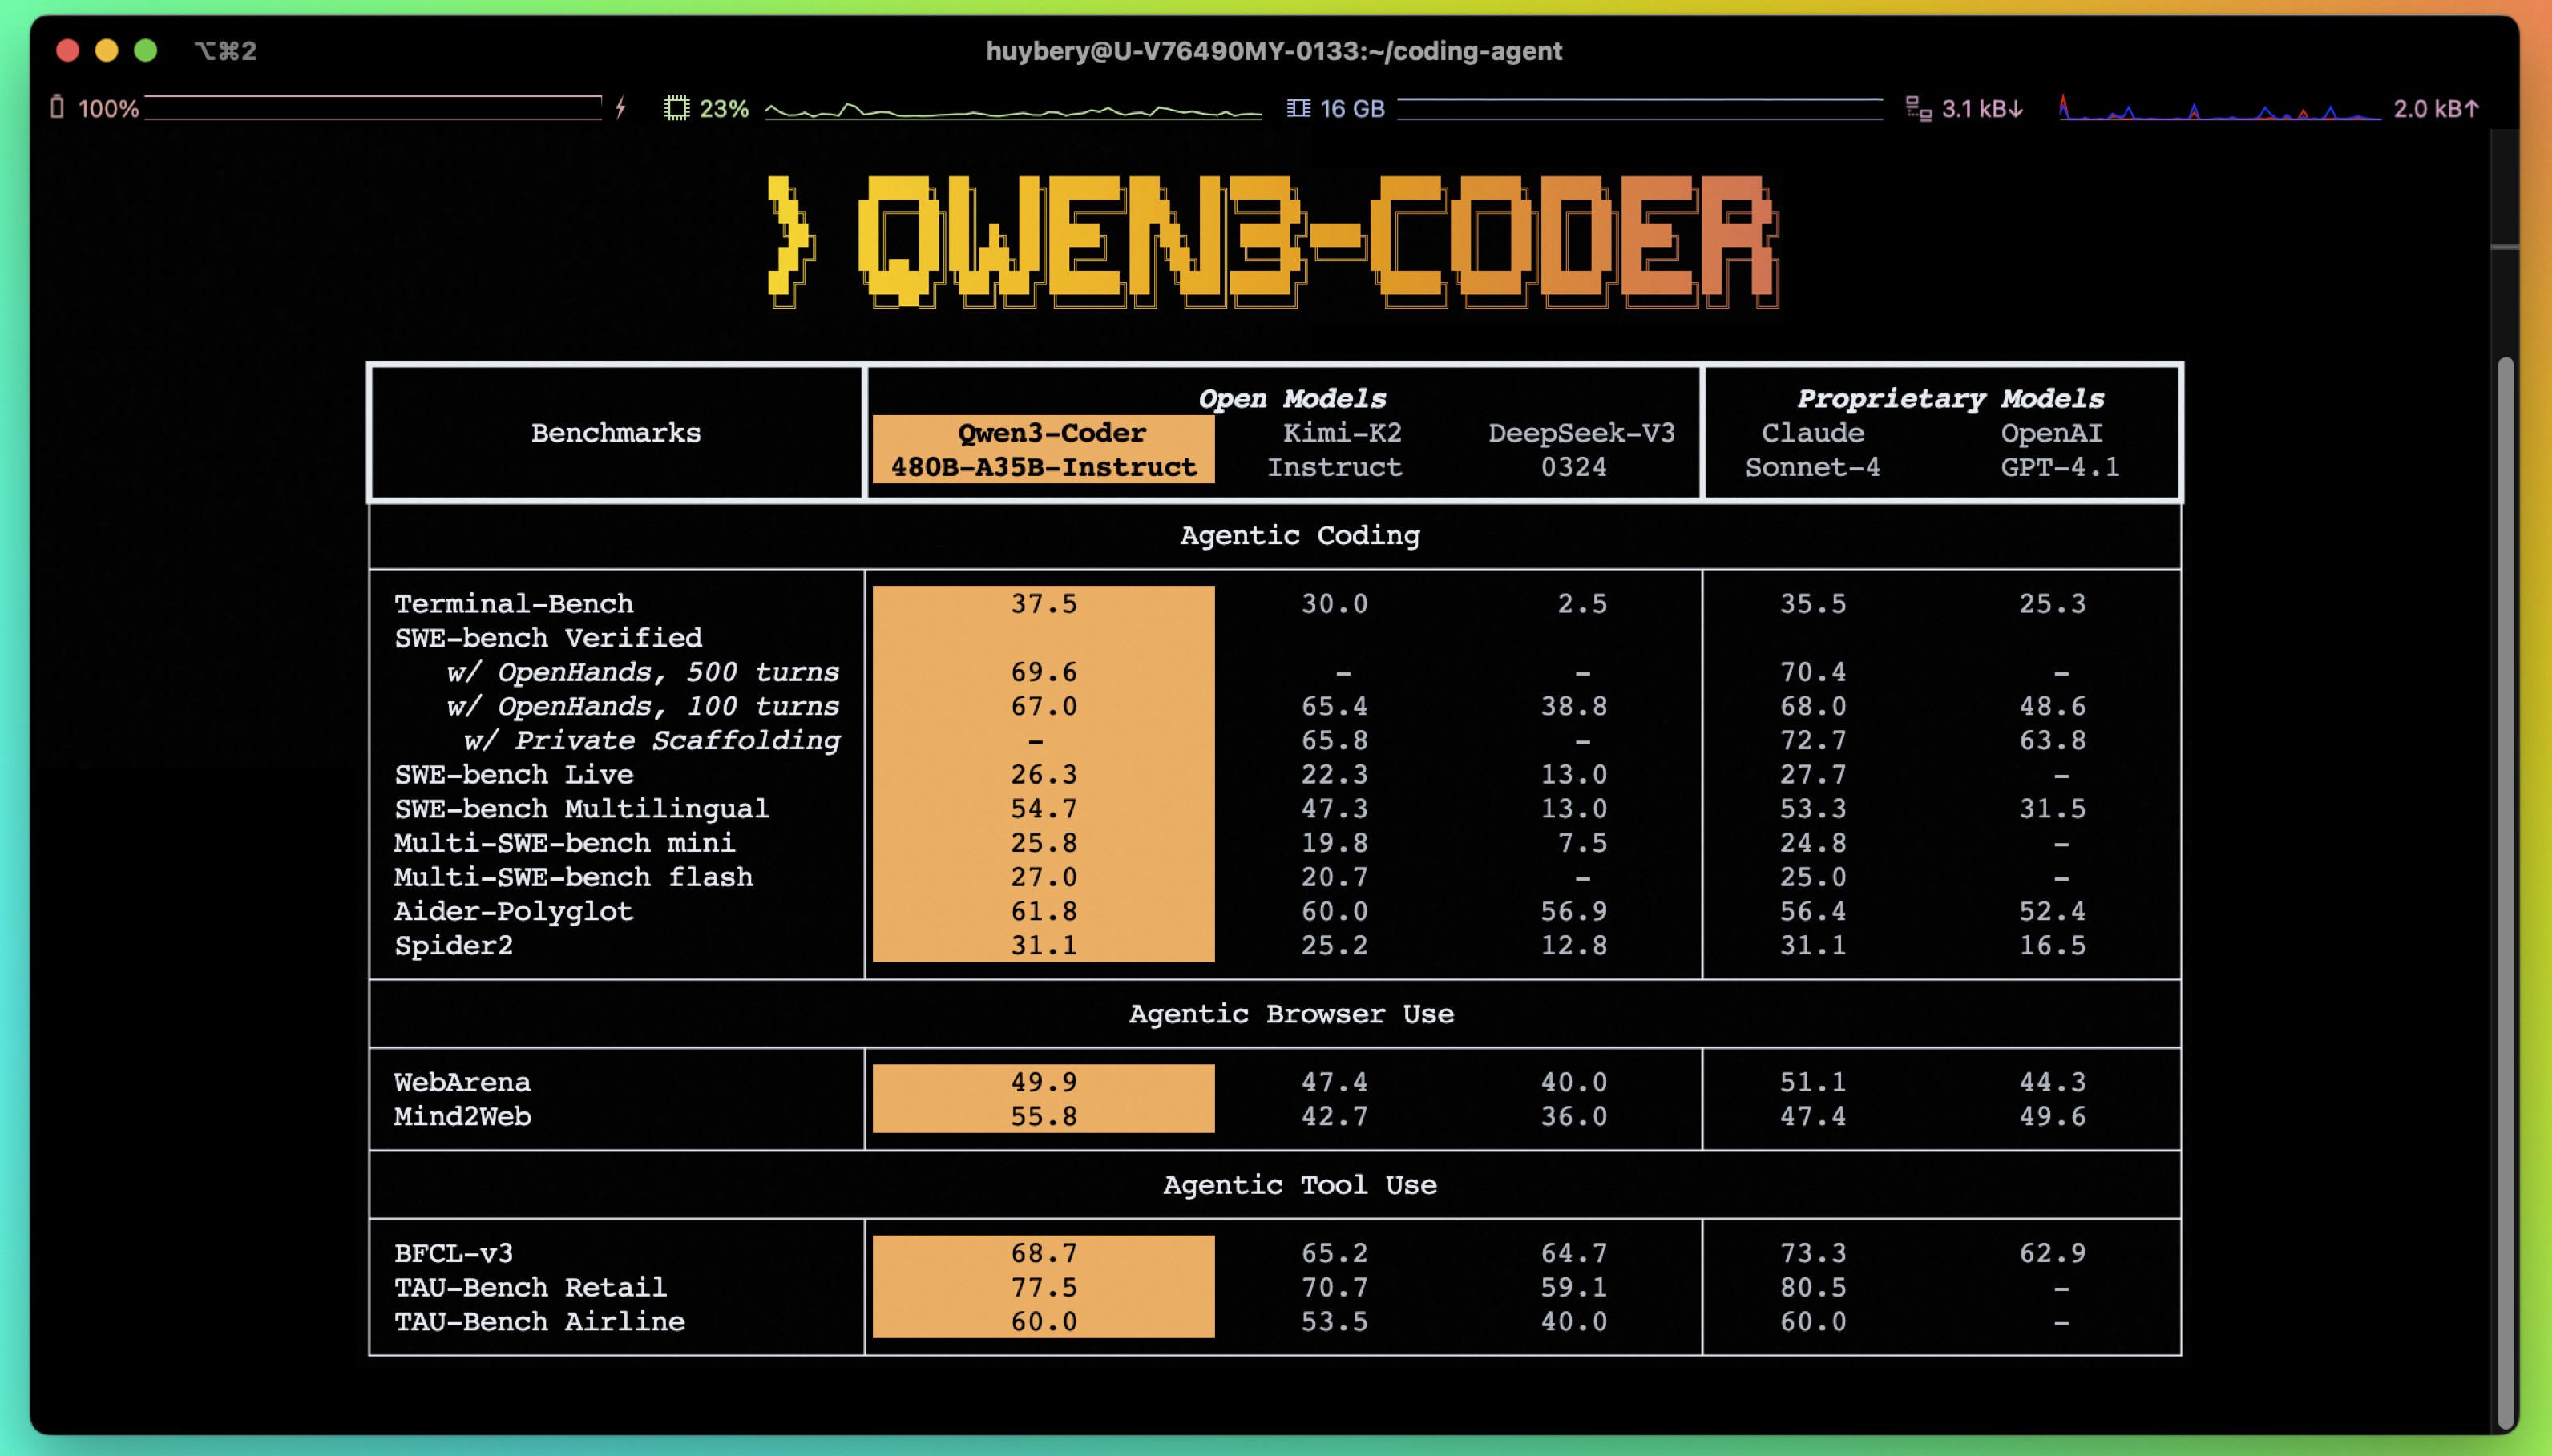 articleQwen3-Coder: Agentic Coding in the WorldQwen Team
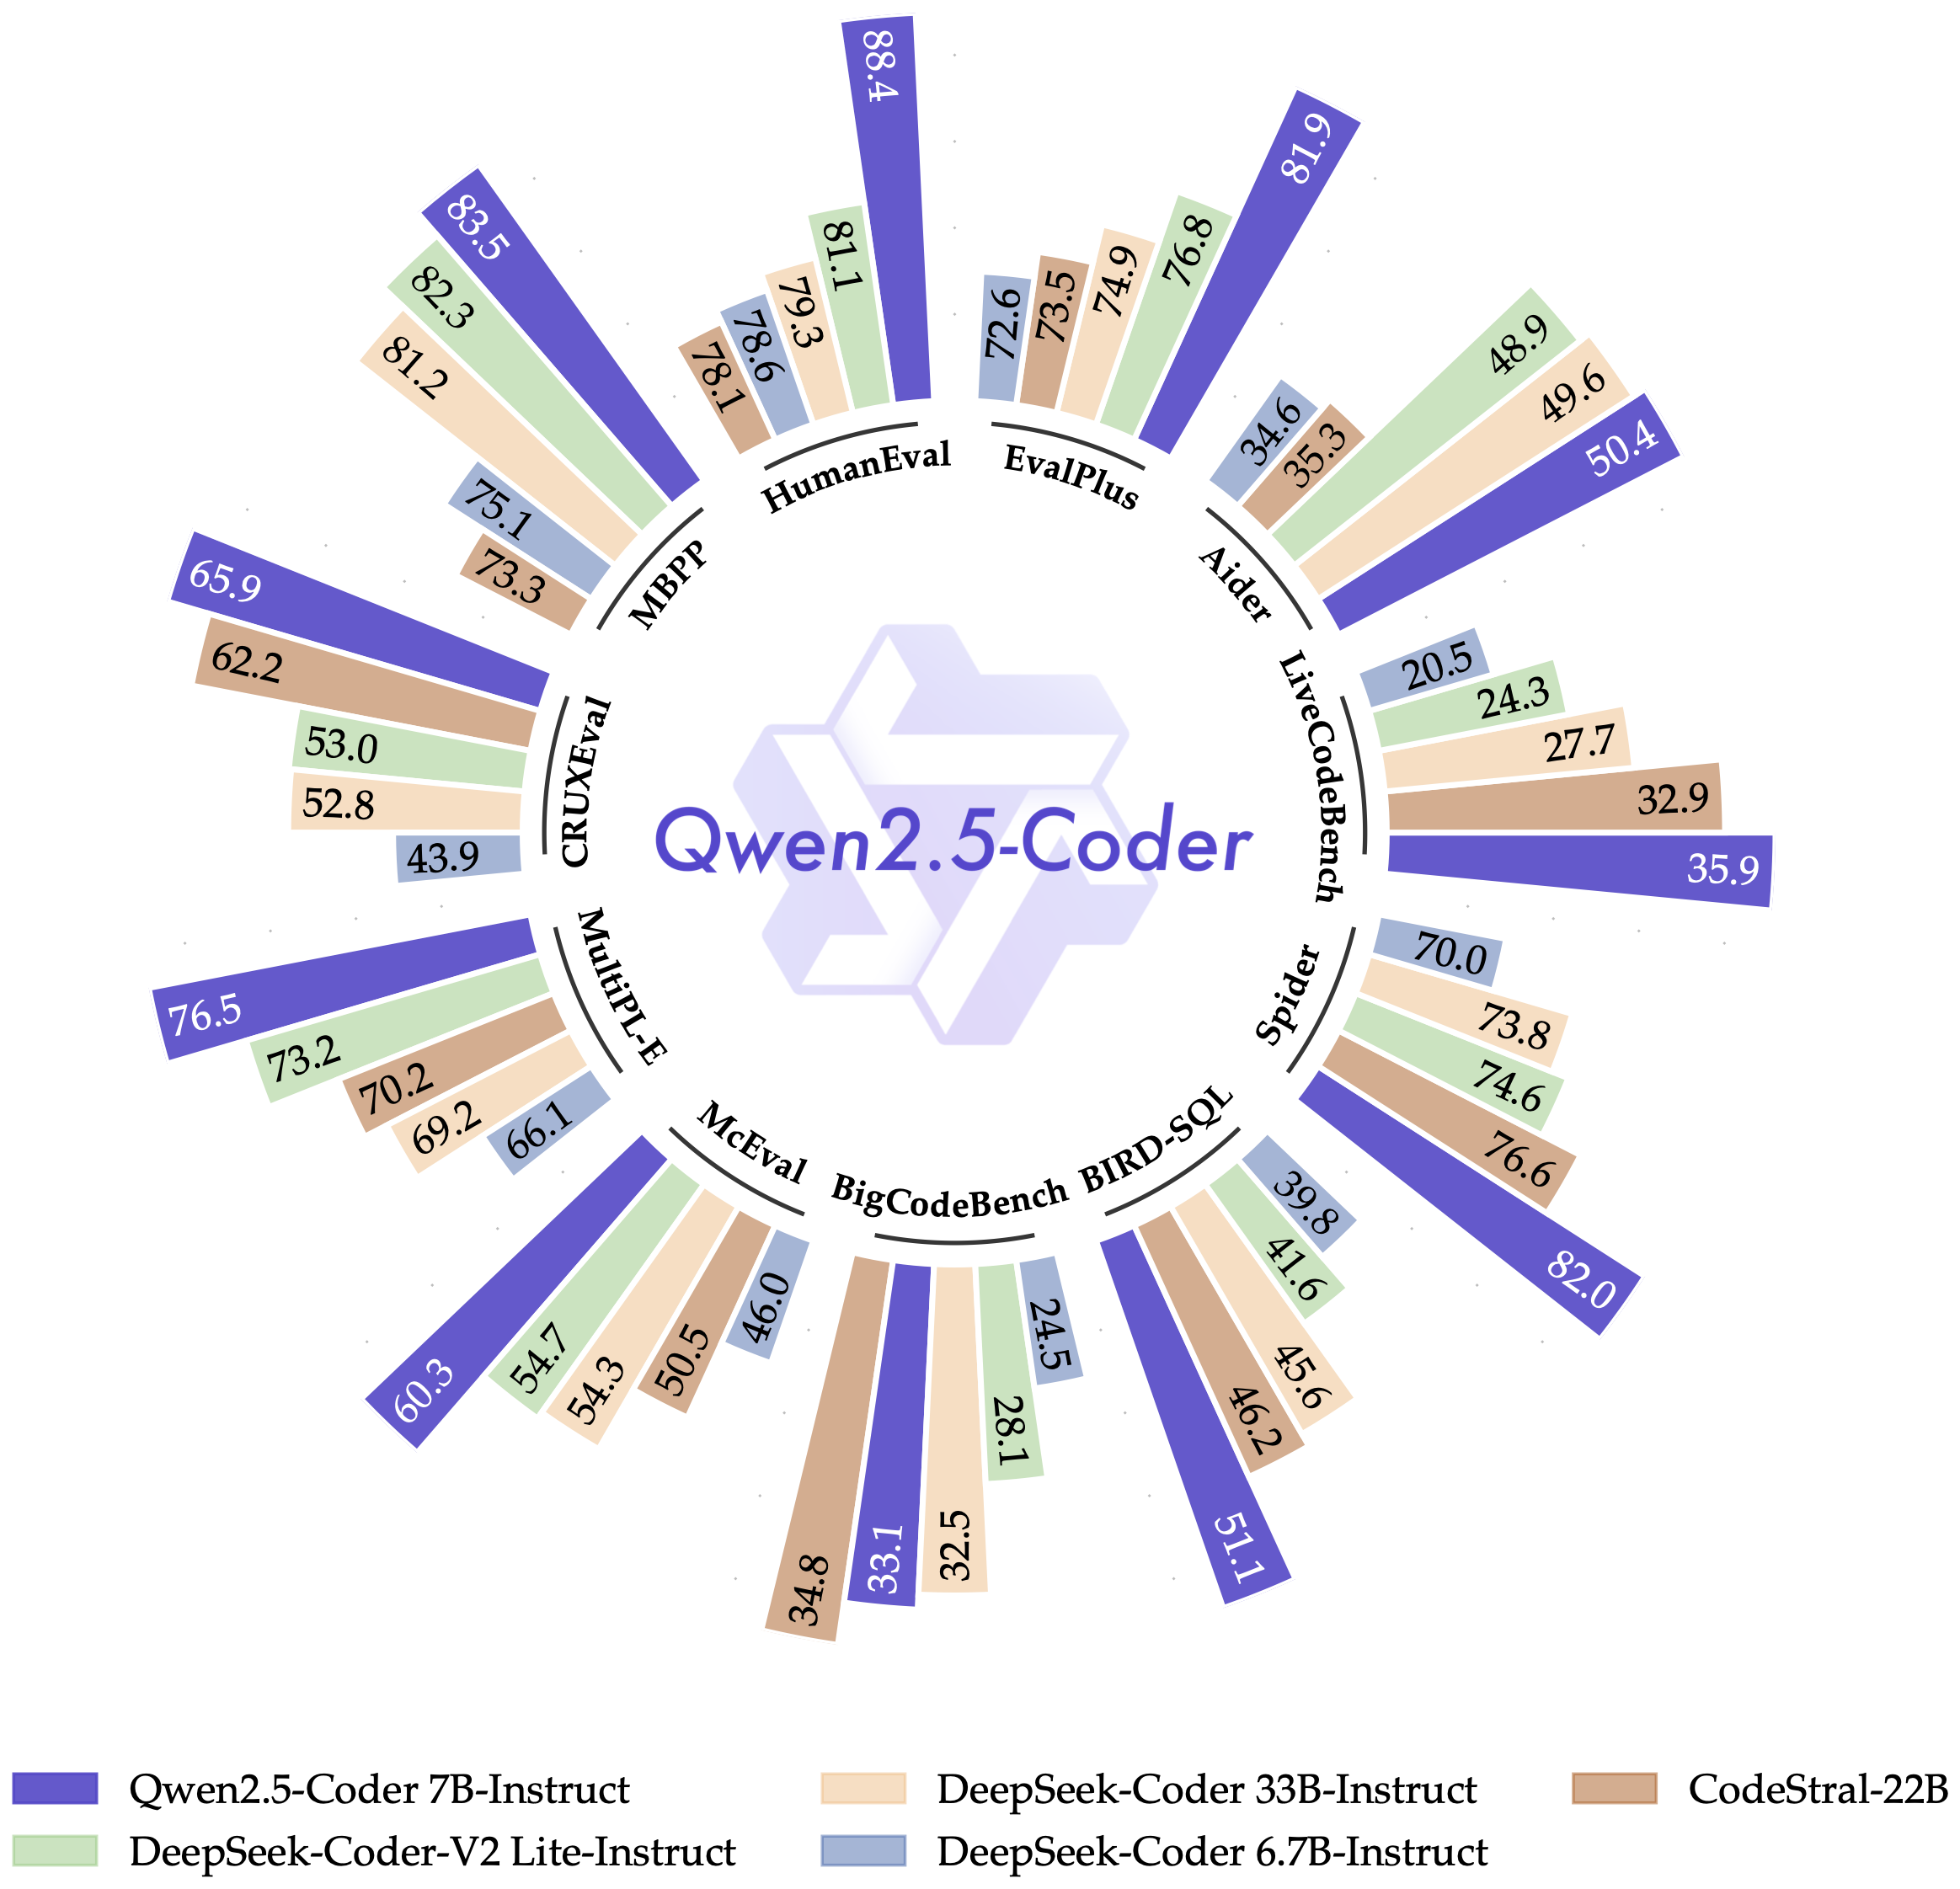 articleQwen2.5-Coder: Code More, Learn More!Qwen Team
 articleA Study on the Impact of Natural Language Differences in Prompts on Automatic Code Generation Using LLMsHaruka Tokumasu, Masanari Kondo, Alexander Serebrenik, Dong Wang, Kei Koyanagi, Kotaro Noguchi, Naoyasu Ubayashi, Yasutaka Kamei
Checking sign-in…
Loading comments…