open weights — A model whose trained parameters are published for anyone to download and run — unlike API-only models you can access but never possess.
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Why it matters
It provides evidence that long-horizon tool-use post-training produces transferable AI agentAn AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.Full definition → behaviors (goal tracking, repair stability, verification) rather than benchmark-specific overfitting, which matters for anyone deciding how to train or evaluate agentic models.
Key quotes
“We argue that the discriminating question is behavioral, namely how a trained agent acts, and that cross-benchmark transfer is the right place to look for it.”
“These results provide descriptive evidence that long-horizon multi-tool post-training can change ways of working that transfer beyond its training domain.”
“a policy can get rewards by exploiting environment-specific regularities (tool schemas, grader parsing, task templates) rather than by acquiring transferable skill”

 articleBacktrader-Bench: Benchmarking LLM Agents on Algorithmic Trading with Self-Generated MCQsRuoxi Zhao, Maziar Raissi
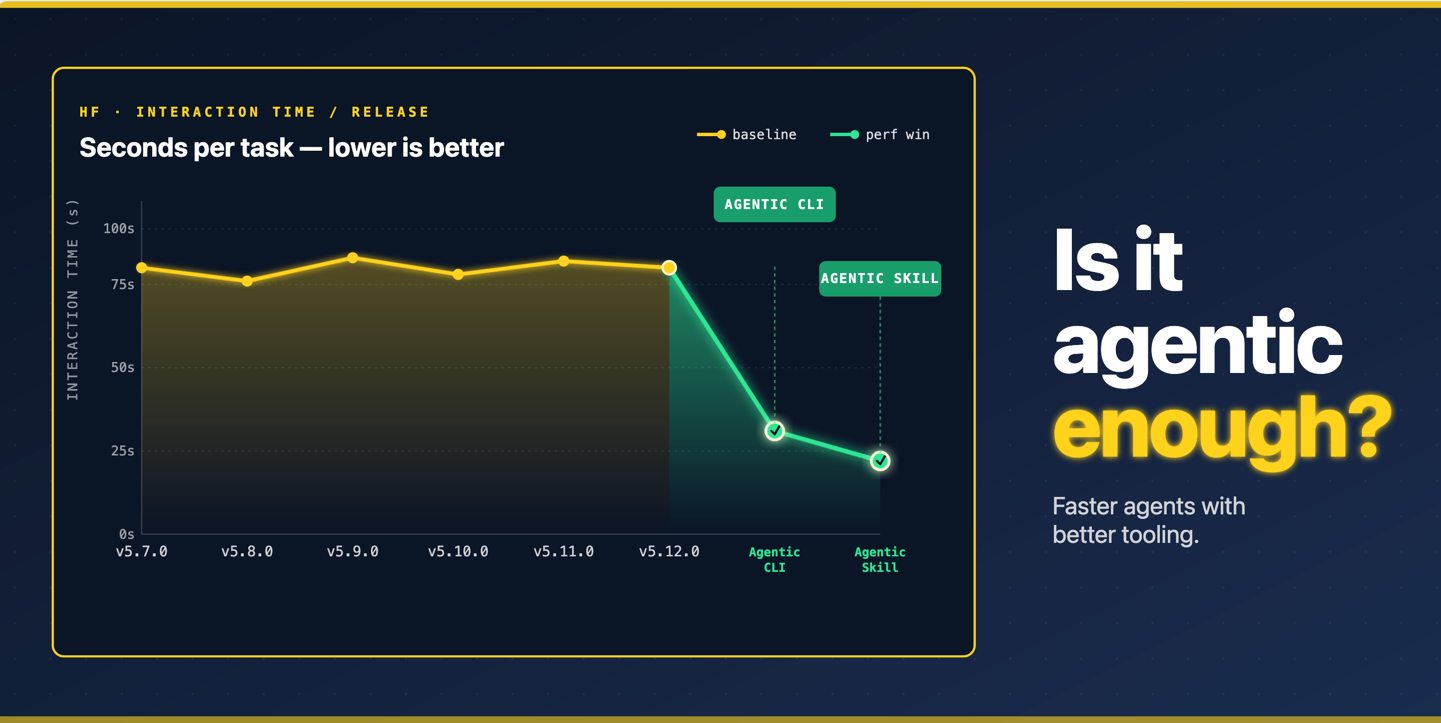 articleIs it agentic enough? Benchmarking open models on your own toolinghuggingface.co
 articleMindForge: Teaching Small Language Models Whole-Life-Cycle Software Engineering via Source-Free Program SynthesisYihao Chen, Shi Chang, Khaled Chawa, Feng Lin, Boyuan Chen, Shaowei Wang, Ahmed E. Hassan