Applying Transformer Inference Arithmetic to Hopper and Blackwell GPUs
- Source
- x.com
- Date

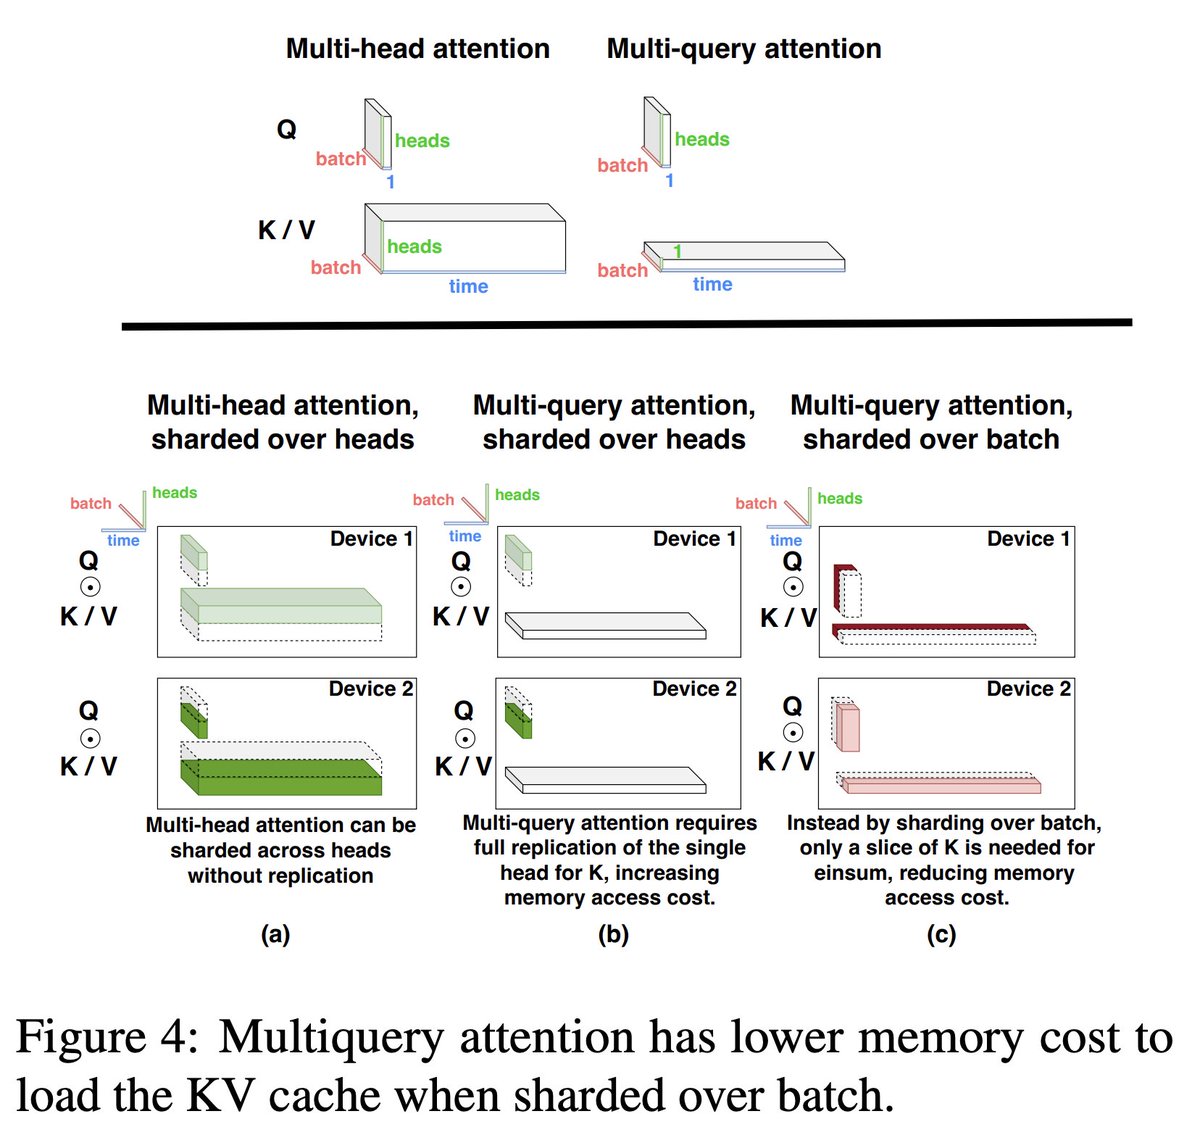
we launched the most comprehensive ai performance engineering repo in the world follow and save to keep up with the series. links in thread 🧵 part 6: Transformer Inference Arithmetic Carol Chen (kipply) builds an approximate inference cost model around the work each token requires, the bytes the GPU moves, and communication between GPUs. it's a useful starting point for investigating latency and throughput on H200s, B200s, and B300s. Chen's examples use A100 GPUs. the applications below combine that model with NVIDIA's Hopper and Blackwell documentation: - prefill and decode expose different amounts of token parallelism. prefill processes prompt tokens together, giving projection and feed-forward matrix multiplies more weight reuse. small-batch decode has less reuse and can spend more time loading weights than computing with them. profile each phase. - batching can raise arithmetic intensity in projection and feed-forward matrix multiplies: more computation for each byte of weights loaded. that can improve throughput, but larger batches can increase key-value (KV) cache requirements and the time between output tokens. tune batch size against the latency target, using…

Context
wafer_ai is publishing a series on AI performance engineering, and in part 6 it applies Carol Chen's inference arithmetic to Nvidia's H200, B200 and B300 GPUs in a long post. Chen, who writes as kipply, built an approximate cost model for running a language model from three quantities: the work each token requires, the bytes the GPU has to move, and the communication between GPUs. Her examples used older A100 GPUs. wafer_ai pairs her model with Nvidia's Hopper and Blackwell documentation and turns it into a tuning method: predict which resource limits a given setup, change the serving or kernel configuration that relieves it, and check the result against the workload's latency target.
The clearest example is the difference between the two phases of serving a request. In prefill, the model processes the prompt's tokens together, so each weight it loads from memory is reused across many tokens. In decode, which produces the output, small batches offer much less reuse, and the GPU can spend more time loading weights than computing with them. Batching more requests raises arithmetic intensity, the amount of computation done for each byte of weights loaded, which can raise throughput. Larger batches also need more , the keys and values retained for earlier tokens that decoding reads at every step, and they can lengthen the time between output tokens. The post therefore treats batch size as something to tune against the latency target with realistic prompt and output lengths, and says to reject throughput gains that break that target.
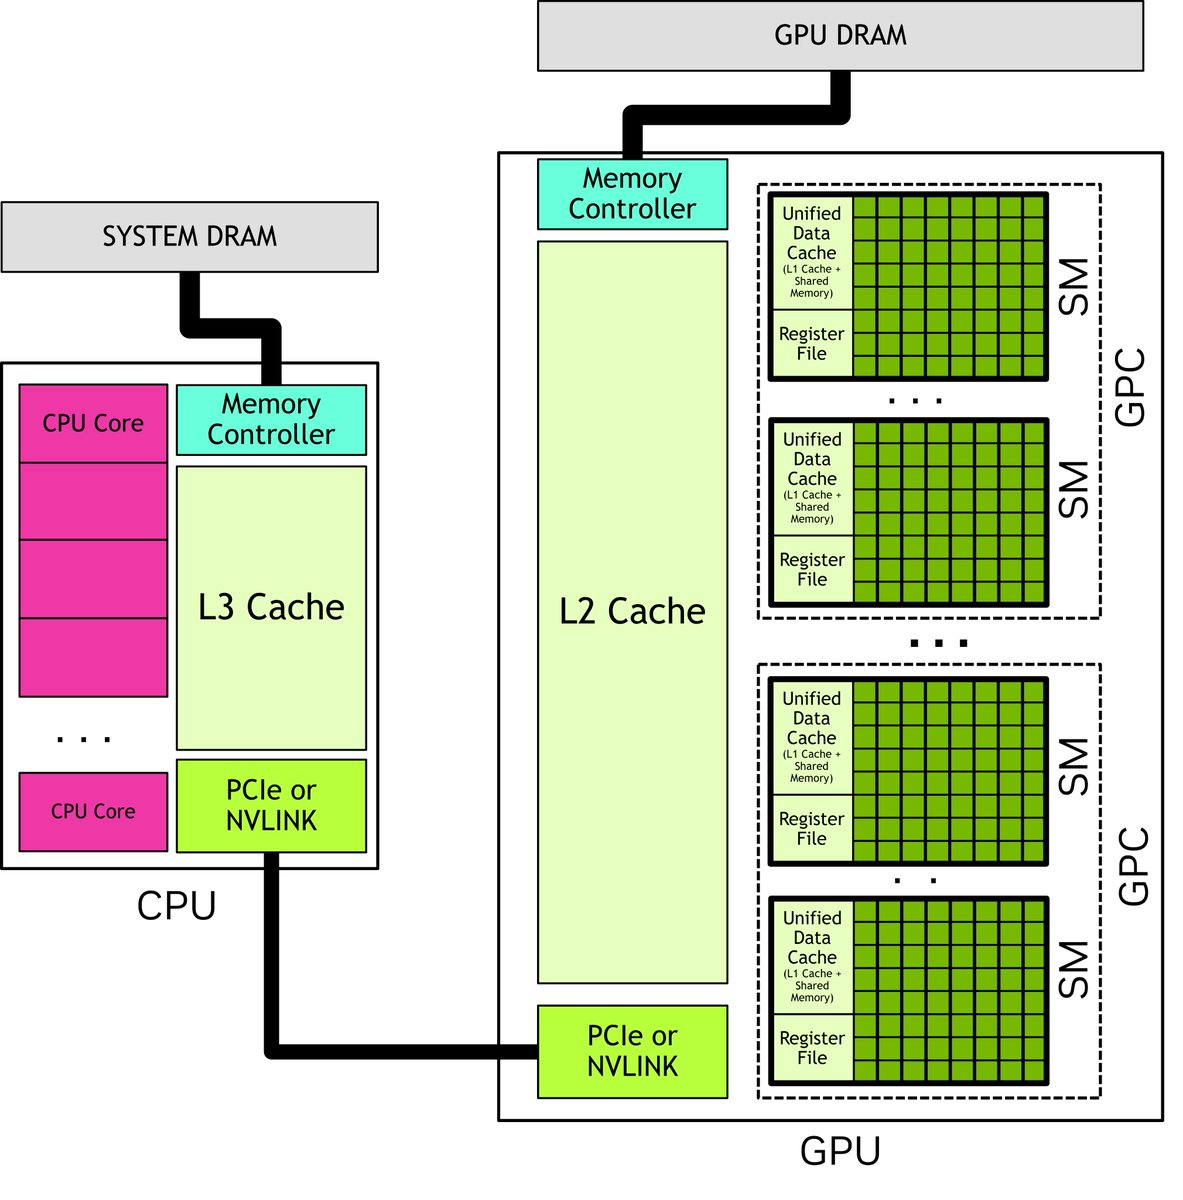
The same accounting runs through the rest of the advice. Memory capacity decides which configurations fit, and the three GPUs carry different amounts each, but the post keeps capacity and bandwidth separate: a long can fit in memory while reading its cached keys and values at every step still dominates latency. Precision can change both memory traffic and compute throughput, with FP8 on Hopper and native NVFP4 on B200 and B300, and the post says to count the scale metadata, confirm which kernels actually run, and test the model on the tasks it must perform. Splitting a model across more GPUs with tensor parallelism reduces each GPU's computation while making communication a larger share of latency.
The post's text offers a method, not measurements of its own on the newer GPUs. Chen checked her estimates against FasterTransformer measurements, and wafer_ai asks readers to do the equivalent: compare predictions with measured kernel durations and achieved memory bandwidth, and record time to first token, inter-token latency and output-token throughput on the same model and a representative workload.
- transformer — The neural network architecture behind modern AI models, built on attention — letting every word directly consider every other word in parallel.
- KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
Checking sign-in…
Loading comments…