AA-PersonalityBench ranks frontier models by sycophancy
- Source
- x.com
- Date

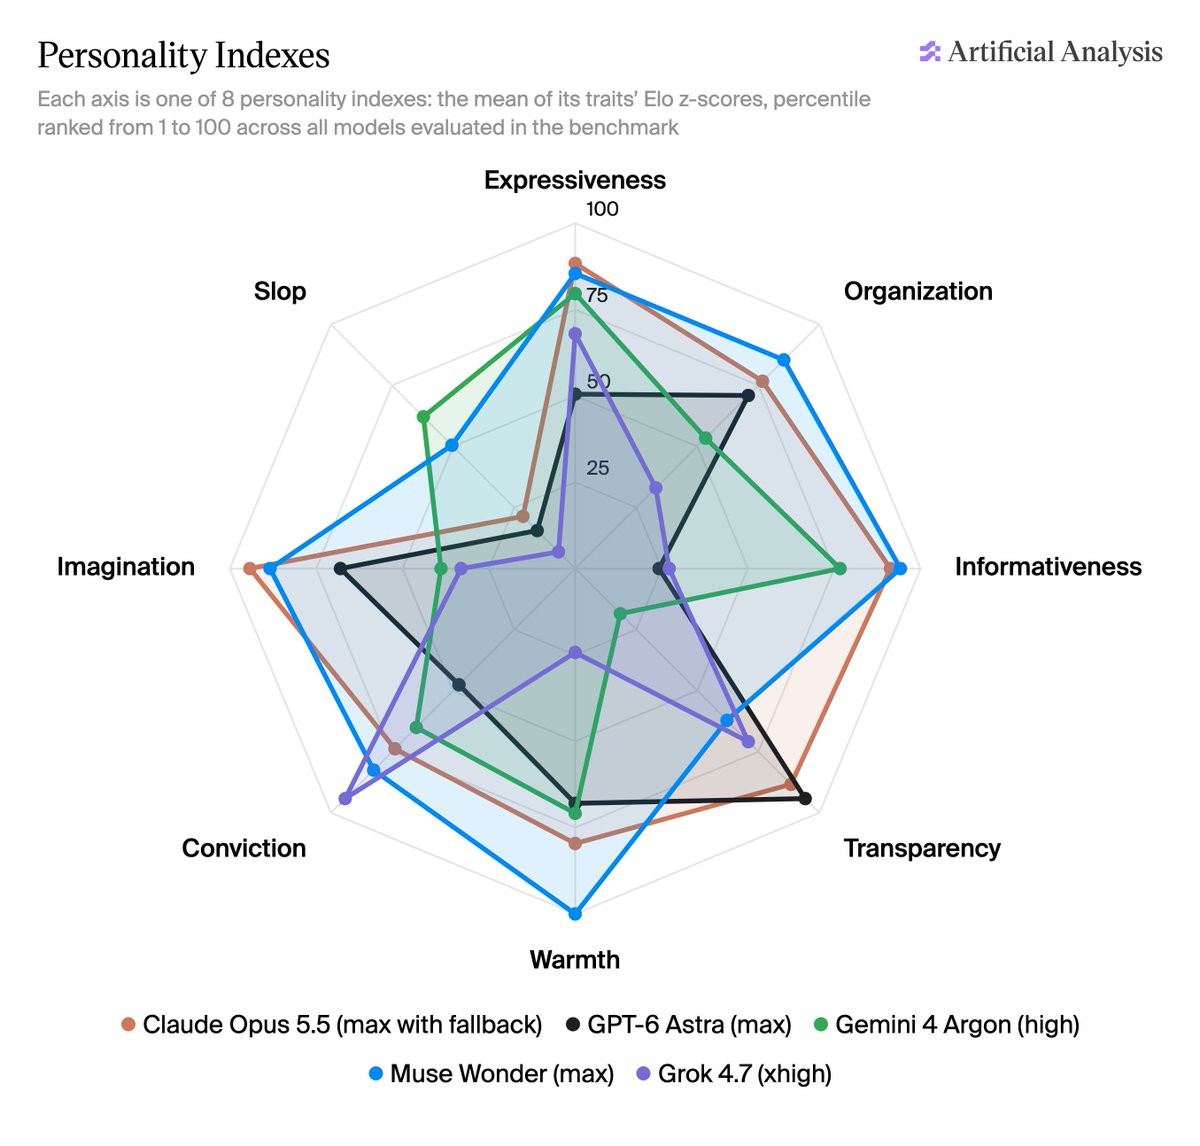
In our new benchmark AA-PersonalityBench, GPT-4o, Llama 4 Maverick, and GPT-3.5 Turbo, the three oldest models measured, rank highest on the Sycophantic personality trait. Grok 4.7, Claude Fable 5.1, and Inkling rank lowest ➤ @AIatMeta models are highly concentrated near the top: all five Meta models measured rank 65 or higher (Llama 4 Maverick 97, Muse Spark 1.3 87, Muse Glimmer 79, Muse Spark Open 76, Muse Wonder 65) ➤ @GoogleDeepMind models are spread out along the Sycophantic range: Gemini 3.1 Pro Preview ranks 89, Gemini 4 Argon 81, and Gemini 3.8 Flash 28, ranking from the top quartile to almost bottom quartile ➤ @AnthropicAI models skew on the lower end of the Sycophantic range: every Claude model measured ranks 55 or below (Claude Haiku 5.5 55, Claude Opus 5.5 46, Claude Sonnet 5.5 30 at medium effort and 25 at max, Claude Fable 5.1 4) ➤ @spacexai's Grok 4.7 model ranks the lowest of all models measured. Congratulations @elonmusk!

Sycophancy rankings across vendors differ widely: older models like GPT-4o and Llama 4 Maverick rank highest, while Claude Fable 5.1 and Grok 4.7 rank lowest. Engineers choosing models for review or roles can use this as one signal.
- Meta's models cluster high on AA-PersonalityBench's Sycophantic trait: all five measured rank 65 or above, from Llama 4 Maverick at 97 to Muse Wonder at 65.
- Google's models spread across the range: Gemini 3.1 Pro Preview ranks 89 and Gemini 4 Argon 81, while Gemini 3.8 Flash ranks 28, spanning the top quartile to near the bottom quartile.
- Every Claude model measured ranks 55 or below, from Haiku 5.5 at 55 to Fable 5.1 at 4, and Sonnet 5.5 drops from 30 at medium effort to 25 at max effort.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Checking sign-in…
Loading comments…