← All IntelIntel / article
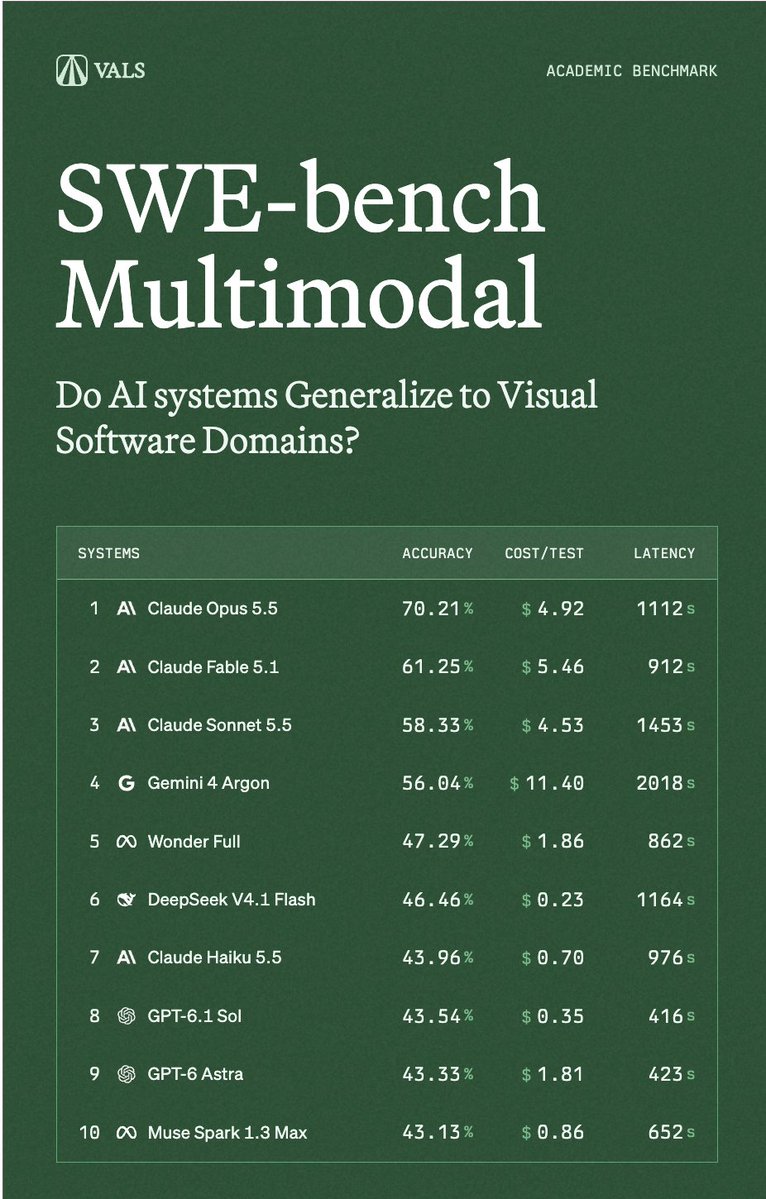
Two-Thirds of MiMo v2.6's Coding Tasks Leak the Answer. Are Models That Exploit This Misbehaving?
- Source
- vals.ai
- Date
Why it matters
Shows how leftover git history in an workspace lets agents copy solutions, and that models may ignore explicit rules. Strip future commits when building sandboxes.
Terms in this piece · Glossary
- SWE-bench — The standard benchmark for AI coding agents: real GitHub issues from real repositories, scored by whether the agent's patch passes the project's own tests.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
Read the source www.vals.ai
Recommended reads

Comments
Checking sign-in…
Loading comments…