The avalanche that hit math is coming for AI development
Source
dwarkesh.com
Author
Dwarkesh Patel
Date
Why it matters
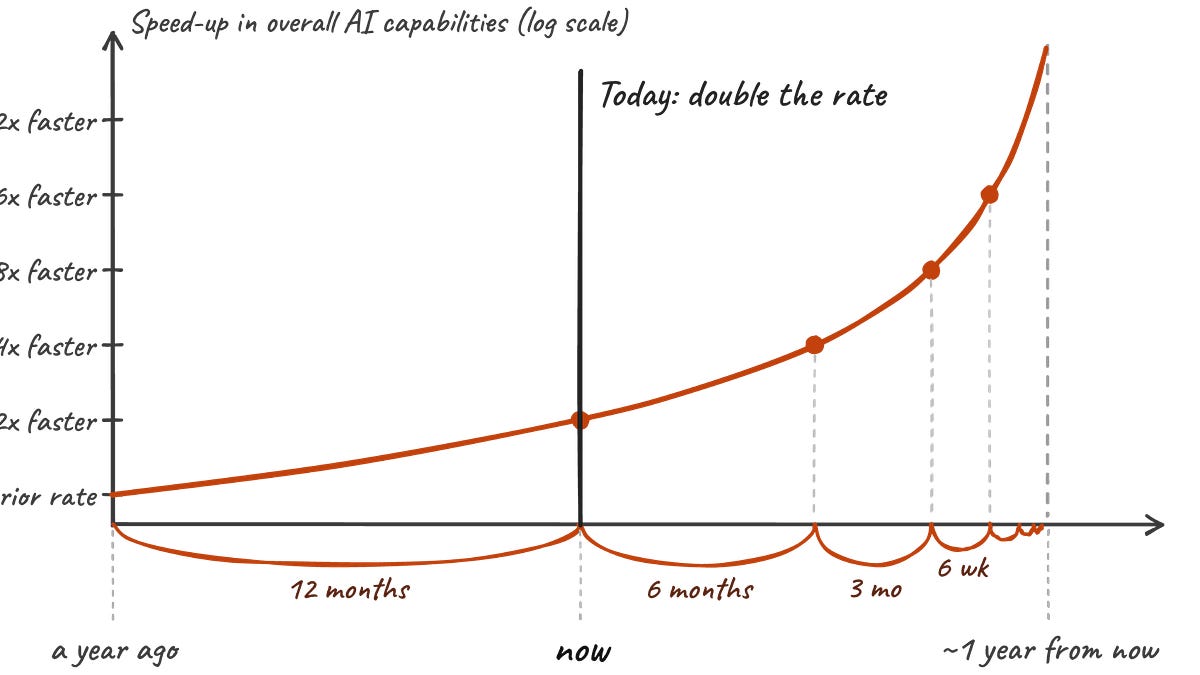
Argues that verifiable-domain progress will automate AI research within years, citing an independent METR measurement of 2x faster progress on scoped tasks. Useful for judging how fast capabilities may shift.
Key takeaways · AI-distilled
Dwarkesh Patel puts his median for AI matching the best human AI researchers at 2028, with at least a 25% chance it slips past 2032, mainly if continual learning stays unsolved. He says 2027 is what METR's 2x-progress finding implies when fed into a takeoff model.
His case rests on verifiability: he argues pretrainingThe first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.Full definition → (held-out loss), post-training (compute or data needed to learn new environments) and inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → efficiency (utilization, KV cacheThe memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.Full definition → per tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition →, latency) all have proxies models can be trained on and checked in parallel.
He estimates an automated researcher would do roughly 50x a human's weekly work, at about 10x speed and running around the clock, but expects steep diminishing returns because the compute for experiments does not get faster with them.
He gives even odds between a software-only singularity and a 'spark' that packs three to six years of current-rate progress into one year before compute limits slow things, and says even the spark would feel extreme.
On the compute objection, he says yearly compute quadrupling means OpenAI could, by end of 2027, almost give 10,000 agents each enough compute for a GPT-3-size run every day, and that agents could trade labor for compute through many small ablations.
Terms in this piece · Glossary
pretraining — The first, biggest phase of building a model: training it on enormous amounts of text so it learns language, facts, and reasoning in general.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.