Running Kimi K3 on my desk?
- Source
- x.com
- Date

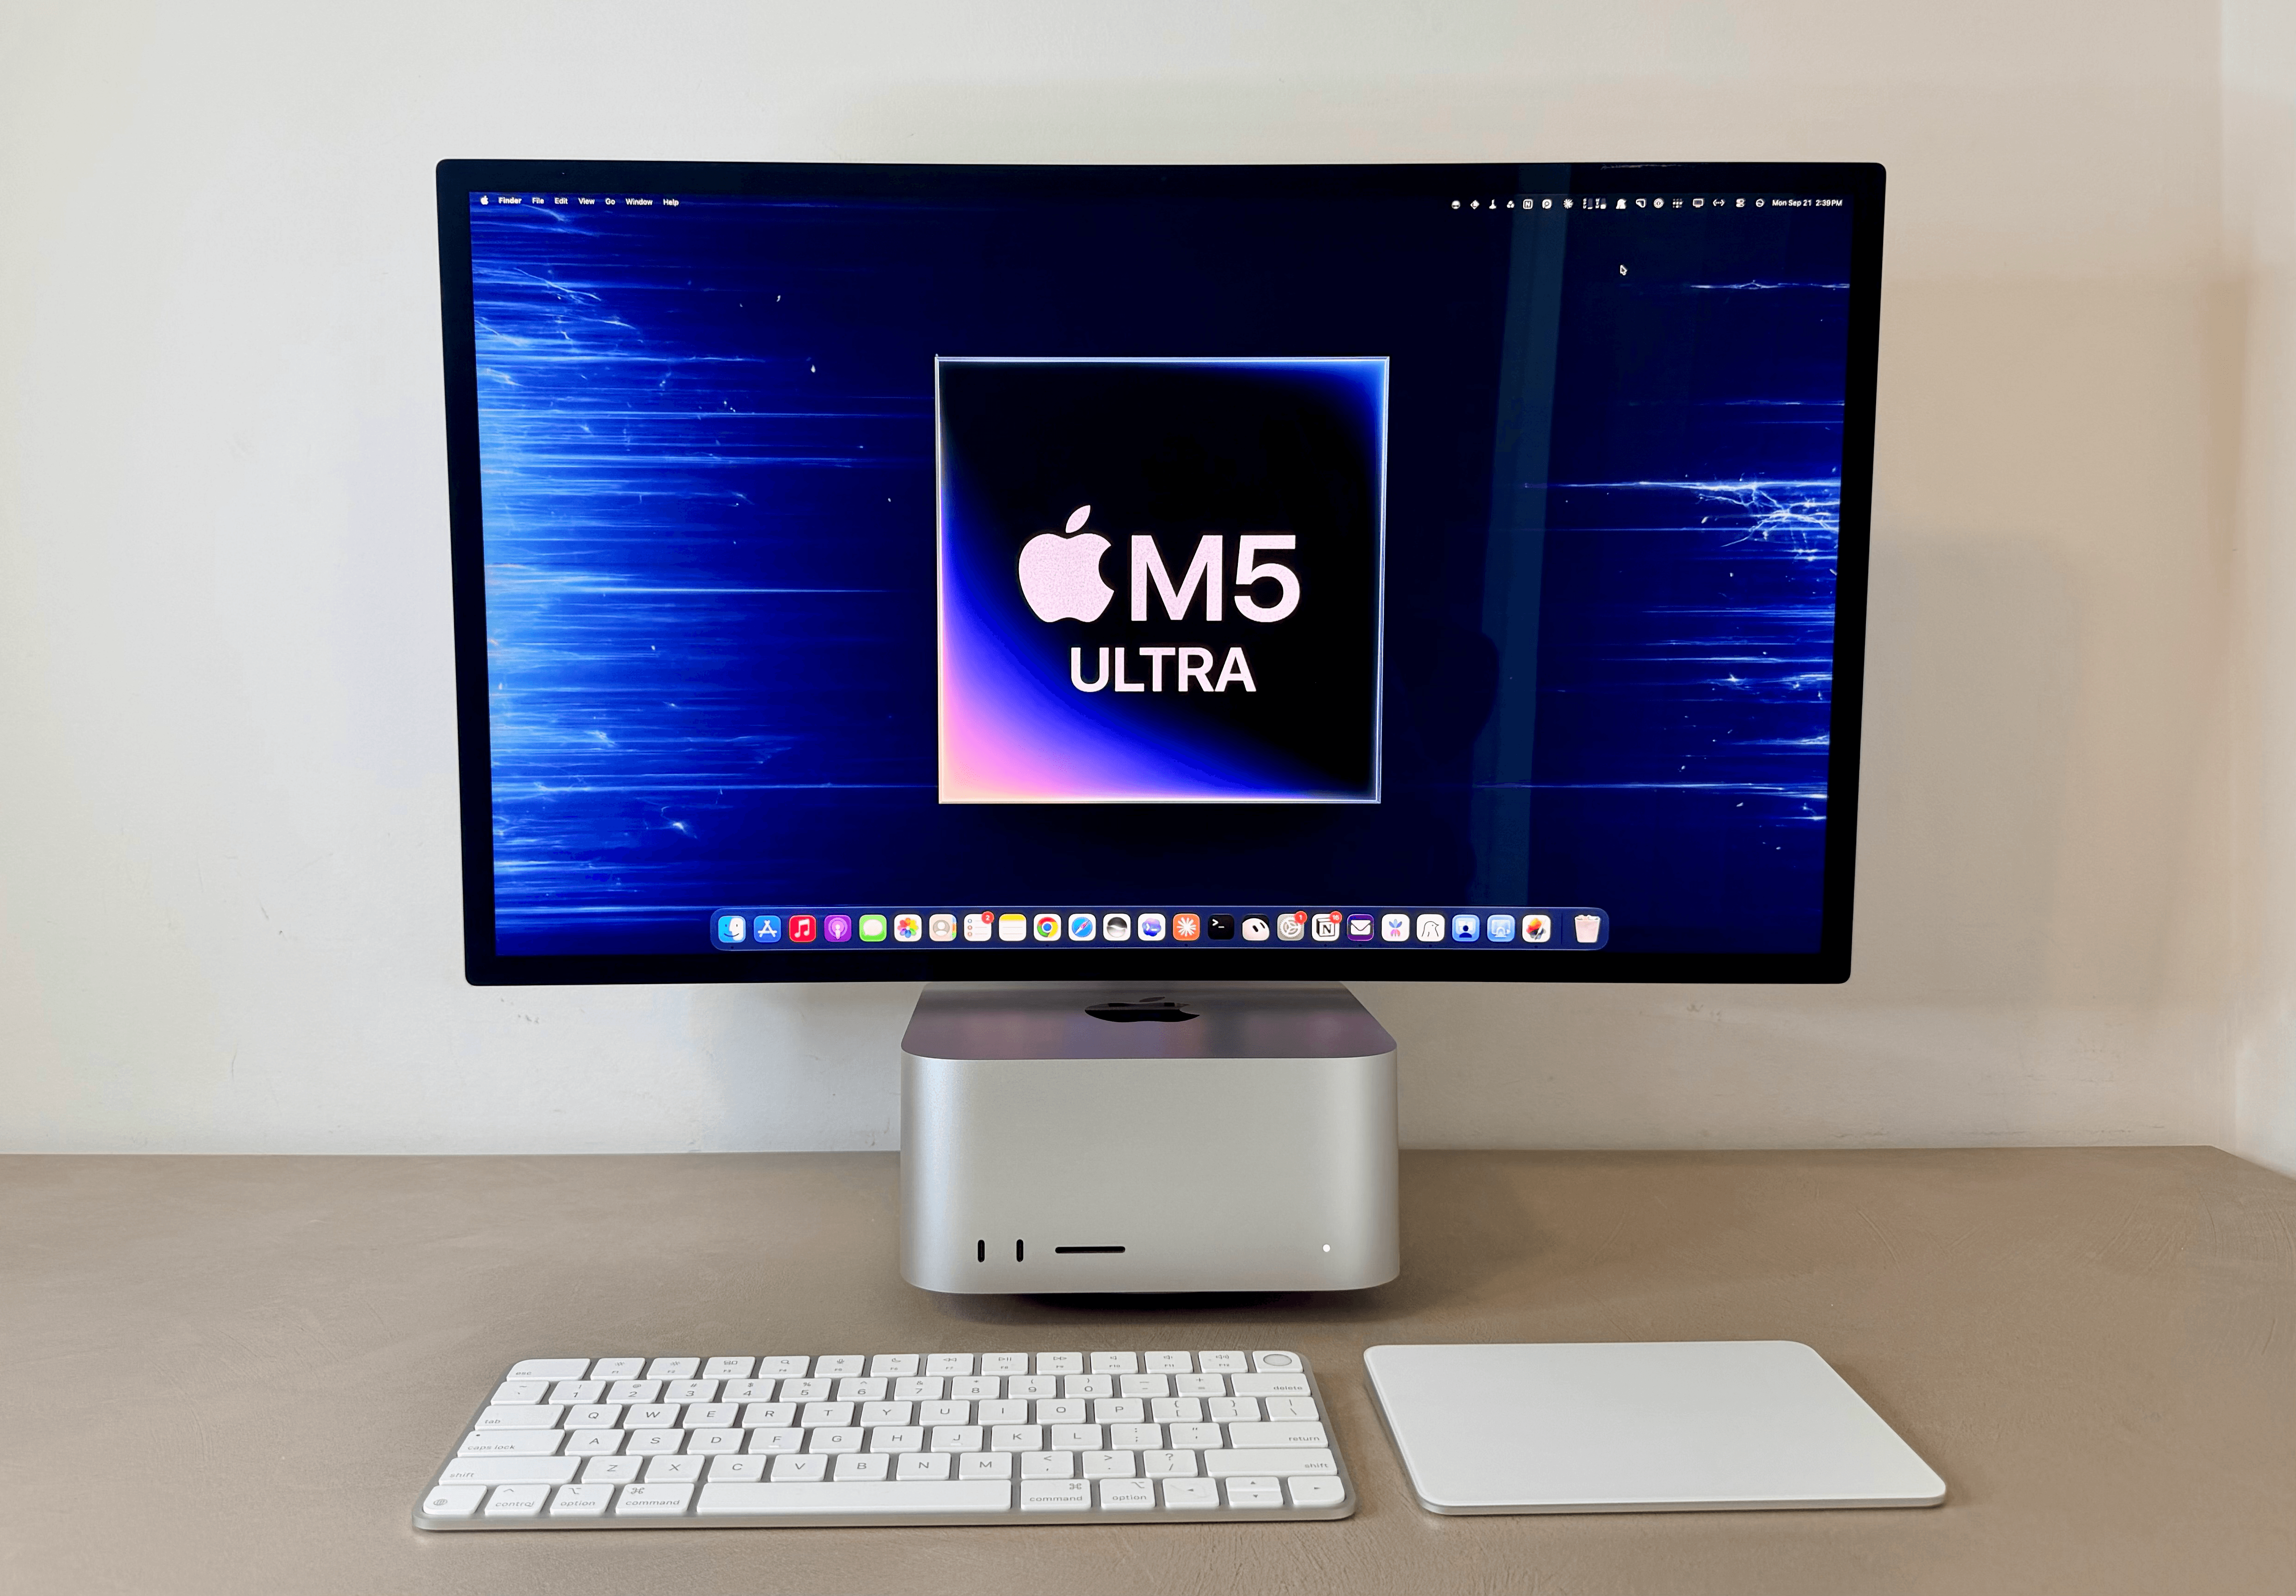
Running Kimi K3 on my desk? It will require 4 x 512GB M3 Ultra Mac Studios (2TB @ 3.2TB/s). Waiting on active parameter count, but based on the rumours I expect we can run it at 30+ tok/sec with MTP + Tensor Parallelism using RDMA over Thunderbolt 5. Prefill will be slow but 512GB M5 Ultra should make that ~5x faster (expecting in October). It will be on local dot ai with full benchmarks as soon as the weights drop. Comment below for early access - sending access codes out throughout the day.
Context
Alex Cheema's Kimi K3 desktop post is a hardware forecast made before he had the weights to test. He anticipated needing four 512 GB M3 Ultra Mac Studios and estimated generation above 30 per second, while explicitly saying he was still waiting for the active parameter count.
The attached earlier account concerns Kimi K2.5 running on two machines. It supplies for his interest in local deployment, but the larger configuration and K3 speed remain predictions. The K3 post is a proposal for a future , rather than evidence that the proposed K3 system worked.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.
- postIs the Rush to Build New LLM Inference Engines Fragmenting the Ecosystem?
- postBig model. 2.4T params, 95B active. 4.89TB. Surprised they didn't release a 4-bi
 post@Jason @Lons @eisokant @ape Correction: Should actually be closer to 50 tok/sec
 postApple markets a four-Mac cluster for trillion-parameter local inference
Checking sign-in…
Loading comments…