Fable 5.2 tops Artificial Analysis Index at a higher cost per task
- Source
- x.com
- Date

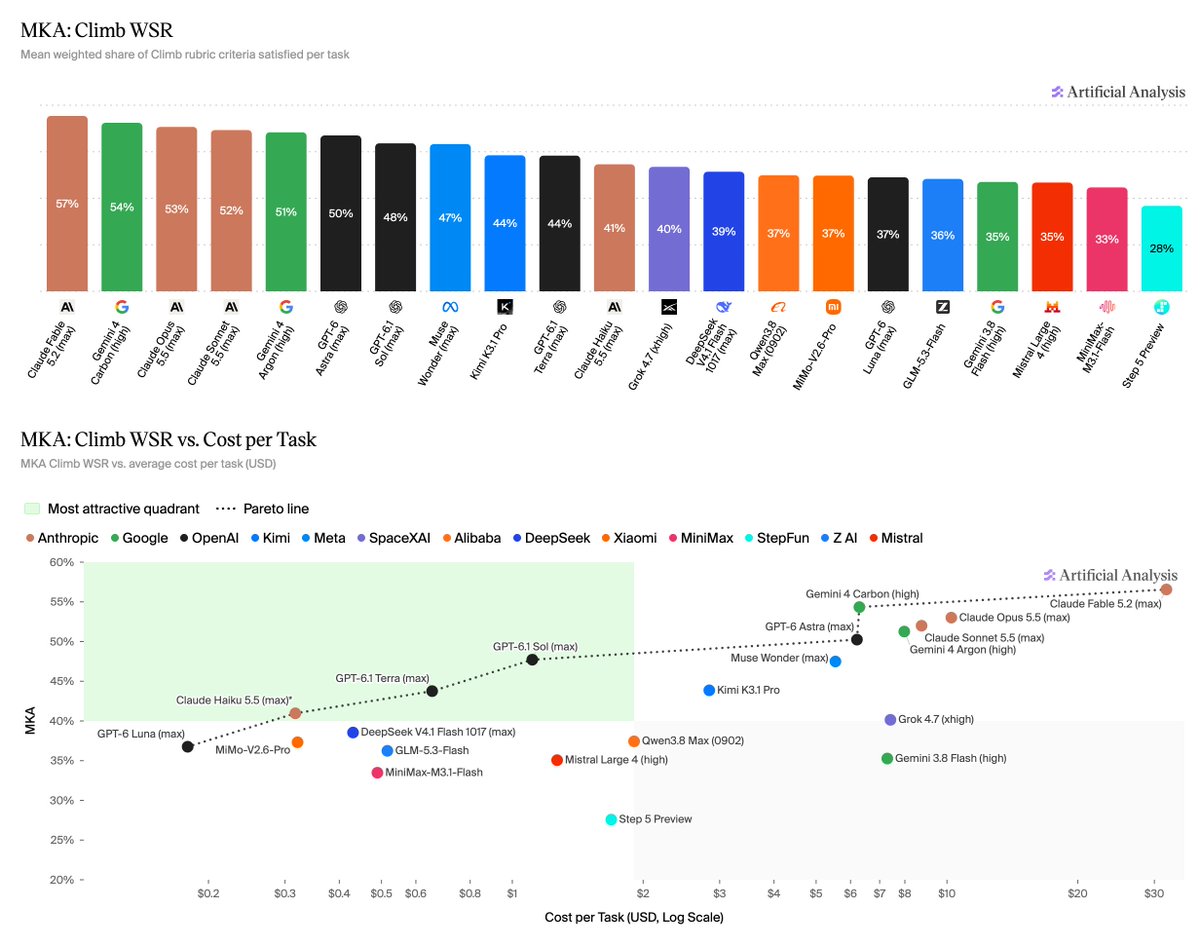
Anthropic has released Claude Fable 5.2, taking the #1 spot on the Artificial Analysis Intelligence Index v5 at 65, led by gains in science, knowledge, and coding At max effort it scores 65, 5 points ahead of Gemini 4 Carbon (high, 60) and 6 ahead of Claude Opus 5.5 (max, 59). Gains are driven by scientific reasoning, knowledge and FrontierCode 2.0, and roughly matching Opus 5.5 on AA-Briefcase and Terminal-Bench 4.0. Priced at $8/$40 per 1M input/output tokens, a 20% reduction from Fable 5.1, Claude Fable 5.2 averages a Cost per Task of $26.5 with max effort, a ~2.6x increase compared to Opus 5.5 (max, $10.0) and ~2x compared to Fable 5.1 (max, $12.99) Key takeaways: ➤ Claude Fable 5.2 leads 5 of the 9 evaluations in the Intelligence Index: At max effort, Fable 5.2 scores 65, ahead of Gemini 4 Carbon (high, 60), Claude Opus 5.5 (max, 59) and GPT-6 Astra (max, 57), and ~15 points above Claude Fable 5.1 (max, 49). It sets the highest scores on HLE-Diamond (80%, previous best 69% from Gemini 4 Carbon), AA-Omniscience v1.1 (67, previous best 54 from Gemini 4 Carbon), Terminal-Bench-Science (73%, previous best 65% from Gemini 4 Carbon), CritPt v2 hard subset (77%, previous best…

Fable 5.2 leads at 65, but max effort costs about 2.6x more per task than Opus 5.5. At high effort it scores 62 using about 40% fewer output than Opus 5.5 (max), so effort setting drives cost and value.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…