NVIDIA Nemotron 3.5 Super VL Powers Specialized Agents with Multimodal Reasoning
Source
developer.nvidia.com
Author
Michelle Horton
Date
Why it matters
A new open multimodal agent model merges reasoning, tool use, and vision in one model, and ships with customization recipes and open datasets. Teams can fine-tune it instead of running separate vision and language models.
Key takeaways · AI-distilled
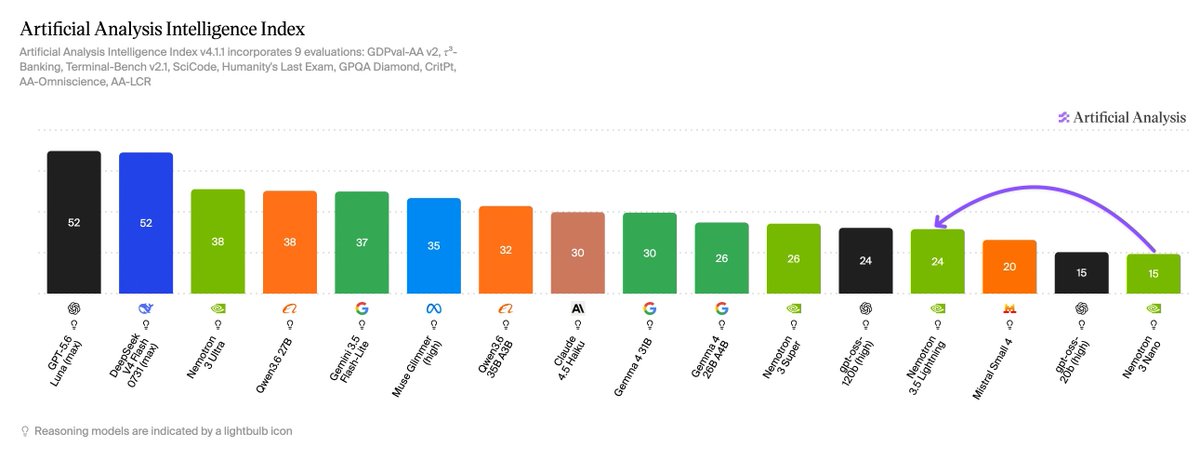
NVIDIA reports Super VL scores 63.44% on Hermes Bench and 87.05% on LangChain evals, ahead of Nemotron 3 Ultra (56.33% and 84.3%). On the CharXiv chart benchmark it scored 80.8%, or 84% with Python code interpretation.
LiLiCorr speculative decodingA speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.Full definition → scores token candidates jointly across a whole draft with a lightweight network. NVIDIA recommends it on DGX Spark and says it gives up to 2.3x faster generation than no speculation.
The NVFP4 checkpoint uses 4-bit weights and activations on Blackwell, and on other GPUs runs with 4-bit weights and 16-bit activations. quantizationShrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.Full definition →-aware distillation also lets the KV cacheThe memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.Full definition → sit in NVFP4 instead of FP8.
Super VL was distilled from Nemotron 3 Ultra, then refined with multi-teacher on-policy distillation in which specialized text and vision teachers score the model's own responses.
Partner figures are projections or reports: Scale AI expects 40x lower inference cost and 5x lower latency for Skydance, Ramp expects up to 50% higher throughput, and AI21 and Alice report a 41% accuracy gain.
Terms in this piece · Glossary
mixture-of-experts — A model built from many specialist sub-networks where only a few activate per token, giving big-model capability at small-model running cost.
speculative decoding — A speed trick where a small model drafts several tokens ahead and the big model verifies them in one pass, often doubling generation speed.
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.
KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.