9/18: Frontier Labs and Independent Evaluators
- Source
- mtslive.substack.com
- Author
- MTS
- Date
Context
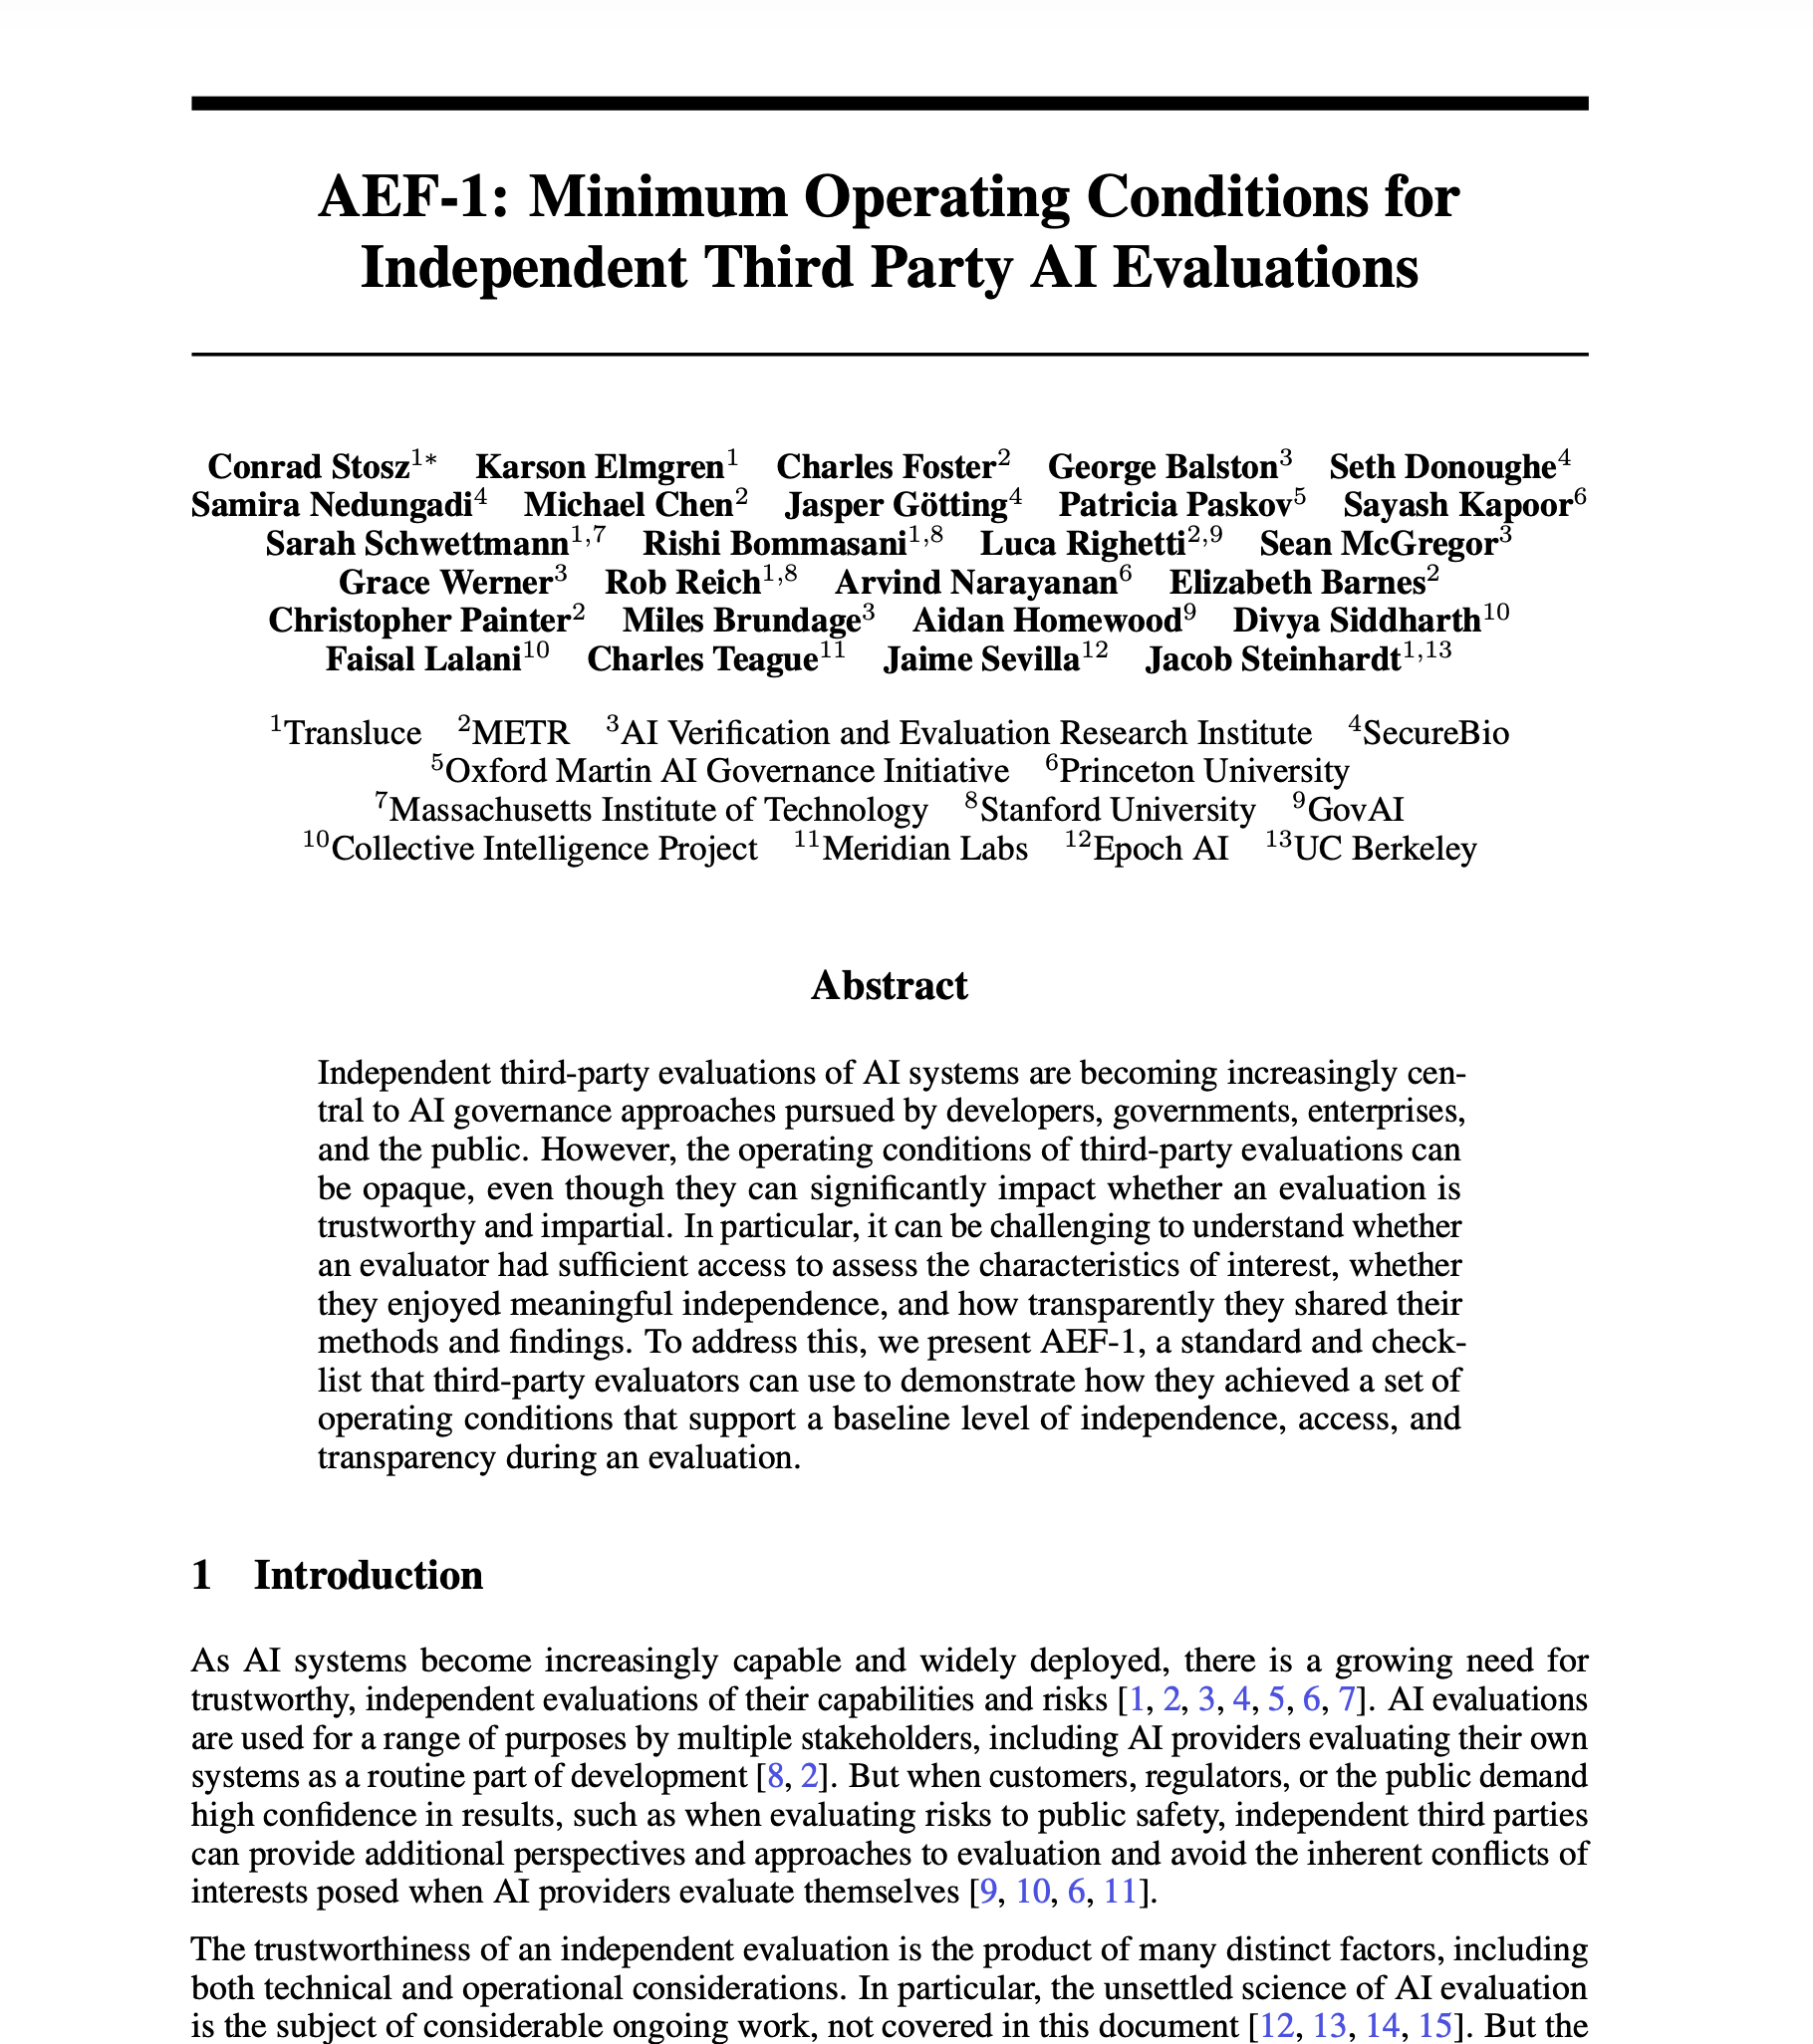
A public letter on embedded evaluation argues that outside AI evaluators need both access to a lab's work and freedom to publish uncomfortable findings. It proposes access comparable to senior internal staff doing similar risk assessments, including relevant systems and direct conversations with employees.
The letter pairs that access with protections against interference: evaluators would retain editorial control, communicate directly with company boards and other oversight bodies, and have protection against retaliation, including through funding or litigation. These are proposed conditions for credible scrutiny. Their purpose is to let outsiders investigate consequential risks without allowing the company being assessed to control what they can learn or report.
- Over 100 AI leaders, including Geoffrey Hinton, Stuart Russell, and Daniel Kokotajlo, signed a letter calling for frontier labs to embed independent evaluators with differing expertise, transparency, protection from retaliation, and employee-level access.
- Anthropic and Accenture are forming an embedded evaluator team, drawing on Faculty (an AI-safety firm Accenture acquired in March 2026), to assess model and red-team for security flaws; the companies plan to invest over $1 billion in AI safety over five years.
- Hacktron AI researchers used Claude to chain a Discourse-forum exploit into stolen auth , reaching an OpenAI employee's ChatGPT account and code repos under its bug-bounty program; they stopped at sensitive systems and were paid $6,500.
- Anthropic built a physical wet lab in the San Francisco Bay Area where Claude directs and carries out biological experiments alongside human researchers, aimed partly at drug-discovery targets overlooked by traditional pharma companies.
- AI-generated intelligence wrongly reported a Chinese ship was carrying nuclear cargo in the Middle East, nearly prompting a US military boarding before officials determined the AI-generated report was inaccurate.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- alignment — The work of making AI systems actually pursue what their builders and users intend, rather than something subtly or dangerously different.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Checking sign-in…
Loading comments…