FinProBench: Evaluating Financial AI Agents with Role-Grounded Rubrics Derived from Professional Deliverables
Source
arxiv.org
Author
Ben Wang, Kang Zhou, Lifan Guo, Feng Chen, Chi Zhang
Date
Why it matters
A practical boundary for LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition →-judge design: prompt-written rubrics suffice where the task convention is well represented in model priors, and fail exactly where your domain is unusual — which is where evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → matters most.
Terms in this piece · Glossary
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.
grounding — Tying a model's answers to checkable sources — retrieved documents, live data, tool results — instead of letting it answer from memory alone.
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
 articleInducing Reward-Free Judging Rubrics that Reduce Over-Crediting in Agent EvaluationDarragh Quinn, David Dylan, Roisin Healy, Fionn Carroll, Maeve Donnelly, Cormac Sheehan
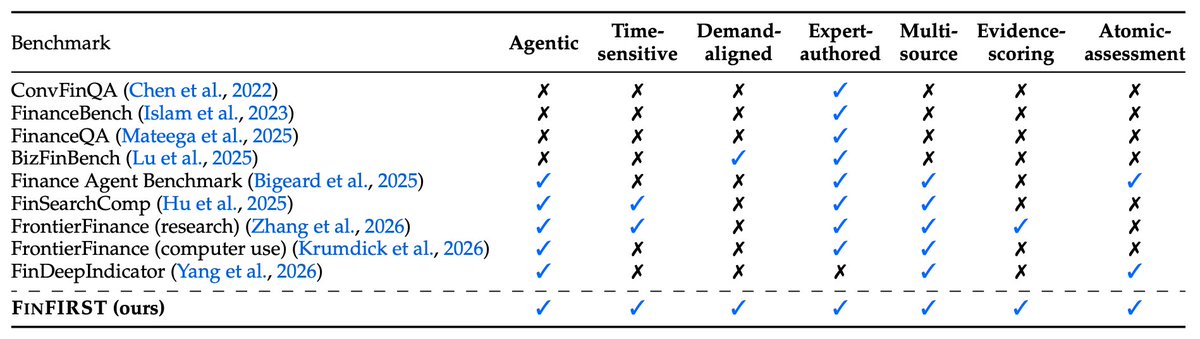 postSince its release, FinFIRST has drawn a lot of interest.Ant Ling
 articleLlm As A Judge Evaluate Ai AgentsOpenRouter editorial sitemap