← All IntelIntel / article
Qwen 3.8 27B on my laptop can interpret model weights, too
- Source
- simonwillison.net
- Date
Why it matters
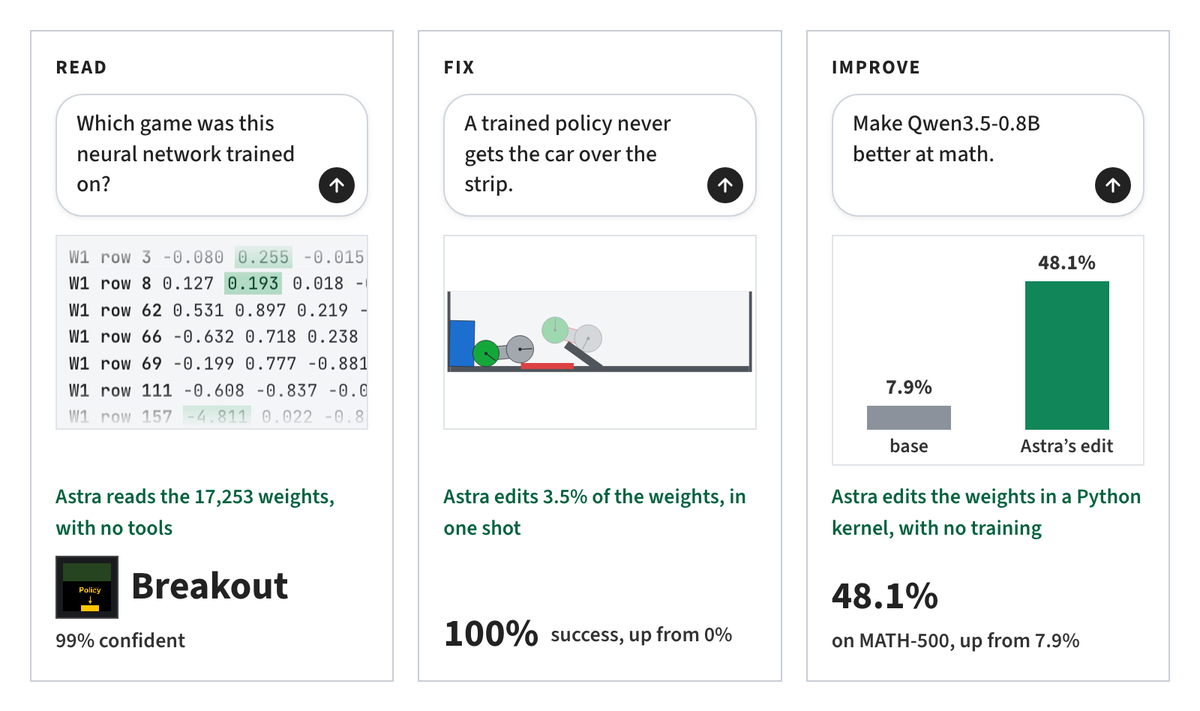
Shows that interpreting raw model weights as text, claimed for a frontier model in a new paper, also works with a 27B model on a laptop. Gives you a runnable way to test the claim yourself.
Key takeaways · AI-distilled
- The Weight-Space Programming paper reports GPT-6 Astra edited 0.016% of Qwen3.5-0.8B's weights without gradients, raising MATH-500 from 7.9% to 48.1%; Matthew Honnibal called the paper misleading for conflating no-tools weight reading with code-assisted editing.
- In the paper's no-tools test, a model sees only the floating-point weights of a policy network trained on a 10x10 grid version of Breakout, Pong, Pac-Man or Freeway, and must name the game in a single response.
- Willison ran the published prompts on Qwen 3.8 27B, a 17GB model, in LM Studio on his laptop. It identified Pac-Man, Pong and Breakout in runs of roughly 46 to 65 minutes, but mistook Freeway for a Pac-Man-like game.
- The local runs needed a long , since LM Studio's default 8,192 failed with errors, plus LMSTUDIO_TIMEOUT raised to 900; the Pac-Man answer took 43,506 reasoning tokens.
- Willison expects a sufficiently experienced human with a notepad and pencil could get there with enough effort, and says some wider commentary does not feel justified: he is not ready to declare the age of source code over.
Terms in this piece · Glossary
- context window — The maximum amount of text a model can consider at once — its working memory for the current conversation or task.
- token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
Read the source simonwillison.net
Recommended reads
Comments
Checking sign-in…
Loading comments…