A Fireside Chat with Cat and Thariq from the Claude Code team
- Source
- simonwillison.net
- Author
- Simon Willison
- Date
Context
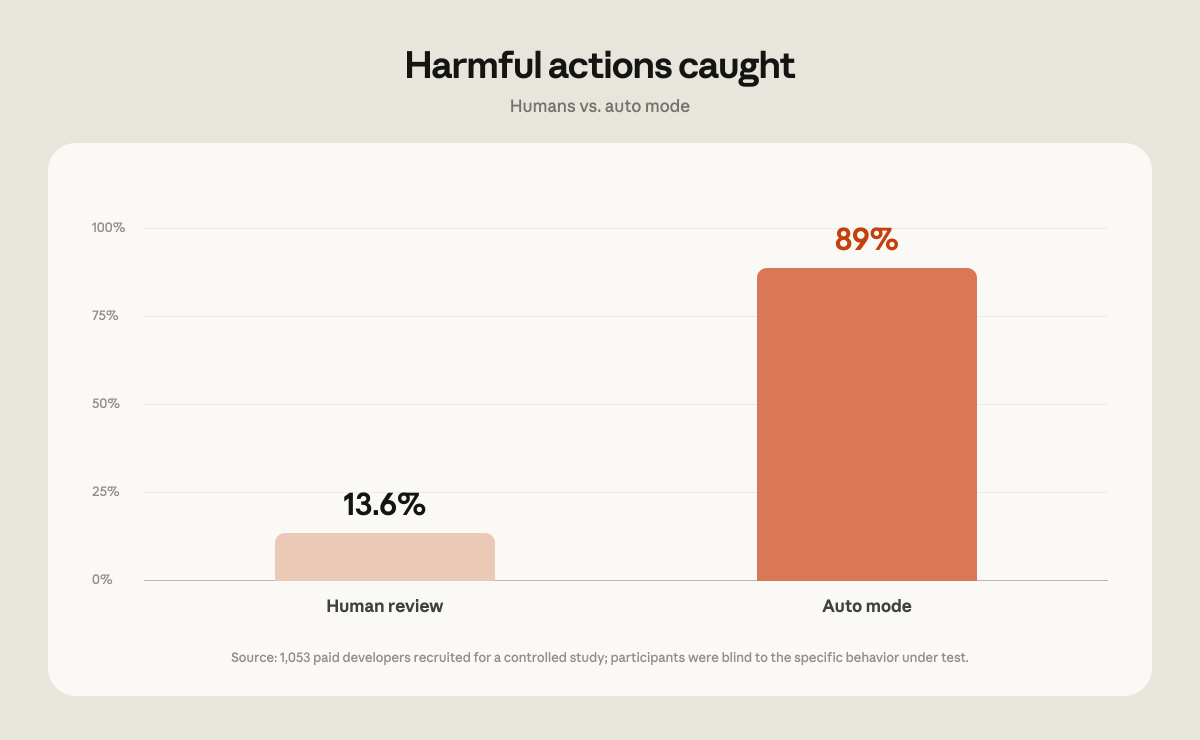
Anthropic's Claude Code team describes a gradual shift toward automated code review, with manual approval retained for critical areas. In this edited fireside-chat transcript, team members say a review bot examines every proposed change, while designated code owners must approve changes touching important components such as the .
They also describe turning failures into future checks: after an incident, the responsible changes become cases for the automated reviewer. This creates a feedback loop in which increasing automation depends on testing the review system against mistakes the team has actually encountered.
- Claude Tag is multiplayer and proactive by design. You add it to a Slack channel and give one standing instruction, like monitor every bug report, open a PR, and tag whoever last touched that code, and it keeps doing that for the life of the channel.
- Preferences live with the team, not one person's config. Tell Claude Tag in the channel that it should debug outages but ignore warnings, and it applies that for everyone on the team from then on.
- The team's split: Claude Code for the hardest tasks, where you want to iterate with the turn by turn. Claude Tag for work you want done on your behalf without kicking off a session at all.
- Thariq's case for rewrites: a codebase is a spec, and often the only complete copy of it, since nobody knows every branch. That makes it an artifact you can distill into a new version. Anthropic rewrote Bun in Rust and now ships on it.
- The engineering mix shifts as idea-to-shipped collapses from six or twelve months down to about a week. Product taste and business judgment rise in value, execution falls, except in infra where the details still decide everything.
- system prompt — The standing instructions a model receives before any user input — defining its role, rules, tools, and tone for the whole conversation.
- eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
- AI agent — An AI system that doesn't just answer once but works toward a goal in a loop — taking actions, reading the results, and deciding what to do next.
- agent skill — A reusable instruction file that teaches an agent how to do one job well — the procedure, the tools, and what counts as done.
“Claude Tag currently lands 65% of our product eng PRs.”
Cat Wu
“For me, it's that rewrites are now good.”
Thariq Shihipar
“In general, we are trying to move to a world where humans don't need to be in the loop.”
Cat Wu
“The way you offset that is by being more ambitious.”
Thariq Shihipar


Checking sign-in…
Loading comments…