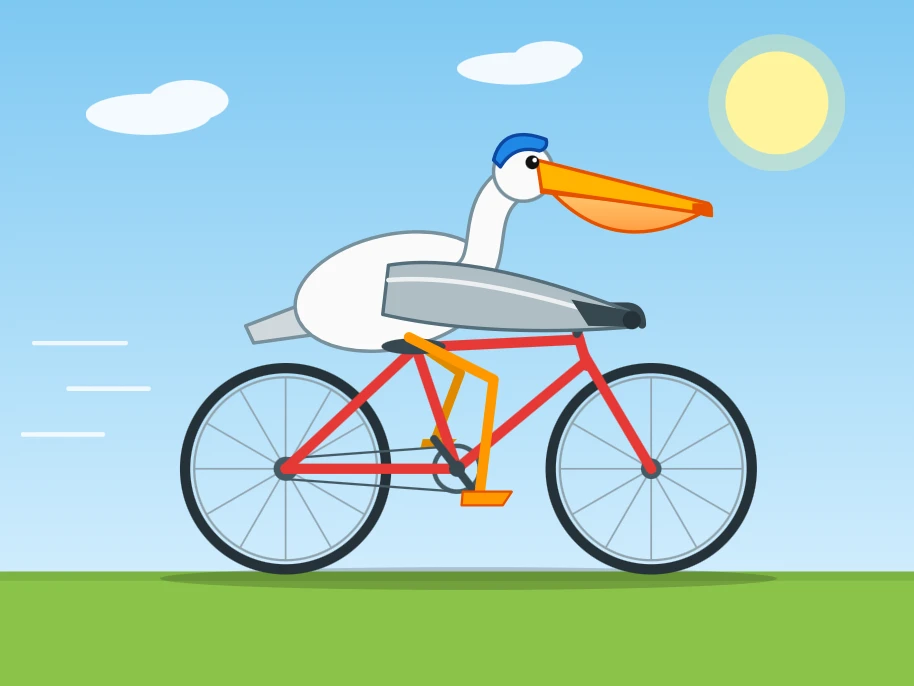
A higher reasoning setting can spend more without delivering an answer. In his Sonnet 5.5 test, Simon Willison reports that Anthropic's model used 128,000 reasoning tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → at Max effort, costing $1.28, then exhausted its budget without producing the requested SVG image code. At Xhigh, it returned an image for 5.74 cents in 41 seconds. This single drawing task illustrates why completion belongs alongside spending in an effort-setting comparison; it does not establish which setting performs best across other tasks.
Key takeaways · AI-distilled
Anthropic says Sonnet 5.5 runs 30%+ faster and costs up to 30% less for most work. Willison notes it keeps Sonnet 5's price while appearing to beat it on every benchmarkA standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.Full definition →.
In Willison's pelican test, max thinking effort used 128,000 tokens ($1.28) and ran out before producing an SVG, the same bug he saw with Opus 5.5. The xhigh setting finished in 41 seconds for about 5.74 cents.
Sonnet 5.5 is now the model behind the claude.ai free tier. Willison points out ChatGPT's free tier uses Luna 5.6 and argues that gives Anthropic the much more capable free offering for now.
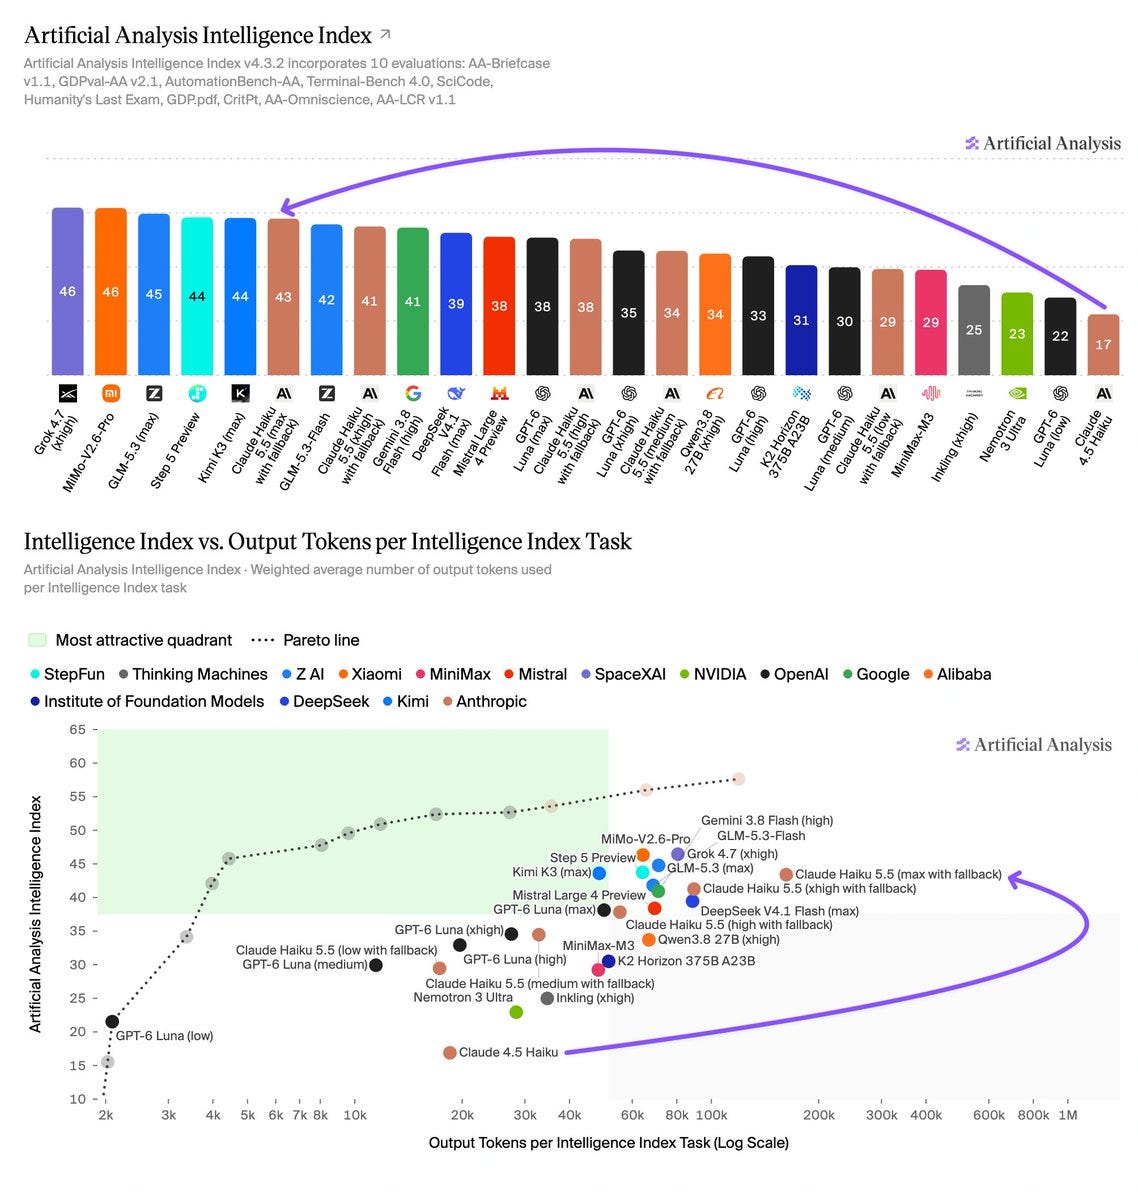
Anthropic's announcement repeats that Haiku 5.5 is coming "in the coming weeks". Willison says he hopes it will be price-competitive with GPT-6 Luna.
Terms in this piece · Glossary
token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
benchmark — A standard public test set for comparing AI models — the shared scoreboards behind every "model X beats model Y" claim.