Why AI evals are the hottest new skill for product builders | Hamel Husain & Shreya Shankar
Source
youtube.com
Author
Lenny's Podcast
Date
Why it matters
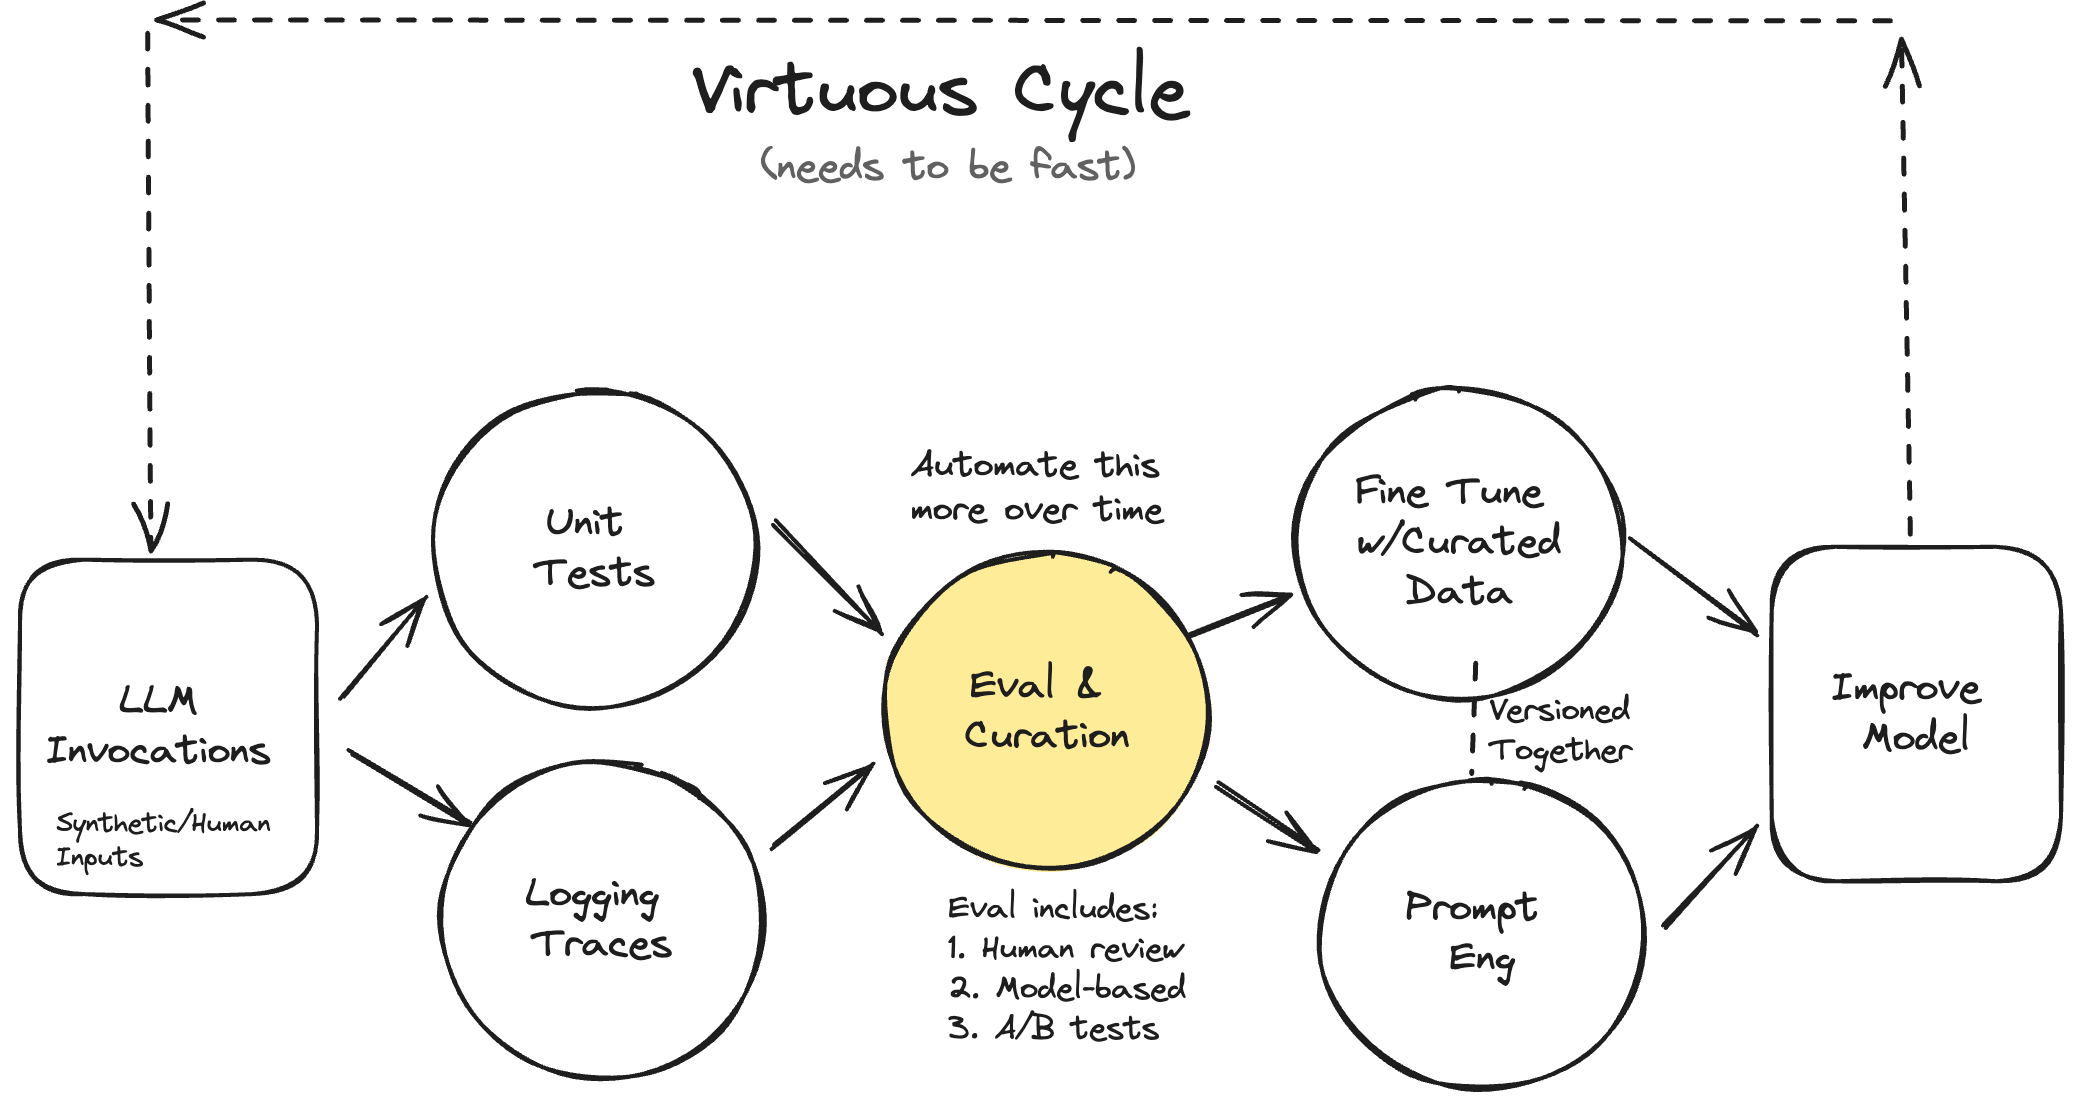
Gives a practical evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition → process: have one domain expert review traces, build failure categories once, and iterate, rather than relying on an LLMA large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.Full definition → to judge itself.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.
LLM — A large language model — the neural network behind tools like Claude and ChatGPT, trained on huge amounts of text to predict what comes next.