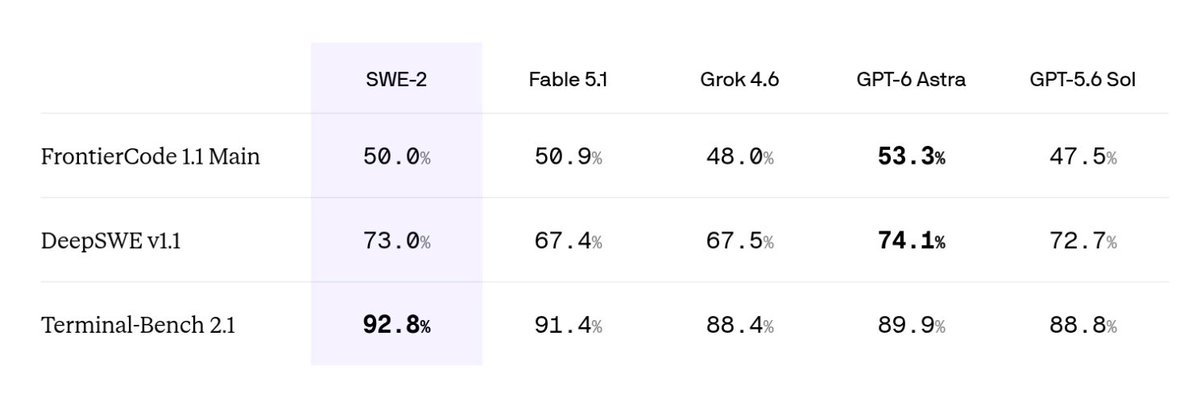
Cognition launches new SWE-2 model, Rivaling Fable 5.1 and GPT-Astra
Source
cognition.com
Author
seelos
Date
Context
Cognition trained SWE-2 to balance successful coding work against the cost of doing it. Its technical announcement describes rewarding successful attempts while penalizing a combination of computation cost and elapsed time, with different penalties for different reasoning-effort settings.
In the company's FrontierCode 1.1 Main evalA repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.Full definition →, the medium setting scored above SWE-1.7 while using 58% fewer turns and costing 81% less on average. Cognition attributes much of that difference to more focused exploration before editing. The result supports a specific efficiency improvement on its tested tasks, rather than a blanket claim that SWE-2 is better for every coding job.
Terms in this piece · Glossary
eval — A repeatable test for AI quality — a set of tasks plus scoring — used the way software teams use test suites, because model output is too variable to judge by eyeballing.