token — The chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.
test-time compute — Spending more computation when the model answers — thinking longer, trying multiple attempts — to buy accuracy without training a bigger model.
inference — Running a trained model to get answers — the phase where AI is actually used, as opposed to trained.
token budget — A cap on how many tokens a task, session, or agent run may consume — the practical control on both cost and how long an agent will grind.
Why it matters
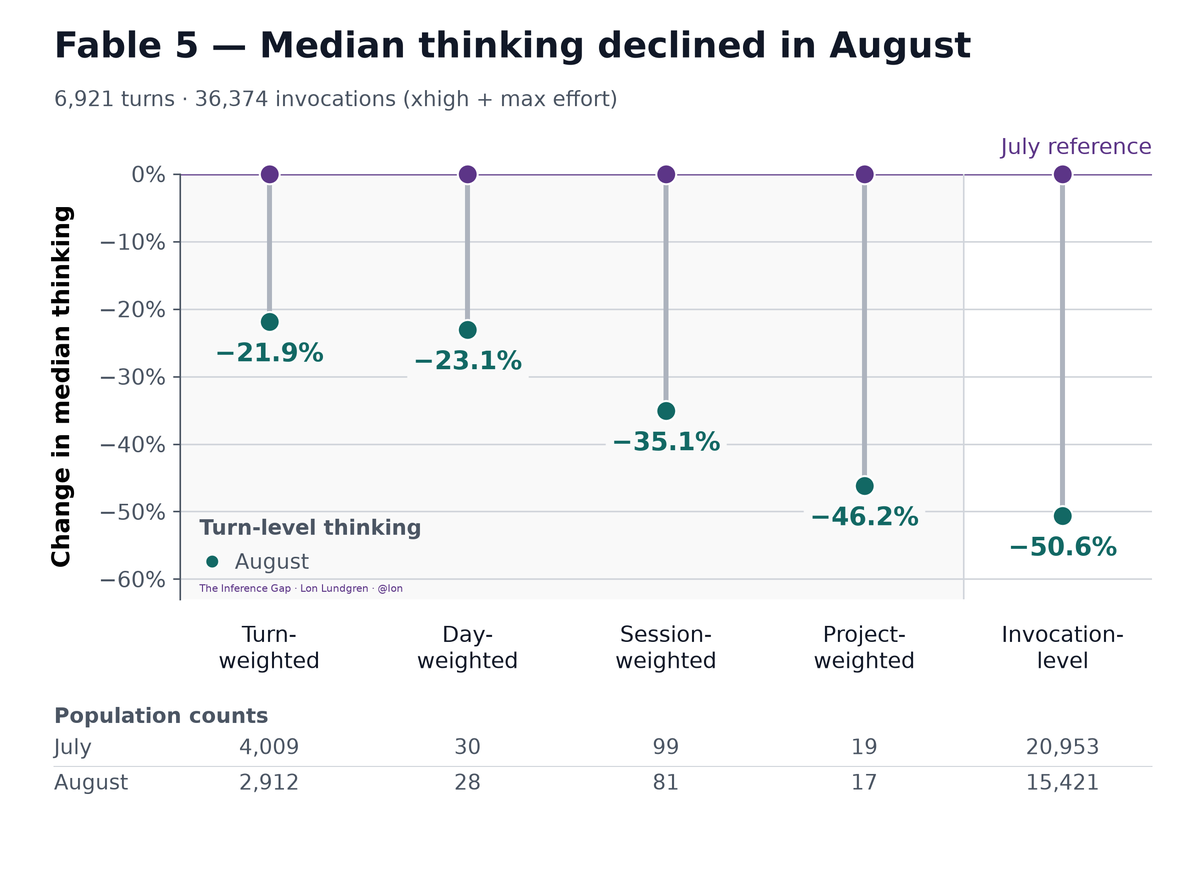
Shows perceived model quality can swing sharply due to the inferenceRunning a trained model to get answers — the phase where AI is actually used, as opposed to trained.Full definition → regime actually served (thinking-token budgetA cap on how many tokens a task, session, or agent run may consume — the practical control on both cost and how long an agent will grind.Full definition →), not the model itself, so practitioners should measure reasoning-tokenThe chunk of text a model reads and writes in — roughly three-quarters of a word — and the unit AI usage is billed in.Full definition → usage instead of assuming a 'nerf'.