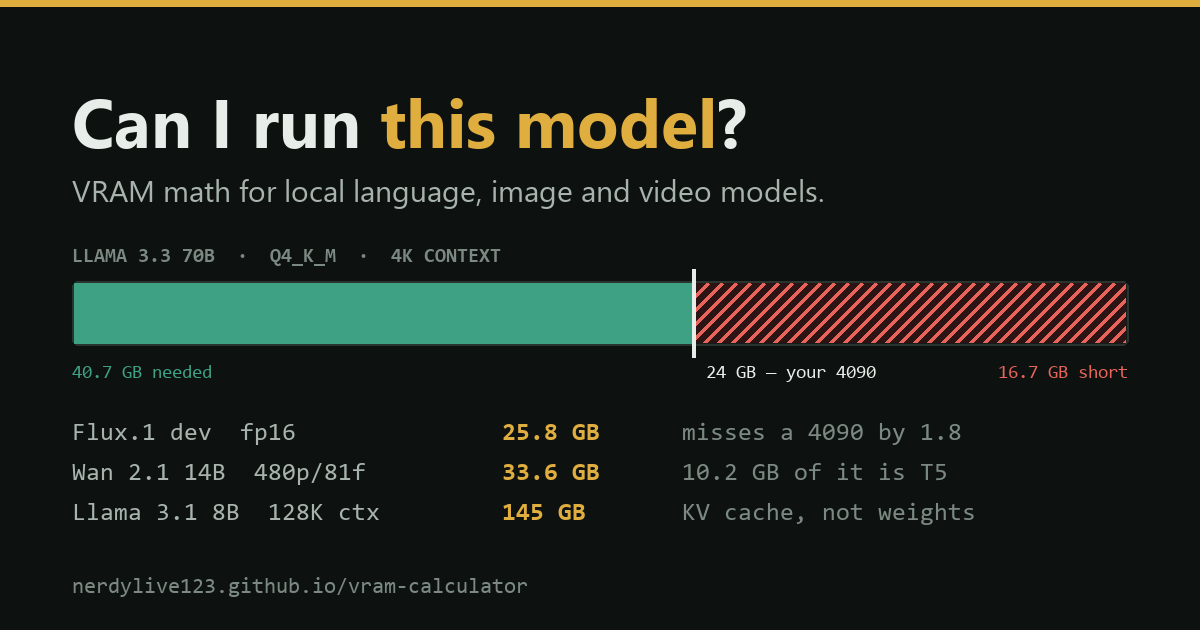
Can I Run This Model? explains why a Large language modelA model trained on large amounts of data to process and generate language.Full definition →'s stored weights are only part of its GPU-memory requirement. Its calculator adds memory for the attentionThe mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.Full definition → cache, which retains information used while processing a sequence, and runtime overhead.
In the displayed formula, cache memory grows with Context and context windowContext is the information available for a generation; the context window is the capacity available to hold it.Full definition → and the number of simultaneous sequences. A configuration that fits a short, single conversation can therefore require more memory when either setting increases. The page exposes its arithmetic so users can see which component changes the estimate. These are planning estimates, rather than benchmark results proving that a particular deployment will fit or achieve a given speed.
Terms in this piece · Glossary
Large language model — A model trained on large amounts of data to process and generate language.
attention — The mechanism that lets a model weigh which earlier words matter for the word it's currently processing — the core operation of a transformer.
Context and context window — Context is the information available for a generation; the context window is the capacity available to hold it.
KV cache — The memory a model keeps about text it has already read, so generating each new token doesn't require reprocessing the whole conversation.