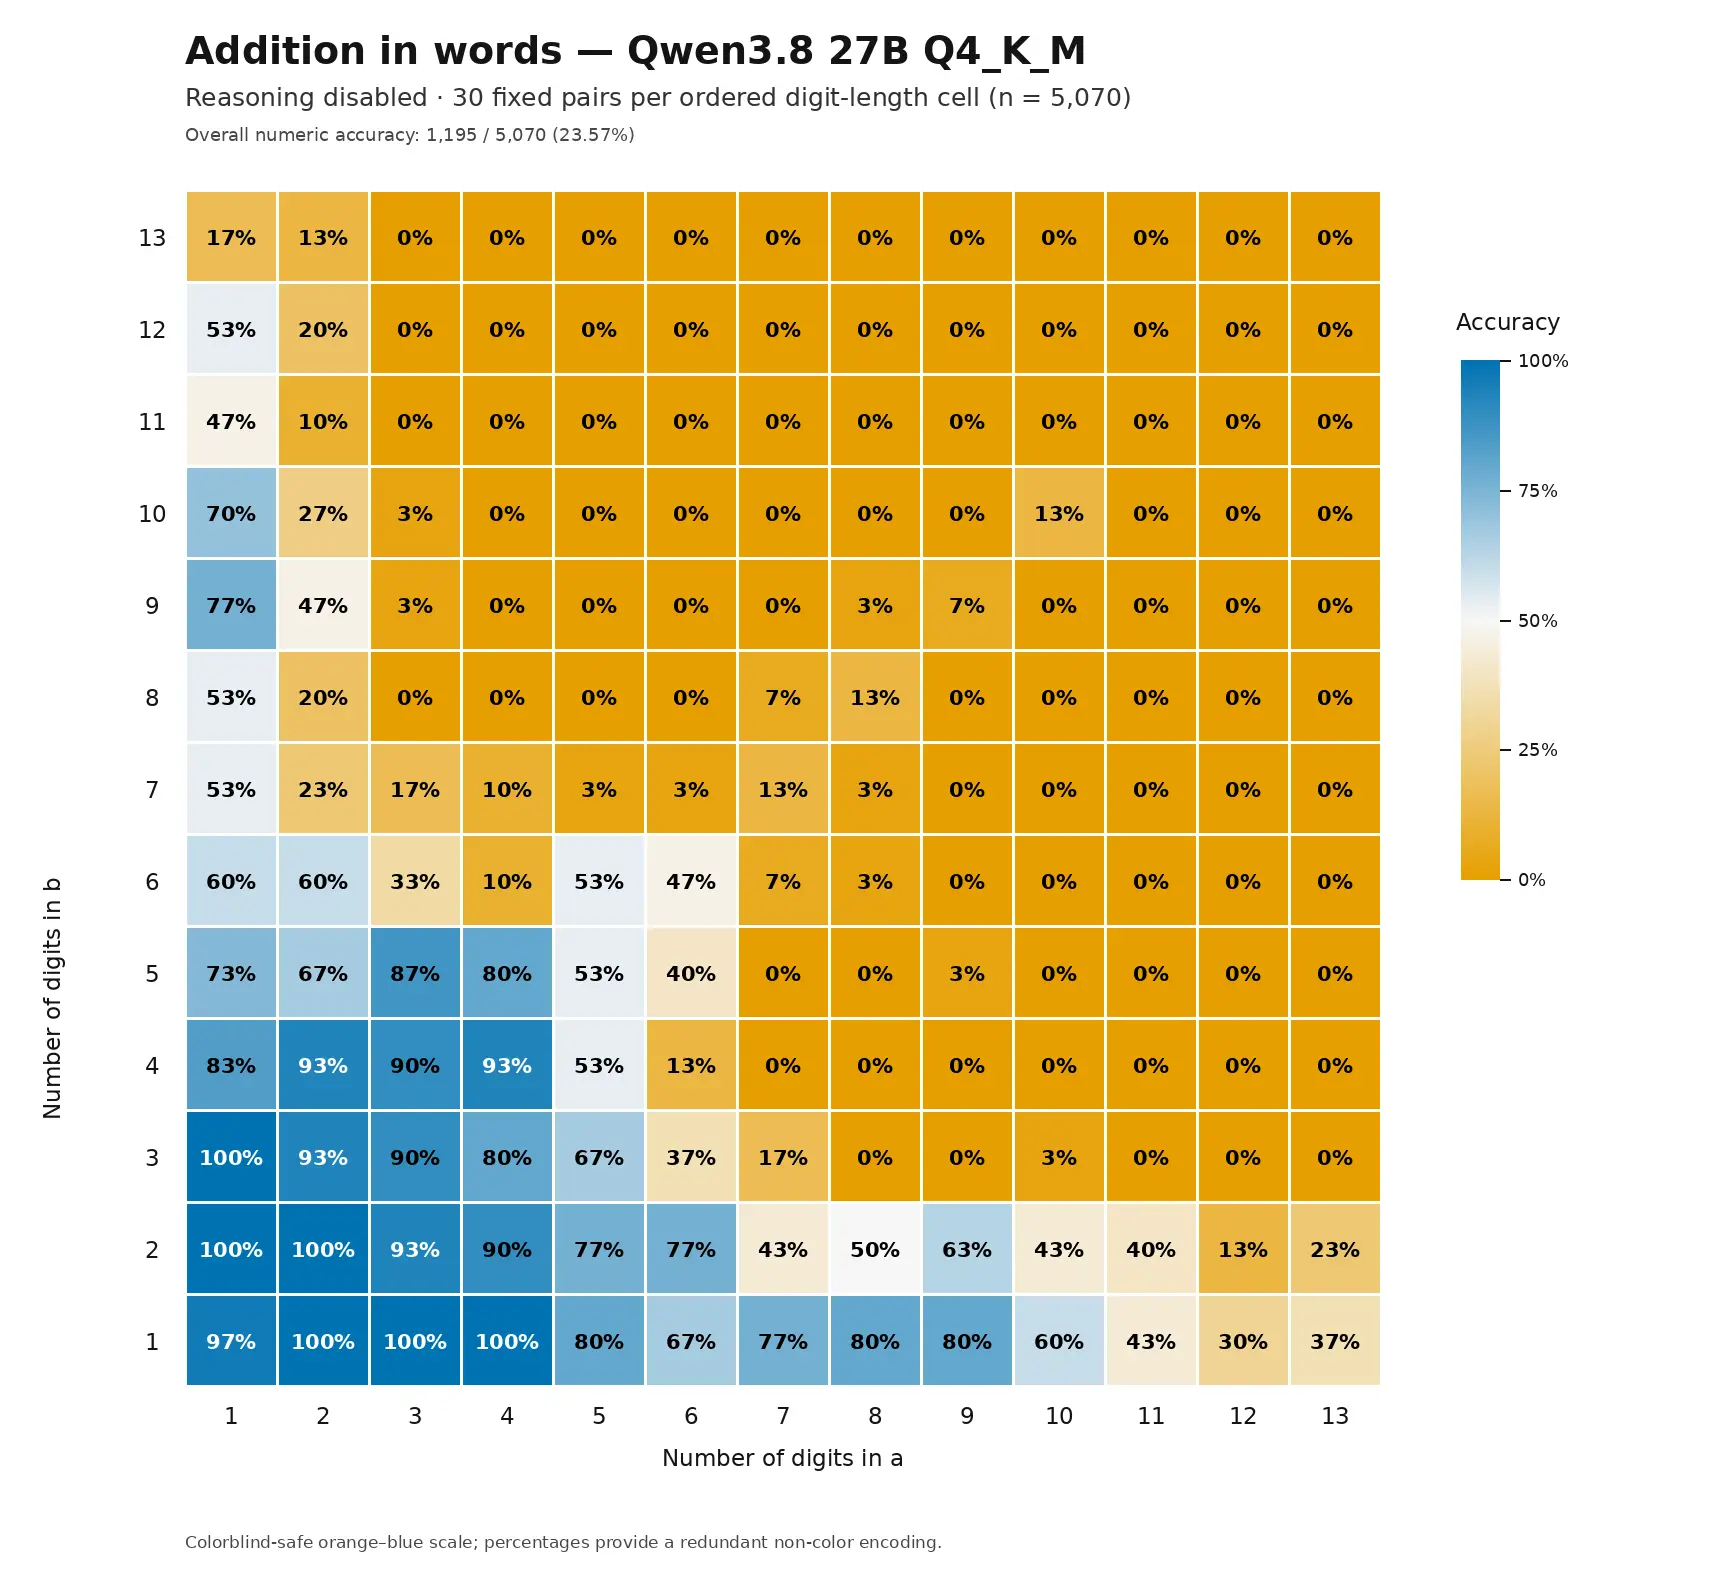
Shows where a local 27B model's arithmetic breaks down, and how reasoning mode changes it, with exact accuracy figures by operand length. Useful when deciding if a local model needs a calculator tool.
Key takeaways · AI-distilled
Simon Willison reran Colin Frasier's GPT-4o-era experiment on a DGX Spark, having a Codex session test a Q4_K_M-quantizationShrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.Full definition → Qwen3.8-27B with 30 attempts per operand-size combination and reasoning disabled.
Without reasoning the model gave the numerically correct sum in words only 23.57% of the time across 5,070 cases, even though 96.17% of its answers followed the required words-only format.
With medium reasoning it was right on 167 of 169 attempts, but Willison ran one sample per combination rather than 30 and expects a second one-shot run would produce different results.
The reasoning traces show the model aligning both numbers digit by digit and adding right to left with explicit carries, working the sum out longhand before writing it in words.
Terms in this piece · Glossary
quantization — Shrinking a model by storing its numbers less precisely — like rounding — so it runs faster and fits on smaller hardware, at a small quality cost.